efficient MCMC sampling
 Maxime Vono, Daniel Paulin and Arnaud Doucet recently arXived a paper about a regularisation technique that allows for efficient sampling from a complex posterior which potential function factorises as a large sum of transforms of linear projections of the parameter θ
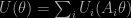
The central idea in the paper [which was new to me] is to introduce auxiliary variates for the different terms in the sum, replacing the projections in the transforms, with an additional regularisation forcing these auxiliary variates to be as close as possible from the corresponding projection

This is only an approximation to the true target but it enjoys the possibility to run a massive Gibbs sampler in quite a reduced dimension. As the variance ρ of the regularisation term goes to zero the marginal posterior on the parameter θ converges to the true posterior. The authors manage to achieve precise convergence rates both in total variation and in Wasserstein distance.
From a practical point of view, only judging from the logistic example, it is hard to fathom how much this approach improves upon other approaches (provided they still apply) as the impact of the value of ρ should be assessed on top of the convergence of the high-dimensional Gibbs sampler. Or is there an annealing version in the pipe-line? While parallelisation is a major argument, it also seems that the Gibbs sampler need a central monitoring for each new simulation of θ. Unless some asynchronous version can be implemented.
June 29, 2019 at 4:26 pm
Thanks for commenting on our paper. The main goal of this work is to provide a theoretical explanation for the good empirical performance of this type of algorithms (first introduced independently by Rendell, Johansen, Lee & Whiteley and Maxime, Dobigeon and Chainais), although we also propose therein a useful methodological extension.
As you explained in your post, the state space for is extended by auxiliary variables
 and the joint log-likelihood is defined as
 where
 is a regularisation parameter. When
 , the marginal of theta tends to the original target. Split Gibbs Sampling proceeds by updating
 conditioned on
 , and then
 conditioned on
 .
The mixing and approximation error results in this paper show how the parameter governs the trade-off between faster mixing (when
 is large) and lower bias for the Gibbs sampler (when
 is small). An interesting feature of these bounds is that they only depend on the strong convexity constants of the potentials
 and neither require differentiability nor smoothness, hence they are applicable to problems with non-differentiable priors (e.g. our image inpainting example).
We would like to emphasize that the running times reported in the paper are for an implementation of the algorithm on a serial computer. Even implemented on a serial computer, the algorithm provides state-of-the-art results for both high-dimensional logistic regression (d=784) and image inpainting. This is in agreement with earlier empirical results reported for such algorithms.
Maxime, Daniel and Arnaud