delayed acceptance [alternative]
In a comment on our Accelerating Metropolis-Hastings algorithms: Delayed acceptance with prefetching paper, Philip commented that he had experimented with an alternative splitting technique retaining the right stationary measure: the idea behind his alternative acceleration is again (a) to divide the target into bits and (b) run the acceptance step by parts, towards a major reduction in computing time. The difference with our approach is to represent the overall acceptance probability
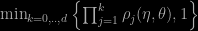
and, even more surprisingly than in our case, this representation remains associated with the right (posterior) target!!! Provided the ordering of the terms is random with a symmetric distribution on the permutation. This property can be directly checked via the detailed balance condition.
In a toy example, I compared the acceptance rates (acrat) for our delayed solution (letabin.R), for this alternative (letamin.R), and for a non-delayed reference (letabaz.R), when considering more and more fractured decompositions of a Bernoulli likelihood.
[sourcecode language=”r” gutter=”false”]
> system.time(source("letabin.R"))
user system elapsed
225.918 0.444 227.200
> acrat
[1] 0.3195 0.2424 0.2154 0.1917 0.1305 0.0958
> system.time(source("letamin.R"))
user system elapsed
340.677 0.512 345.389
> acrat
[1] 0.4045 0.4138 0.4194 0.4003 0.3998 0.4145
> system.time(source("letabaz.R"))
user system elapsed
49.271 0.080 49.862
> acrat
[1] 0.6078 0.6068 0.6103 0.6086 0.6040 0.6158
[/sourcecode]
A very interesting outcome since the acceptance rate does not change with the number of terms in the decomposition for the alternative delayed acceptance method… Even though it logically takes longer than our solution. However, the drawback is that detailed balance implies picking the order at random, hence loosing on the gain in computing the cheap terms first. If reversibility could be bypassed, then this alternative would definitely get very appealing!
November 15, 2014 at 2:29 am
Hi again, one more comment (not specifically related to yesterday’s comment). The motivation behind the acceptance probability min_{k=0,..,d}{prod_{j=1:k} rho_j,1} is a dynamic decision process to boost (acceptance rate) /(# of computed factors). Roughly speaking, you want to reject the current proposal as soon as you think the current proposal is less likely to be accepted than the next proposal. The above acceptance probability is as close as I could get to that criterion while still satisfying detailed balance.
Thanks again for revisiting this!
Philip
November 15, 2014 at 11:18 am
Thanks again. We are currently revising the paper towards submitting to a new journal and we will include references to your solution. Can you please let me know how you would like to be quoted on this?
November 13, 2014 at 11:38 pm
Just remembered the algebra that combines the approaches!
In the decomposition, let the rho_i (i=1:c) be the cheap factors to compute, phi_i (i=1:d) be the expensive factors. I.e., [pi*q(theta->eta)]/pi*q(eta->theta)]= [Prod{rho}]*[Prod{phi}].
Take as acceptance probability:
min_(j=1:c){1,Prod_(i=1:j){rho_i}} * min_(k=1:d){1,Prod_(i=1:k){phi_i}}. You get to compute the cheap terms first, expensive terms last, but there is still a symmetry requirement on ordering of the set of cheap terms, and a symmetry requirement on the set of expensive terms. I have algebra that (appears to) confirm that this satisfies detailed balance, but it is too cumbersome to type here.
Cheers,
Philip
November 14, 2014 at 11:47 am
Thank you Philip. Without checking anything yet (!), I am surprised at managing to keep the cheap versus expensive separation and yet achieving detailed balance.
November 13, 2014 at 6:40 pm
I’m glad I spotted this post in your archives! I played around with some algebra that suggests the two splitting techniques can be combined. Hopefully, when I get home from work I can try to recall that algebra :)