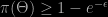Archive for adversarial learning

SEINE AI

Posted in pictures, Statistics, University life with tags , , , , , , , , , , , , , , , , , , , , , , on March 23, 2026 by xi'an

Ten days ago I took part in the SEINE AI 2026 workshop in Jouy-en-Josas, near Paris (homestead of HEC), organised by the Huawei Paris Research Center.. In which I was invited to speak, even though I felt sort of an outlier given the deeply machine-learning, entreprenarial orientation of the meeting, with its theme being Building the Agentic Future of ICT, given that I chose to present our most recent Bayesian adversarial privacy paper. Hence, I stood within a game-theoretic, Bayesian, formal landscape, presumably loosing most of the audience and keeping them away from their lunch!

Other speakers included Simon Lucas from Queen Mary London on Simulation-based AI, which I had trouble distinguishing from building a statistical model by goodness of fit (and using bandits used for update), while focussing on competing on some computer game challenges. And Volker Tresp from LMU München on a tensor brain model that he opposes to a Bayesian brain (with a related paper entitled Bayes or Heisenberg: Who(se) rules? which we discussed in general terms over lunch, namely Bayesian learning vs. quantum updating. And Michal Valko from INRIA Paris (and other companies), who went full blast against the Bradley-Terry model!, with a title of Nash and Nemirovski walk into a bar! With a half-time technique approximating Nash equilibria that reminded me of leapfrog. Much entertaining talk that further provided a game-theoretic transition to mine’s.

As an aside, I played yesterday with ChatGPT composing my talk slides out of our arXiv document and it proved a disaster, with hallucinations of results and concepts not in the paper and a complete mess of handling graphs, first creating generic, fake, unrelated pictures, then inserting actual graphs haphazardly throughout the slides. The sorry result I obviously did not use as the workshop did not seem the ideal place for this sort of prank! The actual version only recycles a few of its summarising slides. (With ye Norse farce proper colour choice!)


Bayesian, adversarial, oceanic, privacy

Posted in Books, Statistics, University life with tags , , , , , , , , , , , , , , , , , , , , , , , on March 6, 2026 by xi'an

We just arXived a new paper on Bayesian privacy! We meaning Cameron Bell, Antoine Luciano, Timothy Johnston and myself, as members of my ERC OCEAN lab at PariSanté and Paris Dauphine. While sharing the same ground as my recent paper with James Bailie, Joshua Bon and Judith Rousseau, this one is definitely more mainstream Bayesian in that the entire decision process falls under the Bayesian hat, with the ultimate decision being the choice of the release mechanism by the data holder (or hoarder!). To rationalise this decision process, we break the framework as resulting from the actions of three actors, namely the data holder, Alice, the data scientist, Bob, and the eavesdropper. Eve. (As in my earlier posts on solving Le Monde’s math puzzles, we could have used pronouns from other cultures, but I feared this would have confused some of the readers. Incidentally, I found out that the earliest use of the first two pronouns was within the groundbreaking cryptography 1977 paper of Rivest, Shamir and Adleman, bringing the RSA algorithm to the World! With Eve appearing in an early, highly-cited privacy paper by Montréal’s Bennett, Brassard, and (unconnected to me!) Robert, in 1988.)

We thus consider a Bayesian setting in which, given data x, held by Alice, inference is to be performed by Bob on a parameter θ. Performing such inference requires Alice releasing information derived from x, which may contain sensitive content, exploited by Eve. Our approach is to compare Alice’s release mechanisms according to both the quality of inference on θ (from Bob’s viewpoint) and the privacy leakage regarding x (sought by Eve and dreaded by Alice). To formalise this evaluation, we posit that Alice refers to a loss function that is a linear combination of Bob’s and Eve’s losses, the weight on Eve’s loss being then negative. (An alternative to be considered in future work is Alice using a ratio of Bob’s and Eve’s losses, possibly set to different powers, the rationale being that a zero loss for Eve is intolerable for Alice.) As in Bayesian experimental design, a prior on the data is necessary for Eve to infer on the hidden data based on the release mechanism and released output and for Alice to evaluate the risk of said release mechanism . (They may differ, as long as they are both made public.) To calibrate Alice’s loss, we opted for a balance that returns the same risk for a full data release and a total lack of release. In specific, informed, settings, other weights could be chosen. While finding the optimal release strategy is impossible but for highly discrete settings, the framework obviously allows for the ranking of natural strategies like insufficient statistics and synthetic datasets. Comments welcome!

Bayesian differential privacy for free?

Posted in Books, pictures, Statistics with tags , , , , , , , , , , , , on September 24, 2023 by xi'an

“We are interested in the question of how we can build differentially-private algorithms within the Bayesian framework. More precisely, we examine when the choice of prior is sufficient to guarantee differential privacy for decisions that are derived from the posterior distribution (…) we show that the Bayesian statistician’s choice of prior distribution ensures a base level of data privacy through the posterior distribution; the statistician can safely respond to external queries using samples from the posterior.”

Recently I came across this 2016 JMLR paper of Christos Dimitrakakis et al. on “how Bayesian inference itself can be used directly to provide private access to data, with no modification.” Which comes as a surprise since it implies that Bayesian sampling would be enough, per se, to keep both the data private and the information it conveys available. The main assumption on which this result is based is one of Lipschitz continuity of the model density, namely that, for a specific (pseudo-)distance ρ

|\log f(x|\theta)-\log f(y|\theta)|\le L\rho(x,y)

uniformly in θ over a set Θ with enough prior mass

\pi(\Theta)\ge 1-e^{-\epsilon}

for an ε>0. In this case, the Kullback-Leibler divergence between the posteriors π(θ|x) and π(θ|y) is bounded by a constant times ρ(x,y). (The constant being 2L when Θ is the entire parameter space.) This condition ensures differential privacy on the posterior distribution (and even more on the associated MCMC sample). More precisely, (2L,0)-differentially private in the case Θ is the entire parameter space. While there is an efficiency issue linked with the result since the bound L being set by the model and hence immovable, this remains a fundamental result for the field (as shown by its high number of citations).