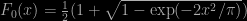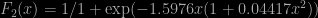Archive for logistic regression

simulated annealing and logistic regression to the max

Posted in Kids, R, Statistics with tags , , , , , , on April 26, 2023 by xi'an

A Riddler puzzle on the three binary and sequential questions one should ask three players hiding their respective U(0,1) realisation, U, V, and W, to best guess which player holds the largest number, max{U,V,W}. Assuming questions of the type Is U<b¹, &tc., the challenge boils down to selecting seven bounds (one for U, two for V, and four for W) in order to optimise the probability of picking the right player. Which means for a given collection of such bounds to learn this probability from the three binary answers. These can be turned into eight (2³) binary variables and I used them as entries in a logistic regression to predict that W was larger than max(U,V), itself predicted by the first two answers. The optimisation of the bounds can then be achieved by simulated annealing (or otherwise) and the approach returns (random) outputs like the following bounds (one on U, two on V, and four on W)

0.616 0.434 0.830 0.350 0.736 0.913 0.796 0.827

for an estimated probability of 0.827. This is a somewhat coherent sequence of bounds when considering the simpler case of two players. Indeed, with three bounds, the probability of winning can be readily derived as

b^2(b^1-b^2)+1/2+b^3(1-b^2+b^1)-b^1b^1

logically optimised by (b¹,b²,b³)=(1/2,1/4,3/4) for a success probability of 0.875. And it coïncides with the solution posted by The Riddler, although there is no intuition behind the figures, contrary to the two player situation. In fact, I am surprised that the bound on W does not equate the expectation of max{U,V} under the current conditions:

> x=runif(1e6,0,.616);y=runif(1e6,0,.434)
> mean(y+(x-y>0)*(x-y))
[1] 0.3591648

moralizing gods drive Nature rejection

Posted in Statistics with tags , , , , , , , on August 29, 2021 by xi'an

on approximations of Φ and Φ⁻¹

Posted in Books, Kids, R, Statistics with tags , , , , , , , , , on June 3, 2021 by xi'an

As I was working on a research project with graduate students, I became interested in fast and not necessarily very accurate approximations to the normal cdf Φ and its inverse. Reading through this 2010 paper of Richards et al., using for instance Polya’s

F_0(x) =\frac{1}{2}(1+\sqrt{1-\exp(-2x^2/\pi)})

(with another version replacing 2/π with the squared root of π/8) and

F_2(x)=1/1+\exp(-1.5976x(1+0.04417x^2))

not to mention a rational faction. All of which are more efficient (in R), if barely, than the resident pnorm() function.

      test replications elapsed relative user.self 
3 logistic       100000   0.410    1.000     0.410 
2    polya       100000   0.411    1.002     0.411 
1 resident       100000   0.455    1.110     0.455 

For the inverse cdf, the approximations there are involving numerical inversion except for

F_0^{-1}(p) =(-\pi/2 \log[1-(2p-1)^2])^{\frac{1}{2}}

which proves slightly faster than qnorm()

       test replications elapsed relative user.self 
2 inv-polya       100000   0.401    1.000     0.401
1  resident       100000   0.450    1.000     0.450

Metropolis-Hastings via Classification [One World ABC seminar]

Posted in Statistics, University life with tags , , , , , , , , , , , , , , , on May 27, 2021 by xi'an

Today, Veronika Rockova is giving a webinar on her paper with Tetsuya Kaji Metropolis-Hastings via classification. at the One World ABC seminar, at 11.30am UK time. (Which was also presented at the Oxford Stats seminar last Feb.) Please register if not already a member of the 1W ABC mailing list.

reXing the bridge

Posted in Books, pictures, Statistics with tags , , , , , , , , , on April 27, 2021 by xi'an

As I was re-reading Xiao-Li  Meng’s and Wing Hung Wong’s 1996 bridge sampling paper in Statistica Sinica, I realised they were making the link with Geyer’s (1994) mythical tech report, in the sense that the iterative construction of α functions “converges to the `reverse logistic regression’  described in Geyer (1994) for the two-density cases” (p.839). Although they also saw the later as an “iterative” application of Torrie and Valleau’s (1977) “umbrella sampling” estimator. And cited Bennett (1976) in the Journal of Computational Physics [for which Elsevier still asks for $39.95!] as the originator of the formula [check (6)]. And of the optimal solution (check (8)). Bennett (1976) also mentions that the method fares poorly when the targets do not overlap:

“When the two ensembles neither overlap nor satisfy the above smoothness condition, an accurate estimate of the free energy cannot be made without gathering additional MC data from one or more intermediate ensembles”

in which case this sequence of intermediate targets could be constructed and, who knows?!, optimised. (This may be the chain solution discussed in the conclusion of the paper.) Another optimisation not considered in enough detail is the allocation of the computing time to the two densities, maybe using a bandit strategy to avoid estimating the variance of the importance weights first.