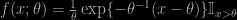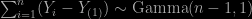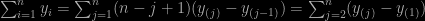Archive for exponential distribution

simulating Gumbel’s bivariate exponential distribution

Posted in Books, Kids, R, Statistics with tags , , , , , , , , , , on January 14, 2024 by xi'an

A challenge interesting enough for a sunny New Year morn, found on X validated, namely the simulation of a bivariate exponential distribution proposed by Gumbel in 1960, with density over the positive quadrant in IR²

{}^{ [(\lambda_2+rx_1)(\lambda_1+rx_2)-r]\exp[-(\lambda_1x_1+\lambda_2x_2+rx_1x_2)]}

Although there exists a direct approach based on the fact that the marginals are Exponential distributions and the conditionals signed mixtures of Gamma distributions, an accept-reject algorithm is also available for the pair, with a dominating density representing a genuine mixture of four Gammas, when omitting the X product in the exponential and the negative r in the first term. The efficiency of this accept-reject algorithm is high for r small. However, and in more direct connection with the original question, using this approach to integrate the function equal to the product of the pair, as considered in the original paper of Gumbel, is much less efficient than seeking a quasi-optimal importance function, since this importance function is yet another mixture of four Gammas that produces a much reduced variance at a cheaper cost!

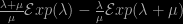
max vs. min

Posted in Books, Kids, Statistics with tags , , , , , , , , on March 26, 2022 by xi'an

Another intriguing question on X validated (about an exercise in Jun Shao’s book) that made me realise a basic fact about exponential distributions. When considering two Exponential random variables X and Y with possibly different parameters λ and μ,  Z⁺=max{X,Y} is dependent on the event X>Y while Z⁻=min{X,Y} is not (and distributed as an Exponential variate with parameter λ+μ.) Furthermore, Z⁺ is distributed from a signed mixture

\frac{\lambda+\mu}{\mu}\mathcal Exp(\lambda)-\frac{\lambda}{\mu}\mathcal Exp(\lambda+\mu)

conditionally on the event X>Y, meaning that there is no sufficient statistic of fixed dimension when given a sample of n realisations of Z⁺’s along with the indicators of the events X>Y…. This may explain why there exists an unbiased estimator of λ⁻¹-μ⁻¹ in this case and (apparently) not when replacing Z⁺ by Z⁻. (Even though the exercise asks for the UMVUE.)

R rexp()

Posted in Books, R, Statistics with tags , , , , , , , on May 18, 2021 by xi'an

Following a question on X validated about the reasons for coding rexp() following Ahrens & Dieter (1972) version, I re-read Luc Devroye’s explanations. Which boils down to an optimised implementation of von Neumann’s Exponential generator. The central result is that, for any μ>0, M a Geometric variate with failure probability exp(-μ) and Z a positive Poisson variate with parameter μ

\mu(M+\min(U_1,\ldots,U_Z))

is distributed as an Exp(1) random variate. Meaning that for every scale μ, the integer part and the fractional part of an Exponential variate are independent, the former a Geometric. A refinement of the above consists in choosing

exp(-μ) =½

as the generation of M then consists in counting the number of 0’s before the first 1 in the binary expansion of U∼U(0,1). Actually the loop used in Ahrens & Dieter (1972) seems to be much less efficient than counting these 0’s

> benchmark("a"={u=runif(1)
    while(u<.5){
     u=2*u
     F=F+log(2)}},
  "b"={v=as.integer(rev(intToBits(2^31*runif(1))))
     sum(cumprod(!v))},
  "c"={sum(cumprod(sample(c(0,1),32,rep=T)))},
  "g"={rgeom(1,prob=.5)},replications=1e4)
  test elapsed relative user.self 
1    a  32.92  557.966    32.885
2    b  0.123    2.085     0.122
3    c  0.113    1.915     0.106
4    g  0.059    1.000     0.058

Obviously, trying to code the change directly in R resulted in much worse performances than the resident rexp(), coded in C.

on completeness

Posted in Books, Kids, Statistics with tags , , , , , , on November 19, 2020 by xi'an

Another X validated question that proved a bit of a challenge, enough for my returning to its resolution on consecutive days. The question was about the completeness of the natural sufficient statistic associated with a sample from the shifted exponential distribution

f(x;\theta) = \frac{1}{\theta^2}\exp\{-\theta^{-2}(x-\theta)\}\mathbb{I}_{x>\theta}

[weirdly called negative exponential in the question] meaning the (minimal) sufficient statistic is made of the first order statistic and of the sample sum (or average), or equivalently

T=(X_{(1)},\sum_{i=2}^n \{X_{(i)}-X_{(1)}\})

Finding the joint distribution of T is rather straightforward as the first component is a drifted Exponential again and the second a Gamma variate with n-2 degrees of freedom and the scale θ². (Devroye’s Bible can be invoked since the Gamma distribution follows from his section on Exponential spacings, p.211.) While the derivation of a function with constant expectation is straightforward for the alternate exponential distribution

f(x;\theta) = \frac{1}{\theta}\exp\{-\theta^{-1}(x-\theta)\}\mathbb{I}_{x>\theta}

since the ratio of the components of T has a fixed distribution, it proved harder for the current case as I was seeking a parameter free transform. When attempting to explain the difficulty on my office board, I realised I was seeking the wrong property since an expectation was enough. Removing the dependence on θ was simpler and led to

\mathbb E_\theta\left[\frac{X_{(1)}}{Y}-\frac{\Gamma(n-2)}{\Gamma(n-3/2)}Y^\frac{-1}{2}\right]=\frac{\Gamma(n-2)}{n\Gamma(n-1)}

but one version of a transform with fixed expectation. This also led me to wonder at the range of possible functions of θ one could use as scale and still retrieve incompleteness of T. Any power of θ should work but what about exp(θ²) or sin²(θ³), i.e. functions for which there exists no unbiased estimator..?

an elegant result on exponential spacings

Posted in Statistics with tags , , , , , , , , , , , , , on April 19, 2017 by xi'an

A question on X validated I spotted in the train back from Lyon got me desperately seeking a reference in Devroye’s Generation Bible despite the abyssal wireless and a group of screeching urchins a few seats away from me… The question is about why

\sum_{i=1}^{n}(Y_i - Y_{(1)}) \sim \text{Gamma}(n-1, 1)

when the Y’s are standard exponentials. Since this reminded me immediately of exponential spacings, thanks to our Devroye fan-club reading group in Warwick,  I tried to download Devroye’s Chapter V and managed after a few aborts (and a significant increase in decibels from the family corner). The result by Sukhatme (1937) is in plain sight as Theorem 2.3 and is quite elegant as it relies on the fact that

\sum_{i=1}^n y_i=\sum_{j=1}^n (n-j+1)(y_{(j)}-y_{(j-1)})=\sum_{j=2}^n (y_{(j)}-y_{(1)})

hence sums up as a mere linear change of variables! (Pandurang Vasudeo Sukhatme (1911–1997) was an Indian statistician who worked on human nutrition and got the Guy Medal of the RSS in 1963.)