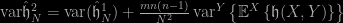Archive for cosmostats

to the early Universe and back

Posted in Books, pictures, Statistics, Travel, University life with tags , , , , , , , , , , , , , , , , , , , on November 16, 2025 by xi'an

On 28 October, I spent the day at Institut d’Astrophysique de Paris (where I used to work on PMC for cosmology between 2005 and 2009), as a committee member for the habilitation defence of Florent Leclercq. Not only it was nice to be back in this unique institution (with vestiges from Laplace’s era), but this was a fantastic habilitation, with a superb thesis that beautifully gathered the different fields mastered by the candidate in a highly coherent discourse. And could serve as an introduction to cosmostatistics for many.

And provided the background to ten years (post-PhD) of research on forward modelling in cosmology and resulting Bayesian statistical analysis either by implicit likelihood (or likelihood-free) inference or by field-level inference. He describes the Simbelmynë software he developed to produce maps of the density field and analyse dark matter dynamics. Ẁhose name is borrowed from Tolkien (along with a quote from Guy Gavriel Kay!):

“How fair are the bright eyes in the grass! Evermind they are called, simbelmynë in this land of Men, for they blossom in all the seasons of the year, and grow where dead men rest.” — J.R.R. Tolkien, The Lord of the Ring

And the Bayesian computational and modelling tools he elaborated, like SELFI (Simulator expansion for likelihood-free inference, Leclercq et al., 2019), that relates to Michael Gutmann’s and Juka Corander’s BOLFI. (Obviously, I did not get every aspect right from just reading the thesis and attending the lecture, in particular the remarks on using SELFI to assess model misspecification. But I remain impressed by the scope of the work and its likely impact on the field!)

Natural nested sampling

Posted in Books, Statistics, University life with tags , , , , , , , , , , , on May 28, 2023 by xi'an

“The nested sampling algorithm solves otherwise challenging, high-dimensional integrals by evolving a collection of live points through parameter space. The algorithm was immediately adopted in cosmology because it partially overcomes three of the major difficulties in Markov chain Monte Carlo, the algorithm traditionally used for Bayesian computation. Nested sampling simultaneously returns results for model comparison and parameter inference; successfully solves multimodal problems; and is naturally self-tuning, allowing its immediate application to new challenges.”

I came across a review on nested sampling in Nature Reviews Methods Primers of May 2022, with a large number of contributing authors, some of whom I knew from earlier papers in astrostatistics. As illustrated by the above quote from the introduction, the tone is definitely optimistic about the capacities of the method, reproducing the original argument that the evidence is the posterior expectation of the likelihood L(θ) under the prior. Which representation, while valid, is not translating into a dimension-free methodology since parameters θ still need be simulated.

“Nested sampling lies in a class of algorithms that form a path of bridging distributions and evolves samples along that path. Nested sampling stands out because the path is automatic and smooth — compression along log X by, on average, 1/𝑛at each iteration — and because along the path is compressed through constrained priors, rather than from the prior to the posterior. This was a motivation for nested sampling as it avoids phase transitions — abrupt changes in the bridging distributions — that cause problems for other methods, including path samplers, such as annealing.”

The elephant in the room is eventually processed, namely the simulation from the prior constrained to the likelihood level sets that in my experience (with, e.g., mixture posteriors) proves most time consuming. This stems from the fact that these level sets are notoriously difficult to evaluate from a given sample: all points stand within the set but they hardly provide any indication of the boundaries of saif set… Region sampling requires to construct a region that bounds the likelihood level set, which requires some knowledge of the likelihood variations to have a chance to remain efficient, incl. in cosmological applications, while regular MCMC steps require an increasing number of steps as the constraint gets tighter and tighter. For otherwise it essentially amounts to duplicating a live particle.

ABC in Clermont-Ferrand

Posted in Mountains, pictures, Statistics, Travel, University life with tags , , , , , , , , , , , on September 20, 2019 by xi'an

Today I am taking part in a one-day workshop at the Université of Clermont Auvergne on ABC. With applications to cosmostatistics, along with Martin Kilbinger [with whom I worked on PMC schemes], Florent Leclerc and Grégoire Aufort. This should prove a most exciting day! (With not enough time to run up Puy de Dôme in the morning, though.)

simulated summary statistics [in the sky]

Posted in Statistics with tags , , , , , , , on October 10, 2018 by xi'an

Thinking it was related with ABC, although in the end it is not!, I recently read a baffling cosmology paper by Jeffrey and Abdalla. The data d there means an observed (summary) statistic, while the summary statistic is a transform of the parameter, μ(θ), which calibrates the distribution of the data. With nuisance parameters. More intriguing to me is the sentence that the correct likelihood of d is indexed by a simulated version of μ(θ), μ'(θ), rather than by μ(θ). Which seems to assume that the pseudo- or simulated data can be produced for the same value of the parameter as the observed data. The rest of the paper remains incomprehensible for I do not understand how the simulated versions are simulated.

“…the corrected likelihood is more than a factor of exp(30) more probable than the uncorrected. This is further validation of the corrected likelihood; the model (i.e. the corrected likelihood) shows a better goodness-of-fit.”

The authors further ressort to Bayes factors to compare corrected and uncorrected versions of the likelihoods, which leads (see quote) to picking the corrected version. But are they comparable as such, given that the corrected version involves simulations that are treated as supplementary data? As noted by the authors, the Bayes factor  unsurprisingly goes to one as the number M of simulations grows to infinity, as supported by the graph below.

an interesting identity

Posted in Books, pictures, Statistics, University life with tags , , , , , , , , on March 1, 2018 by xi'an

Another interesting X validated question, another remembrance of past discussions on that issue. Discussions that took place in the Institut d’Astrophysique de Paris, nearby this painting of Laplace, when working on our cosmostats project. Namely the potential appeal of recycling multidimensional simulations by permuting the individual components in nearly independent settings. As shown by the variance decomposition in my answer, when opposing N iid pairs (X,Y) to the N combinations of √N simulations of X and √N simulations of Y, the comparison

\text{var} \hat{\mathfrak{h}}^2_N=\text{var} (\hat{\mathfrak{h}}^1_N)+\frac{mn(n-1)}{N^2}\,\text{var}^Y\left\{ \mathbb{E}^{X}\left\{\mathfrak{h}(X,Y)\right\}\right\}

+\frac{m(m-1)n}{N^2}\,\text{var}^X\left[\mathbb{E}^Y\left\{\mathfrak{h}(X,Y)\right\}\right]

unsurprisingly gives the upper hand to the iid sequence. A sort of converse to Rao-Blackwellisation…. Unless the production of N simulations gets much more costly when compared with the N function evaluations. No wonder we never see this proposal in Monte Carlo textbooks!