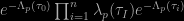Archive for missing species problem

JSM 2024, Portland, Day 3

Posted in pictures, Running, Statistics, Travel, University life with tags , , , , , , , , , , , , , , , , , , , , , , , , , , , , , , , , , , on August 9, 2024 by xi'an

Bayesian contributed session as the first round of the third day (with a choice of five parallel sessions featuring Bayesian topics!!, actually easier to pick than among the following eight parallel sessions of the 10:30 schedule!!!), with a talk by Tahir Ekin on adversarial outlier detection that could connect with our Oceaner(c) privacy concerns. Then one involving spike & slab (a theme to figure prominently in this special day!!) in mixed response models by Sameer Deshpande, seeking a (unBayesian!) MAP for a latent variable model by Monte Carlo EM. Followed by a talk by Yunyi Shen on completely random measures for estimating the (distribution of the) number of species in heterogeneous populations. Next, Valentin Zulj on (frequentist rather than) Bayesian stacking, on estimating optimal weights for model averaging (which should be posterior probabilities in a pure Bayesian mindframe), including a score function that could lead to generalised Bayesian inference on said weights. Finishing with a talk by Chaegeun Song on correcting Bayesian credible sets towards (frequentist, again!!!) exact coverage for classification (which reminded me of my very first paper with George on correcting frequentist confidence for Binomial observations). With which I could not really engage as seeking a specific coverage level did not seem relevant, imho, but I appreciated the wheel plot representation.My second morn session was about modern (what else?!) sampling algorithms, although I spent the first dozen minutes wondering whether or not I had entered the wrong room. Until Tianhao Wang focussed on Thompson sampling for bandits. It did prove far enough from my interest for my (sleep deprived) attention to drift too quickly. Only the talk by Yuchen Wu on a spike & slab (as suits the day!) challenge captured enough this wandering attention. Crossing further into my realm of primary topics by considering a target distribution that is a product of distributions. But I did not get from her presentation how a product measure decomposition was inducing higher efficiency (and did not find answers within the arXived preprint). Unless it exploited specific features of the target, like conditional independence between the components. The last talk was by Brice Huang on sampling low temperature Gibbs measures using stochastic localisation.

After coming upon a row of food trucks across the conference centre and being unfairly attracted by an Ethiopian injera picture into a terrible wrap, I returned for the Skeptical about AI session, just a few minutes late, only to find accessing the session was impossible! Quite sad to miss the presentations and the arguments (even though I had heard a previous talk by Genevera Allen when visiting Rutgers two years ago). As a second best, I then joined the recent (of course!) Advances in Bayesian Computation (aka ABC?!) session with a medley of topics, including a data subset versus data sketching model reduction by Sudipto Saha. Which could have consequences on our privacy strategies. And marginal evidence estimation for the Bayesian Lasso by Christopher Hans while avoiding data completion. And another latent variable model with a sequential variational Bayes approach by Bao Anh Vu, using at one point Cappé et al. (2005) EM-based approximation to the log likelihood gradient. Finishing by a back-to-the-future talk by Luke Duttweiler on MCMC convergence diagnostics. Comparing several chains via proximity maps that themselves require some preliminary knowledge about the MCMC kernel. (Nice title though, “the traceplot thickens”!)The crux of the day was however the 2024 COPSS Award ceremony with several friends featuring among the recipients, Danielle Durante for the Emerging Leaders Award, Regina Liu for the Elizabeth L. Scott Award and Veronika Rockova for the Presidents’ Award. Congrats!!!


capture-recapture rediscovered

Posted in Books, Statistics with tags , , , , , , , , , , , , on March 2, 2022 by xi'an

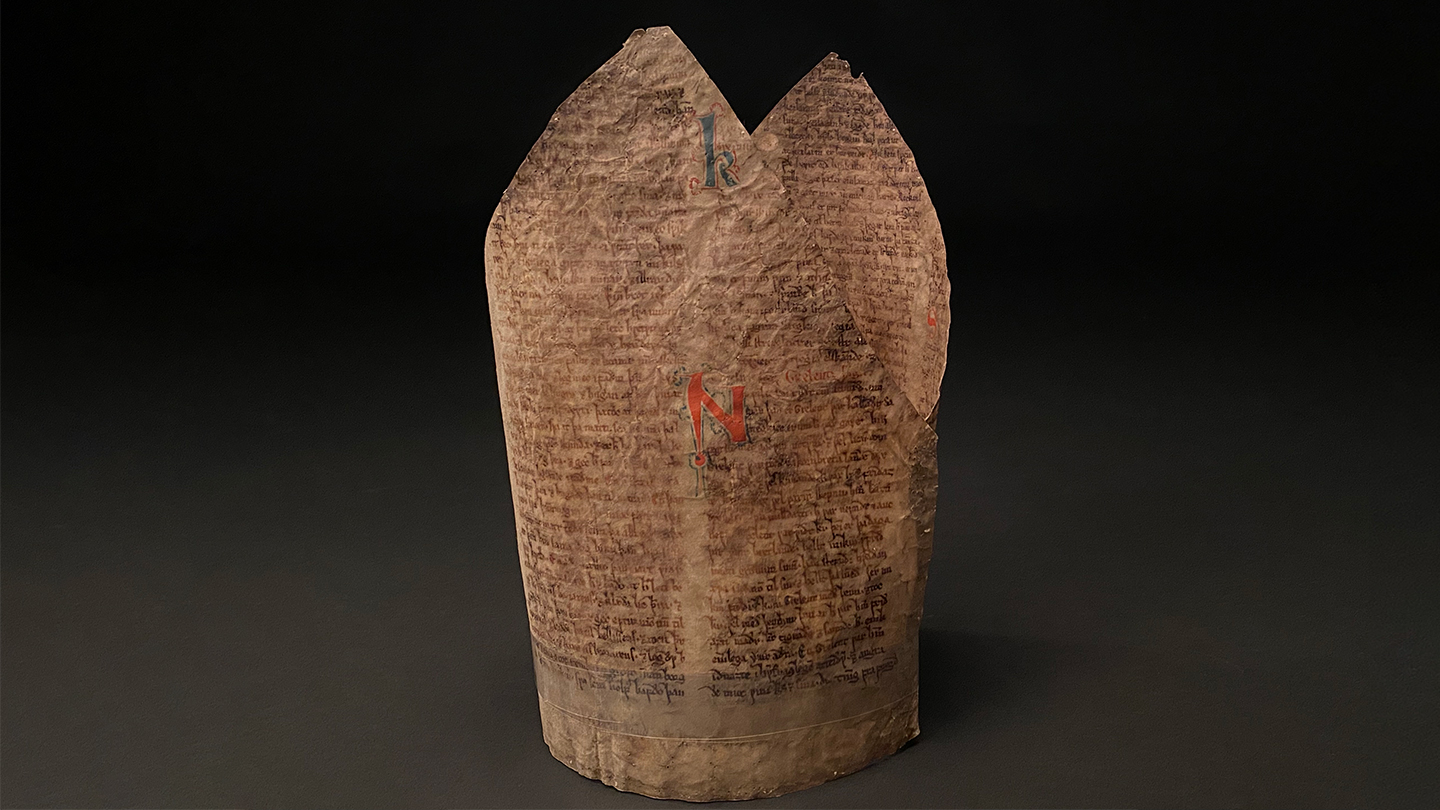
A recent Science paper applies capture-recapture to estimating how much medieval literature has been lost, using ancient lists of works and comparing with the currently know corpus. To deduce at a 91% loss. Which begets the next question of how many ancient lists have been lost! Or how many of the observed ones are sheer copies of the others. First I thought I had no access to the paper so could not comment on the specific data and accounting for the uneven and unrandom sampling behind this modelling… But I still would not share the anti-modelling bias of this Harvard historian, given the superlative record of Anne Chao in capture-recapture methodology!

“The paper seems geared more toward systems theorists and statisticians, says Daniel Smail, a historian at Harvard University who studies medieval social and cultural history, and the authors haven’t done enough to establish why cultural production should follow the same rules as life systems. But for him, the bigger question is: Given that we already have catalogs of ancient texts, and previous estimates were pretty close to the model’s new one, what does the new work add?”

Once at Ca’Foscari, I realised the local network gave me access to the paper. The description of the Chao1 method, as far as I can tell, does not describe how the problematic collection of catalogs where duplicates (recaptures) can be observed is taken into account. For one thing, the collection is far from iid since some catalogs must have built on earlier ones. It is also surprising imho that the authors spend space on discussing unbiasedness when a more crucial issue is the randomness assumption behind the collected data.

Measuring abundance [book review]

Posted in Books, Statistics with tags , , , , , , , , , , , , on January 27, 2022 by xi'an

This 2020 book, Measuring Abundance:  Methods for the Estimation of Population Size and Species Richness was written by Graham Upton, retired professor of applied statistics, for the Data in the Wild series published by Pelagic Publishing, a publishing company based in Exeter.

“Measuring the abundance of individuals and the diversity of species are core components of most ecological research projects and conservation monitoring. This book brings together in one place, for the first time, the methods used to estimate the abundance of individuals in nature.”

Its purpose is to provide a collection of statistical methods for measuring animal abundance or lack thereof. There are four parts: a primer on statistical methods, going no further than maximum likelihood estimation and bootstrap. The term Bayesian only occurs once, in connection with the (a-Bayesian) BIC. (I first spotted a second entry, until I realised this was not a typo and the example truly was about Bawean warty pigs!) The second part is about stationary (or static) individuals, such as trees, and it mostly exposes different recognised ways of sampling, with a focus on minimising the surveyor’s effort. Examples include forestry sampling (with a chainsaw method!) and underwater sampling. There is very little statistics involved in this part apart from the rare appearance of a MLE with an asymptotic confidence interval. There is also very little about misspecified models, except for the occasional warning that the estimates may prove completely wrong. The third part is about mobile individuals, with capture-recapture methods receiving the lion’s share (!). No lion was actually involved in the studies used as examples (but there were grizzly bears from Yellowstone and Banff National Parks). Given the huge variety of capture-recapture models, very little input is found within the book as the practical aspects are delegated to R software like the RMark and mra packages. Very little is written on using covariates or spatial features in such models, mostly dedicated to printed output from R packages with AIC as the sole standard for comparing models. I did not know of distance methods (Chapter 8), which are less invasive counting methods. They however seem to rely on a particular model of missing on individuals as the distance increases. The last section is about estimating the number of species. With again a model assumption that may prove wrong. With the inclusion of diversity measures,

The contents of the book are really down to earth and intended for field data gatherers. For instance, “drive slowly and steadily at 20 mph with headlights and hazard lights on ” (p.91) or “Before starting to record, allow fish time to acclimatize to the presence of divers” (p.91). It is unclear to me how useful the book would prove to be for general statisticians, apart from revealing the huge diversity of methods actually employed in the field. To either build upon these or expose students to their reassessment. More advanced books are McCrea and Morgan (2014), Buckland et al. (2016) and the most recent Seber and Schofield (2019).

[Disclaimer about potential self-plagiarism: this post or an edited version will eventually appear in my Book Review section in CHANCE.]

Naturally amazed at non-identifiability

Posted in Books, Statistics, University life with tags , , , , , , , , , , , on May 27, 2020 by xi'an

A Nature paper by Stilianos Louca and Matthew W. Pennell,  Extant time trees are consistent with a myriad of diversification histories, comes to the extraordinary conclusion that birth-&-death evolutionary models cannot distinguish between several scenarios given the available data! Namely, stem ages and daughter lineage ages cannot identify the speciation rate function λ(.), the extinction rate function μ(.)  and the sampling fraction ρ inherently defining the deterministic ODE leading to the number of species predicted at any point τ in time, N(τ). The Nature paper does not seem to make a point beyond the obvious and I am rather perplexed at why it got published [and even highlighted]. A while ago, under the leadership of Steve, PNAS decided to include statistician reviewers for papers relying on statistical arguments. It could time for Nature to move there as well.

“We thus conclude that two birth-death models are congruent if and only if they have the same rp and the same λp at some time point in the present or past.” [S.1.1, p.4]

Or, stated otherwise, that a tree structured dataset made of branch lengths are not enough to identify two functions that parameterise the model. The likelihood looks like

\frac{\rho^{n-1}\Psi(\tau_1,\tau_0)}{1-E(\tau)}\prod_{i=1}^n \lambda(\tau_i)\Psi(s_{i,1},\tau_i)\Psi(s_{i,2},\tau_i)$

where E(.) is the probability to survive to the present and ψ(s,t) the probability to survive and be sampled between times s and t. Sort of. Both functions depending on functions λ(.) and  μ(.). (When the stem age is unknown, the likelihood changes a wee bit, but with no changes in the qualitative conclusions. Another way to write this likelihood is in term of the speciation rate λp

e^{-\Lambda_p(\tau_0)}\prod_{i=1}^n\lambda_p(\tau_I)e^{-\Lambda_p(\tau_i)}

where Λp is the integrated rate, but which shares the same characteristic of being unable to identify the functions λ(.) and μ(.). While this sounds quite obvious the paper (or rather the supplementary material) goes into fairly extensive mode, including “abstract” algebra to define congruence.


“…we explain why model selection methods based on parsimony or “Occam’s razor”, such as the Akaike Information Criterion and the Bayesian Information Criterion that penalize excessive parameters, generally cannot resolve the identifiability issue…” [S.2, p15]

As illustrated by the above quote, the supplementary material also includes a section about statistical model selections techniques failing to capture the issue, section that seems superfluous or even absurd once the fact that the likelihood is constant across a congruence class has been stated.

Batman at Warwick

Posted in Books, pictures, Statistics, University life with tags , , , , on June 11, 2016 by xi'an

Here is a short video featuring Mark Girolami (Warwick) explaining how to use signal processing and Bayesian statistics to estimate how many bats there are in a dark cave: