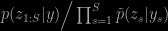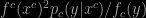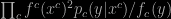Archive for parallel processing

6th Workshop on Sequential Monte Carlo Methods (#2)

Posted in Mountains, pictures, Running, Statistics, Travel, University life with tags , , , , , , , , , , , , , , , , , , , , , , , on June 5, 2024 by xi'an

Managed to get back from the Pentland hills in time for the Wednesday afternoon session, which proved most interesting as close to my research interests!

Nicola Branchini presented his work with Victor Elvira (a close friend and coauthor, incidentally one of the organisers of the workshop!) on improving self normalised importance sampling by interpreting it as a ratio of estimators based on two samples (which may be the same) and attempting to optimise the joint distribution of said sample. The starting assumption is having (good) marginal importance functions, which means the goal here is in optimising a copula distribution targeting the ratio as quantity of interest. Optimality is however defined in terms of the approximate asymptotic variance of the ratio, which remains an approximation. The idea is nonetheless quite interesting and shows potential for connecting with bridge sampling and… AMIS! As an aside, the talk considered cases when the margins are multivariate, which requires a généralisation of Sklar’s theorem. Simo Särkä then demonstrated how highly parallel processors like GPUs can accommodate Bayesian filters and smoothers in state space models not requiring simulation, gaining a reduction in complexity from O(T) to O(log T). I had not really thought of parallel processing in the recent years, hence was quite pleased at hearing this resolution based on so-called associative scans, and see that implementations were already available in Julia/CUDA.

This was followed by a highly enjoyable poster session, including chats about ABC-SMC for discovery rates, infinite dimensional diffusions, Pareto smoothed importance samplings, &tc with posters by Hugo Marival (coauthor of our importance Monte Carlo recent paper) and Shreya Roy (a student at U of Warwick). With sunny views of Arthur’s Seat (and plenty of people at the top), contrary to the above! Followed by a private party dinner occupying half of a nearby and novel South Indian restaurant that proved quite tasty, local and definitely enjoyable.

For my last morning in town, albeit it was unrelated to the posted abstract, Pierre Del Moral spoke about noisy versions of the ensemble Kalman filter on linear diffusions that allowed for stable solutions under strong enough conditions, encompassing an impressive corpus of work over the past ten years. Alex Beskos presented antithetic multilevel methods for diffusions, which allow to improve the error in the discretisation, even though I did not fully get the whole idea (partly due to dozing out from time to time, a consequence of my last early rounds of Arthur’s Seat in the very early morn).

Daniel Paulin presented a novel unbiased method based on kinetic Langevin dynamics that combines advanced splitting methods with enhanced gradients, avoiding Metropolis correction by coupling and multilevel Monte Carlo approach, achieving unbiasedness by telescoping, but involving an avalanche of acronyms in the leapfrog/Gibbs steps.  And Adam Johansen (U of Warwick) on several recent papers of their divide-and-conquer filtering methods, introduced in a 2017 JCGS paper, following a decomposition of the state variable into low-dimensional components like branches and leaves of a tree.

distributed evidence

Posted in Books, pictures, Statistics, University life with tags , , , , , , , , , , , , , , , , , , on December 16, 2021 by xi'an

Alexander Buchholz (who did his PhD at CREST with Nicolas Chopin), Daniel Ahfock, and my friend Sylvia Richardson published a great paper on the distributed computation of Bayesian evidence in Bayesian Analysis. The setting is one of distributed data from several sources with no communication between them, which relates to consensus Monte Carlo even though model choice has not been particularly studied from that perspective. The authors operate under the assumption of conditionally conjugate models, i.e., the existence of a data augmentation scheme into an exponential family so that conjugate priors can be used. For a division of the data into S blocks, the fundamental identity in the paper is

p(y) = \alpha^S \prod_{s=1}^S \tilde p(y_s) \int \prod_{s=1}^S \tilde p(\theta|y_s)\,\text d\theta

where α is the normalising constant of the sub-prior exp{log[p(θ)]/S} and the other terms are associated with this prior. Under the conditionally conjugate assumption, the integral can be approximated based on the latent variables. Most interestingly, the associated variance is directly connected with the variance of

p(z_{1:S}|y)\Big/\prod_{s=1}^S \tilde p(z_s|y_s)

under the joint:

“The variance of the ratio measures the quality of the product of the conditional sub-posterior as an importance sample proposal distribution.”

Assuming this variance is finite (which is likely). An approximate alternative is proposed, namely to replace the exact sub-posterior with a Normal distribution, as in consensus Monte Carlo, which should obviously require some consideration as to which parameterisation of the model produces the “most normal” (or the least abnormal!) posterior. And ensures a finite variance in the importance sampling approximation (as ensured by the strong bounds in Proposition 5). A problem shared by the bridgesampling package.

“…if the error that comes from MCMC sampling is relatively small and that the shard sizes are large enough so that the quality of the subposterior normal approximation is reasonable, our suggested approach will result in good approximations of the full data set marginal likelihood.”

The resulting approximation can also be handy in conjunction with reversible jump MCMC, in the sense that RJMCMC algorithms can be run in parallel on different chunks or shards of the entire dataset. Although the computing gain may be reduced by the need for separate approximations.

averaged acceptance ratios

Posted in Statistics with tags , , , , , , , , , , , , , on January 15, 2021 by xi'an

In another recent arXival, Christophe Andrieu, Sinan Yıldırım, Arnaud Doucet, and Nicolas Chopin study the impact of averaging estimators of acceptance ratios in Metropolis-Hastings algorithms. (It is connected with the earlier arXival rephrasing Metropolis-Hastings in terms of involutions discussed here.)

“… it is possible to improve performance of this algorithm by using a modification where the acceptance ratio r(ξ) is integrated with respect to a subset of the proposed variables.”

This interpretation of the current proposal makes it a form of Rao-Blackwellisation, explicitly mentioned on p.18, where, using a mixture proposal, with an adapted acceptance probability, it depends on the integrated acceptance ratio only. Somewhat magically using this ratio and its inverse with probability ½. And it increases the average Metropolis-Hastings acceptance probability (albeit with a larger number of simulations). Since the ideal averaging is rarely available, the authors implement a Monte Carlo averaging version. With applications to the exchange algorithm and to reversible jump MCMC. The major application is to pseudo-marginal settings with a high complexity (in the number T of terms) and where the authors’ approach does scale efficiently with T. There is even an ABC side to the story as one illustration is made of the ABC approximation to the posterior of an α-stable sample. As an encompassing proposal for handling Metropolis-Hastings environments with latent variables and several versions of the acceptance ratios, this is quite an interesting paper that I think we will study in further detail with our students.

Monte Carlo fusion

Posted in Statistics with tags , , , , , , , , , on January 18, 2019 by xi'an

Hongsheng Dai, Murray Pollock (University of Warwick), and Gareth Roberts (University of Warwick) just arXived a paper we discussed together last year while I was at Warwick. Where fusion means bringing different parts of the target distribution

f(x)∝f¹(x)f²(x)…

together, once simulation from each part has been done. In the same spirit as in Scott et al. (2016) consensus Monte Carlo. Where for instance the components of the target cannot be computed simultaneously, either because of the size of the dataset, or because of privacy issues.The idea in this paper is to target an augmented density with the above marginal, using for each component of f, an auxiliary variable x¹,x²,…, and a target that is the product of the squared component, f¹(x¹)², f²(x²)², … by a transition density keeping f¹(.)²,f²(.)²,… invariant:

f^c(x^c)^2 p_c(y|x^c) / f_c(y)

as for instance the transition density of a Langevin diffusion. The marginal of

\prod_c f^c(x^c)^2 p_c(y|x^c) / f_c(y)

as a function of y is then the targeted original product. Simulating from this new extended target can be achieved by rejection sampling. (Any impact of the number of auxiliary variables on the convergence?) The practical implementation actually implies using the path-space rejection sampling methods in the Read Paper of Beskos et al. (2006). (An extreme case of the algorithm is actually an (exact) ABC version where the simulations x¹,x²,… from all components have to be identical and equal to y. The opposite extreme is the consensus Monte Carlo Algorithm, which explains why this algorithm is not an efficient solution.) An alternative is based on an Ornstein-Uhlenbeck bridge. While the paper remains at a theoretical level with toy examples, I heard from the same sources that applications to more realistic problems and implementation on parallel processors is under way.

EP as a way of life (aka Life of EP)

Posted in Books, Statistics, University life with tags , , , , , , , on December 24, 2014 by xi'an

When Andrew was in Paris, we discussed at length about using EP for handling big datasets in a different way than running parallel MCMC. A related preprint came out on arXiv a few days ago, with an introduction on Andrews’ blog. (Not written two months in advance as most of his entries!)

The major argument in using EP in a large data setting is that the approximation to the true posterior can be build using one part of the data at a time and thus avoids handling the entire likelihood function. Nonetheless, I still remain mostly agnostic about using EP and a seminar this morning at CREST by Guillaume Dehaene and Simon Barthelmé (re)generated self-interrogations about the method that hopefully can be exploited towards the future version of the paper.

One of the major difficulties I have with EP is about the nature of the resulting approximation. Since it is chosen out of a “nice” family of distributions, presumably restricted to an exponential family, the optimal approximation will remain within this family, which further makes EP sound like a specific variational Bayes method since the goal is to find the family member the closest to the posterior in terms of Kullback-Leibler divergence. (Except that the divergence is the opposite one.) I remain uncertain about what to do with the resulting solution, as the algorithm does not tell me how close this solution will be from the true posterior. Unless one can use it as a pseudo-distribution for indirect inference (a.k.a., ABC)..?

Another thing that became clear during this seminar is that the decomposition of the target as a product is completely arbitrary, i.e., does not correspond to an feature of the target other than the later being the product of those components. Hence, the EP partition could be adapted or even optimised within the algorithm. Similarly, the parametrisation could be optimised towards a “more Gaussian” posterior. This is something that makes EP both exciting as opening many avenues for experimentation and fuzzy as its perceived lack of goal makes comparing approaches delicate. For instance, using MCMC or HMC steps to estimate the parameters of the tilted distribution is quite natural in complex settings but the impact of the additional approximation must be gauged against the overall purpose of the approach.