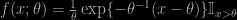Archive for unbiased estimation

importance sampling and independent Metropolis–Hastings with unbounded weights

Posted in Books, Statistics with tags , , , , , , , , , , , , on December 12, 2024 by xi'an

George Deligiannidis, Pierre E. Jacob, El Mahdi Khribch, and Guanyang Wang just arXived a paper on the respective behaviours of importance sampling and independent Metropolis–Hastings (IMH) under the same proposal when the importance weight is unbounded but enjoys a p-th moment with p≥2. Both algorithms are sharing a lot, with importance sampling appearing as a rough Rao-Blackwellisation of Metropolis-Hastings, and its asymptotic variance being smaller than the asymptotic variance of Metropolis-Hastings. I was unable to check whether or not their conditions encompassed the highly interesting case when the integrand f is integrable under the target π, but not L²(π). (Theorem 2.3 does not seem to include this case.)

They consider a particular (!) version of Metropolis–Hastings (IMH) under the same proposal when the importance weight is unbounded but enjoys a p-th moment. Both algorithms are sharing a lot, with importance sampling appearing when N iid proposed values are drawn at once and accepted or rejected (again at once) with an acceptance ratio the average of the weights. Although this is already found in a 2010 paper by Christophe Andrieu and co-authors, and stem from an unbiased importance sampler, I was not aware of this version. My initial feeling (predictably) was pessimistic, but thinking about it, using the average weight brings into the sample simulations with small weights that would otherwise be discarded. Of course, a rejection proves N times more costly. But this is truly a form of Rao-Blackwellisation in the sense that it removes the weight variability to some extent (see p5) and it turns the outcome into an unbiased estimator. Despite the self-normalising behaviour! They also conclude that the rejection probability is at least c/√N  on average (Remark 4.1).

“We show that the bias of self-normalized importance sampling is of order N −1, and we obtain new bounds on the moments of the error in importance sampling. We then consider IMH, and show that the common random numbers coupling is optimal. Using this coupling, we show that the total variation distance between IMH at iteration t and π decays as tp-1.”

They also compare the biases in sampling importance resampling and independent Metropolis–Hastings, with the later getting the upper hand, but I do not see the justification in resampling when computing an integral. Since this does not a sample from the target, especially when the weights are unbounded, and adds to the variability of the estimator. They further propose a (telescopic) unbiased modification to the self-normalised importance sampling estimator, with an inefficiency twice as high. But a neat Rao-Blackwellisation trick brings it back to the same level!

unbiased estimation of a reciprocal

Posted in Books, Statistics, University life with tags , , , , , , , , on November 8, 2024 by xi'an

As often, I came a’X this 2007 paper following an X-validated (if poorly worded) question that linked to it. With weird arguments:

  1. Computing an unbiased estimate of the integral induced by an unnormalised density f is a poor sales argument, as the renormalised object is not a probability density. Call to the unbiased approximation of Bayes factors the paper does not!
  2. The proposed solution involves a replacement of the unnormalised density f  by a substitute and normalised density h  that leads to the identity

\frac{f(y)}{\int f(x)\text dx}=\frac{hf(y)}{1-\int [h(x)-h(y)f(x)/f(x)]\text dx}=\frac{hf(y)}{1-a(y)}

with the assumption that the function a  is between -1 and 1, which requires some insight about the connection between f  and h.

  1. The unbiased estimator is an infinite power series in a(y). Requiring an increasing number of independent generations as the power grows.
  2. The series is unbiasedly terminated by playing roulette (if not Russian roulette!). Stopping when the k-th power estimate is below a certain bound. To be selected with no preliminary knowledge of the range of a.
  3. The uncertainty attached to the power series estimate is not evaluate and could reach the concerning level of an infinite variance.

that may explain for its limited popularity.


training energy based models

Posted in Books, Statistics with tags , , , , , , , on April 7, 2021 by xi'an

This recent arXival by Song and Kingma covers different computational approaches to semi-parametric estimation, but also exposes imho the chasm existing between statistical and machine learning perspectives on the problem.

“Energy-based models are much less restrictive in functional form: instead of specifying a normalized probability, they only specify the unnormalized negative log-probability (…) Since the energy function does not need to integrate to one, it can be parameterized with any nonlinear regression function.”

The above in the introduction appears first as a strange argument, since the mass one constraint is the least of the problems when addressing non-parametric density estimation. Problems like the convergence, the speed of convergence, the computational cost and the overall integrability of the estimator. It seems however that the restriction or lack thereof is to be understood as the ability to use much more elaborate forms of densities, which are then black-boxes whose components have little relevance… When using such mega-over-parameterised representations of densities, such as neural networks and normalising flows, a statistical assessment leads to highly challenging questions. But convergence (in the sample size) does not appear to be a concern for the paper. (Except for a citation of Hyvärinen on p.5.)

Using MLE in this context appears to be questionable, though, since the base parameter θ is not unlikely to remain identifiable. Computing the MLE is therefore a minor issue, in this regard, a resolution based on simulated gradients being well-chartered from the earlier era of stochastic optimisation as in Robbins & Monro (1954), Duflo (1996) or Benveniste & al. (1990). (The log-gradient of the normalising constant being estimated by the opposite of the gradient of the energy at a random point.)

“Running MCMC till convergence to obtain a sample x∼p(x) can be computationally expensive.”

Contrastive divergence à la Hinton (2002) is presented as a solution to the convergence problem by stopping early, which seems reasonable given the random gradient is mostly noise. With a possible correction for bias à la Jacob & al. (missing the published version).

An alternative to MLE is the 2005 Hyvärinen score, notorious for bypassing the normalising constant. But blamed in the paper for being costly in the dimension d of the variate x, due to the second derivative matrix. Which can be avoided by using Stein’s unbiased estimator of the risk (yay!) if using randomized data. And surprisingly linked with contrastive divergence as well, if a Taylor expansion is good enough an approximation! An interesting byproduct of the discussion on score matching is to turn it into an unintended form of ABC!

“Many methods have been proposed to automatically tune the noise distribution, such as Adversarial Contrastive Estimation (Bose et al., 2018), Conditional NCE (Ceylan and Gutmann, 2018) and Flow Contrastive Estimation (Gao et al., 2020).”

A third approach is the noise contrastive estimation method of Gutmann & Hyvärinen (2010) that connects with both others. And is a precursor of GAN methods, mentioned at the end of the paper via a (sort of) variational inequality.

on completeness

Posted in Books, Kids, Statistics with tags , , , , , , on November 19, 2020 by xi'an

Another X validated question that proved a bit of a challenge, enough for my returning to its resolution on consecutive days. The question was about the completeness of the natural sufficient statistic associated with a sample from the shifted exponential distribution

f(x;\theta) = \frac{1}{\theta^2}\exp\{-\theta^{-2}(x-\theta)\}\mathbb{I}_{x>\theta}

[weirdly called negative exponential in the question] meaning the (minimal) sufficient statistic is made of the first order statistic and of the sample sum (or average), or equivalently

T=(X_{(1)},\sum_{i=2}^n \{X_{(i)}-X_{(1)}\})

Finding the joint distribution of T is rather straightforward as the first component is a drifted Exponential again and the second a Gamma variate with n-2 degrees of freedom and the scale θ². (Devroye’s Bible can be invoked since the Gamma distribution follows from his section on Exponential spacings, p.211.) While the derivation of a function with constant expectation is straightforward for the alternate exponential distribution

f(x;\theta) = \frac{1}{\theta}\exp\{-\theta^{-1}(x-\theta)\}\mathbb{I}_{x>\theta}

since the ratio of the components of T has a fixed distribution, it proved harder for the current case as I was seeking a parameter free transform. When attempting to explain the difficulty on my office board, I realised I was seeking the wrong property since an expectation was enough. Removing the dependence on θ was simpler and led to

\mathbb E_\theta\left[\frac{X_{(1)}}{Y}-\frac{\Gamma(n-2)}{\Gamma(n-3/2)}Y^\frac{-1}{2}\right]=\frac{\Gamma(n-2)}{n\Gamma(n-1)}

but one version of a transform with fixed expectation. This also led me to wonder at the range of possible functions of θ one could use as scale and still retrieve incompleteness of T. Any power of θ should work but what about exp(θ²) or sin²(θ³), i.e. functions for which there exists no unbiased estimator..?

absurdly unbiased estimators

Posted in Books, Kids, Statistics with tags , , , , , , , on November 8, 2018 by xi'an

“…there are important classes of problems for which the mathematics forces the existence of such estimators.”

Recently I came through a short paper written by Erich Lehmann for The American Statistician, Estimation with Inadequate Information. He analyses the apparent absurdity of using unbiased estimators or even best unbiased estimators in settings like the Poisson P(λ) observation X producing the (unique) unbiased estimator of exp(-bλ) equal to

(1-b)^x

which is indeed absurd when b>1. My first reaction to this example is that the question of what is “best” for a single observation is not very meaningful and that adding n independent Poisson observations replaces b with b/n, which gets eventually less than one. But Lehmann argues that the paradox stems from a case of missing information, as for instance in the Poisson example where the above quantity is the probability P(T=0) that T=0, when T=X+Y, Y being another unobserved Poisson with parameter (b-1)λ. In a lot of such cases, there is no unbiased estimator at all. When there is any, it must take values outside the (0,1) range, thanks to a lemma shown by Lehmann that the conditional expectation of this estimator given T is either zero or one.

I find the short paper quite interesting in exposing some reasons why the estimators cannot find enough information within the data (often a single point) to achieve an efficient estimation of the targeted function of the parameter, even though the setting may appear rather artificial.