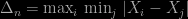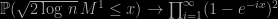Although there exists a direct approach based on the fact that the marginals are Exponential distributions and the conditionals signed mixtures of Gamma distributions, an accept-reject algorithm is also available for the pair, with a dominating density representing a genuine mixture of four Gammas, when omitting the X product in the exponential and the negative r in the first term. The efficiency of this accept-reject algorithm is high for r small. However, and in more direct connection with the original question, using this approach to integrate the function equal to the product of the pair, as considered in the original paper of Gumbel, is much less efficient than seeking a quasi-optimal importance function, since this importance function is yet another mixture of four Gammas that produces a much reduced variance at a cheaper cost!
This week, Nature has a “career news” section dedicated to how hiring quotas [may have] failed for French university hiring. And based solely on a technical report by a Science Po’ Paris researcher. The hiring quota means that every hiring committee for a French public university hiring committee must be made of at least 40% members of each gender. (Plus at least 50% of external members.) Which has been reduced to 30% in some severely imbalanced fields like mathematics. The main conclusion of the report is that the reform has had a negative impact on the hiring imbalance between men and women in French universities, with “the higher the share of women in a committee, the lower women are ranked” (p.2). As head of the hiring board in maths at Dauphine, which officiates as a secretarial committee for assembling all hiring committee, I was interested in the reasons for this perceived impact, as I had not observed it at my [first order remote] level. As a warning the discussion that follows makes little sense without a prior glance at the paper.
“Deschamps estimated that without the reform, 21 men and 12 women would have been hired in the field of mathematics. But with the reform, committees whose membership met the quota hired 30 men and 3 women”Nature,
Skipping the non-quantitative and somewhat ideological part of the report, as well as descriptive statistics, I looked mostly at the modelling behind the conclusions, as reported for instance in the above definite statement in Nature. Starting with a collection of assumptions and simplifications. A first dubious such assumption is that fields and even less universities where the more than 40% quota was already existing before (the 2015 reform) could be used as “control groups”, given the huge potential for confounders, especially the huge imbalance in female-to-male ratios in diverse fields. Second, the data only covers hiring histories for three French universities (out of 63 total) over the years 2009-2018 and furthermore merges assistant (Maître de Conférence) and full professors, where hiring is de facto much more involved, with often one candidate being contacted [prior to the official advertising of the position] by the department as an expression of interest (or the reverse). Third, the remark that
“there are no significant differences between the percentage of women who apply and those who are hired” (p.9)
seems to make the all discussion moot… and contradict both the conclusion and the above assertion! Fourth, the candidate’s qualification (or quality) is equated with the h-index, which is highly reductive and, once again, open to considerable biases in terms of seniority degree and of field. Depending on the publication lag and also the percentage of publications in English versus the vernacular in the given field. And the type of publications (from an average of 2.94 in business to 9.96 on physics]. Fifth, the report equates academic connections [that may bias the ranking] with having the supervisor present in the hiring committee [which sounds like a clear conflict of interest] or the candidate applying in the [same] university that delivered his or her PhD. Missing a myriad of other connections that make committee members often prone to impact the ranking by reporting facts from outside the application form.
“…controlling for field fixed effects and connections make the coefficient [of the percentage of women in the committee] statistically insignificant, though the point estimate remains high.” (p.17)
The models used by Pierre Deschamps are multivariate logit and probit regressions, where each jury attaches a utility to each of its candidates, made of a qualification term [for the position] and of a gender bias most surprisingly multiplying candidate gender and jury gender dummies. The qualification term is expressed as a [jury free] linear regression on covariates plus a jury fixed effect. Plus an error distributed as a Gumbel extreme variate that leads to a closed-form likelihood [and this seems to be the only reason for picking this highly skewed distribution]. The probit model is used to model the probability that one candidate has a better utility than another. The main issue with this modelling is the agglomeration of independence assumptions, as (i) candidates and hired ones are not independent, from being evaluated over several positions all at once, with earlier selections and rankings all public, to having to rank themselves all the positions where they are eligible, to possibly being co-authors of other candidates; (ii) jurys are not independent either, as the limited pool of external members, esp. in gender-imbalanced fields, means that the same faculty often ends up in several jurys at once and hence evaluates the same candidates as a result, plus decides on local ranking in connection with earlier rankings; (iii) independence between several jurys of the same university when this university may try to impose a certain if unofficial gender quota, a variate obviously impossible to fill . Plus again a unique modelling across disciplines. A side but not solely technical remark is that among the covariates used to predict ranking or first position for a female candidate, the percentage of female candidates appears, while being exogenous. Again, using a univariate probit to predict the probability that a candidate is ranked first ignores the comparison between a dozen candidates, both male and female, operated by the jury. Overall, I find little reason to give (significant) weight to the indicator that the president is a woman in the logistic regression and even less to believe that a better gender balance in the jurys has led to a worse gender balance in the hirings. From one model to the next the coefficients change from being significant to non-significant and, again, I find the definition of the control group fairly crude and unsatisfactory, if only because jurys move from one session to the next (and there is little reason to believe one field more gender biased than another, with everything else accounted for). And for another my own experience within hiring committees in Dauphine or elsewhere has never been one where the president strongly impacts the decision. If anything, the president is often more neutral (and never ever imoe makes use of the additional vote to break ties!)…
when the n-sample is made of iid Normal variates is (a) replaced with the distribution of one arbitrary minimum and (b) the distribution of the minimum is based on an assumption of independence between the absolute differences. Which does not hold, as shown by the above correlation matrix (plotted via corrplot) for N=11 and 10⁴ simulations. One could think that this correlation decreases with N, but it remains essentially 0.2 for larger values of N. (On the other hand, the minima are essentially independent.)
The riddle from the Riddler for the coming weeks is extremely simple to express in mathematical terms, as it summarises into characterising the distribution of
when the n-sample is made of iid Normal variates. I however had a hard time finding a result connected with this quantity since most available characterisations are for either Uniform or Exponential variates. I eventually found a 2017 arXival by Nagaraya et al. covering the issue. Since the Normal distribution belongs to the Gumbel domain of attraction, the extreme spacings, that is the spacings between the most extreme orders statistics [rescaled by nφ(Φ⁻¹{1-n⁻¹})] are asymptotically independent and asymptotically distributed as (Theorem 5, p.15, after correcting a typo):
where the ξ’s are Exp(1) variates. A crude approximation is thus to consider that the above Δ is distributed as the maximum of two standard and independent exponential distributions, modulo the rescaling by nφ(Φ⁻¹{1-n⁻¹})… But a more adequate result was pointed out to me by Gérard Biau, namely a 1986 Annals of Probability paper by Paul Deheuvels, my former head at ISUP, Université Pierre and Marie Curie. In this paper, Paul Deheuvels establishes that the largest spacing in a normal sample, M¹, satisfies
from which a conservative upper bound on the value of n required for a given bound x⁰ can be derived. The simulation below compares the limiting cdf (in red) with the empirical cdf of the above Δ based on 10⁴ samples of size n=10³.The limiting cdf is the cdf of the maximum of an infinite sequence of independent exponentials with scales 1,½,…. Which connects with the above result, in fine. For a practical application, the 99% quantile of this distribution is 4.71. To achieve a maximum spacing of, say 0.1, with probability 0.99, one would need 2 log(n) > 5.29²/0.1², i.e., log(n)>1402, which is a pretty large number…
As I had to wake up pretty early on Easter morning to give my daughter a ride, while waiting I came upon this calculus question on X validated of computing the conditional expectation of a Gumbel variate, conditional on its drifted version being larger than another independent Gumbel variate with the same location-scale parameters. (Just reminding readers that a Gumbel G(0,1) variate is a double log-uniform, i.e., can be generated as X=-log(-log(U)).) And found after a few minutes (and a call to Wolfram Alpha integrator) that
which is simple enough to make me wonder if there is a simpler derivation than the call to the exponential integral Ei(x) function. (And easy to check by simulation.)
Incidentally, I discovered that Emil Gumbel had applied statistical analysis to the study of four years of political murders in the Weimar Republic, demonstrating the huge bias of the local justice towards right-wing murders. When he signed the urgent call [for the union of the socialist and communist parties] against fascism in 1932, he got expelled from his professor position in Heidelberg and emigrated to France, which he had to leave again for the USA on the Nazi invasion in 1940. Where he became a professor at Columbia.
 A challenge interesting enough for a sunny New Year morn, found on X validated, namely the simulation of a bivariate exponential distribution proposed by Gumbel in 1960, with density over the positive quadrant in IR²


 The