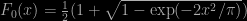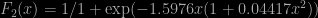In conjunction with the normal-Laplace comparison mentioned in the most recent post about our lack of confidence in ABC model choice, we have been working on the derivation of the exact Bayes factor and I derived an easy formula for the marginal likelihood in the Laplace case that boils down to a weighted sum of normal probabilities (with somehow obvious notations)
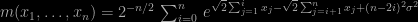

I then wrote a short R code that produced this marginal likelihood.
[sourcecode language=”r” gutter=”false”]
# ABC model comparison between Laplace and normal
# L(mu,V2) versus N(mu,1) with a prior N(0,2*2)
nobs=21
nsims=500
sqrtwo=sqrt(2)
marnor=function(smpl){
-0.5*nobs*log(2*pi)-0.5*(nobs-1)*var(smpl)+0.5*log(1+1/(4*nobs))-0.5*mean(smpl)^2/(4+1/nobs)}
marlap=function(sampl){
smpl=sort(sampl)
S=sum(smpl)
S=c(S,S-2*cumsum(smpl))
phi=pnorm((smpl-sqrtwo*4*(nobs-2*(1:nobs)))/2)
phip=pnorm((smpl-sqrtwo*4*(nobs-2*(1:nobs)+2))/2)
Dphi=log(c(phip[1],phip[-1]-phi[-nobs],1-phi[nobs]))
-0.5*nobs*log(2)+log(sum(exp(-sqrtwo*S+4*(nobs-2*(0:nobs))^2+Dphi)))
}
[/sourcecode]
When checking it with an alternative Monte Carlo integration, Jean-Michel Marin spotted a slight but persistent numerical difference:
[sourcecode language=”r” gutter=”false”]
> test=sample(c(-1,1),nobs,rep=TRUE)*rexp(nobs,sqrt(2))
> exp(marlap(test))
[1] 3.074013e-10
> f=function(x){exp(-sqrt(2)*sum(abs(test-x)))*2^(-nobs/2)}
> mean(apply(as.matrix(2*rnorm(10^6)),1,f))
[1] 3.126421e-11
[/sourcecode]
And while I thought it could be due to the simulation error, he persisted in analysing the problem until he found the reason: the difference between the normal cdfs in the above marginal was replaced by zero in the tails of the sample, while it contributed in a significant manner, due to the huge weights in front of those differences! He then rewrote the marlap function so that the difference was better computed in the tails, with a much higher level of agreement!
[sourcecode language=”r” gutter=”false”]
marlap=function(test){
sigma2=4
lulu=rep(0,nobs-1)
test=sort(test)
for (i in 1:(nobs-1)){
cst=sqrt(2)*(nobs-2*i)*sigma2
if (test[i]<0)
lulu[i]=exp(sqrt(2)*sum(test[1:i])-sqrt(2)*sum(test[(i+1):nobs])+
(nobs-2*i)^2*sigma2+pnorm((test[i+1]-cst)/sqrt(sigma2),log=TRUE)+
log(1-exp(pnorm((test[i]-cst)/sqrt(sigma2),log=TRUE)-
pnorm((test[i+1]-cst)/sqrt(sigma2),log=TRUE))))
else
lulu[i]=exp(sqrt(2)*sum(test[1:i])-sqrt(2)*sum(test[(i+1):nobs])+
(nobs-2*i)^2*sigma2+pnorm(-(test[i]-cst)/sqrt(sigma2),log=TRUE)+
log(1-exp(pnorm(-(test[i+1]-cst)/sqrt(sigma2),log=TRUE)-
pnorm(-(test[i]-cst)/sqrt(sigma2),log=TRUE))))
if (lulu[i]==0)
lulu[i]=exp(sqrt(2)*sum(test[1:i])-sqrt(2)*sum(test[(i+1):nobs])+
(nobs-2*i)^2*sigma2+log(pnorm((test[i+1]-cst)/sqrt(sigma2))-
pnorm((test[i]-cst)/sqrt(sigma2))))
}
lulu0=exp(-sqrt(2)*sum(test[1:nobs])+nobs^2*sigma2+
pnorm((test[1]-sqrt(2)*nobs*sigma2)/sqrt(sigma2),log=TRUE))
lulun=exp(sqrt(2)*sum(test[1:nobs])+nobs^2*sigma2+
pnorm(-(test[nobs]+sqrt(2)*nobs*sigma2)/sqrt(sigma2),log=TRUE))
2^(-nobs/2)*sum(c(lulu0,lulu,lulun))
}
[/sourcecode]
Here is an example of this agreement:
[sourcecode language=”r” gutter=”false”]
> marlap(test)
[1] 5.519428e-10
mean(apply(as.matrix(2*rnorm(10^6)),1,f))
[1] 5.540964e-10
[/sourcecode]