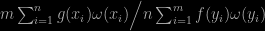Archive for bias

mostly Monte Carlo [new season]

Posted in Books, Statistics, University life with tags , , , , , , , , , on September 9, 2026 by xi'an

The new season of mostly Monte Carlo has started with three talks this very Friday! At Paris Santé Campus as usual.

14h El Mahdi Khribch (ESSEC)

Contributions to the Theory of Bayesian Computation: Bias, Information, and Robustness.

Abstract: Bayesian inference is rarely computable exactly, and every practical substitute, whether a Monte Carlo sampler, a tempered posterior or a variational approximation, carries an error. This thesis gives finite-sample guarantees for three of them: the bias of sampling-based integration, the information cost of data-dependent posteriors, and the robustness of inference under misspecification. The unifying tools throughout are PAC-Bayesian change-of-measure inequalities and their information-theoretic counterparts.

15h Federica Milinanni (Northwestern University)

Rapid Mixing of Stereographic MCMC for Heavy-Tailed Sampling

Abstract: Sampling from high-dimensional, heavy-tailed distributions is a fundamental challenge in computational statistics, as many standard Markov chain Monte Carlo (MCMC) methods mix poorly in such settings. Recently, Stereographic MCMC [Yang et al., 2024] and the Sub-Cauchy Projection Sampler [Grazzi et al., 2026] have been shown to perform successfully on such tasks. However, establishing their non-asymptotic convergence properties remains an important open problem. In this work, we fill this gap by establishing non-asymptotic upper bounds on the mixing time of the stereographic projection and sub-Cauchy projection samplers. Our results demonstrate that, under certain conditions on the target and initial distributions, the mixing time is polynomial in dimension for a broad class of distributions, including light- and heavy-tailed cases.

Motivated by the theoretical analysis, we further establish a new weighted isoperimetric inequality that extends the classical version for (strongly) log-concave distributions to the heavy-tailed setting with optimal dimension dependence.

The proof techniques provide new insights into the geometric properties of heavy-tailed distributions that govern rapid mixing in high dimensions.

This is joint work with Tyler Farghly (Inria) and Jun Yang (University of Copenhagen)

16h Sylvain Procope-Mamert (INRAe)

A forward only method to construct proposal distributions in particle filters

Abstract: Particle filters are powerful algorithms used to sample from a sequence of distributions. It is useful notably, for Bayesian inference with different types of models and real data applications. In particular, when we try to recover a hidden signal from sequentially produced data with state-space models, the canonically defined proposals known as the bootstrap particle filter are rarely well-behaved and need extra work to be turned into useful sampling algorithms. Previous works on iterated methods for the automated construction of sequential Monte Carlo proposals, which were based on a backward scheme, have shown how to gradually improve proposals to reach a global optimality criterion, but they require a good initial proposal and cannot be used online.

A modern introduction to probability and statistics [book review]

Posted in Books, R, Statistics, Travel, University life with tags , , , , , , , , , , , , , , , , , , , , , on July 12, 2025 by xi'an

In the plane to Bengaluru, I read through the book A modern introduction to probability and statistics, by Graham Upton—whose Measuring Animal Abundance I reviewed for CHANCE a while ago—, which is based on the earlier Understanding Statistics, written jointly with Ian Cook. (Not to be confused with A modern introduction to probability and statistics by Dekking et al.) The subtitle is understanding statistical principles in the computer age. Sorry, in the age of the computer. While the cover is most pleasant (and modern), as noticed by an AF flight attendant, the contents are very very standard and could have been written decades ago since the main concession to “the” computer age is the inclusion of a few R commands at the end of most chapters. There are even a few distribution tables here and there (in case “the” computer is not available). But there is no other connection with computational statistics or statistical computing.

The classicism of the contents and the intended audience mean there is little therein on which to either object or criticise. The mixture of elementary probability and basic statistics in a single textbook always feels awkward to me and I think I would have trouble teaching solely from this material. Apart from the glaring typo on the variance of the sum of two correlated random variables on page 87, missing the factor 2 in front of the covariance, while correct(ed) p97 (and the inevitable “the the” typo spotted once). My main criticisms are on the potential confusion between samples and populations in the early chapters, when some statistics are used as motivational examples, as for instance in a (hidden) Monte Carlo stabilisation to the limiting values (p57), way before the Law of Large Numbers is introduced,, the variable mileage in mathematical rigour (while being uncertain that first year students can handle integrals and derivatives), the textbook examples, and the amount of the book contents spent on descriptive statistics and even more on the “classical” tests, with no critical perspective on using point nulls or p-values. The book concludes with a four page (benevolent) chapter on Bayesian statistics that is superfluous imho, or even counterproductive since my experience with a rushed introduction to Bayesian principles almost always result in a rejection of said principles. Plus, the illustration with the coin tossing is not particularly helpful since Andrew maintains that one can load a die, but cannot bias a coin. (A similar reservation on the half-page 289 coverage on pseudo-random generation and Monte Carlo principles for computing p-values.)

Minor (mostly idiosyncratic) remarks follow: CLT prior to LLN,   n-1 in sample sd, little to no model criticism (ntbcf goodness of fit), missing an opportunity when mentioning the varying probability of a day being a birthday (p31) in contrast with BDA cover story, and another opportunity to cite the 2024 Ig Nobel Prize for coin tossing around the LLN, an unclear definition for random variables( p53) and a potentially confusing introduction of Poisson distributions through a informal reference to Poisson processes (and no reason why the years of accession of the kings of Sussex and England till Guillaume—making a return on p178 with the Domesday Book—in 1066 should follow such a process as suggested in Figure 3.5), a surprising definition of the constant e as the special case of exp(x) when x=1 and its series expansion (p70), omitting proofs on laws of sums of iid rv’s by introducing moment generating functions rather late, another obscure reference to a 16th German treatise on surveying as a precursor of the CLT (p131), a proof for the normalising constant of the Normal density that will most likely escape most first year students, a introduction of the t, F, and χ² distributions with no mention of their respective densities (pp141-147), never defining a joint Normal distribution density, insisting on unbiasedness without noting that maximum likelihood—with a strange motivation that it “makes the next sample of n observations most likely to resemble the data in the current sample (p228)—estimators are almost always biased, an abundance of footnotes that may prove of little interest for the youngest readers.

[Disclaimer about potential self-plagiarism as usual: this post or an edited version will eventually appear in my Books Review section in CHANCE.]

Data science ethics [book review]

Posted in Books, Statistics, University life with tags , , , , , , , , , , , , , , , , , , , , , , , , , , , , , , , , , on May 5, 2025 by xi'an

Data science ethics (concepts, techniques and cautionary tales), by David Martens, was published in 2022 by Oxford University Press. The book is inspired by the author’s  course on Data Science and ethics he has been teaching at the University of Antwerp. (With a link to his slides.) The 255p book proceeds by decomposing the ethics of data science into its different steps: data gathering (Chap. 2), data preprocessing (Chap. 3), modelling (Chap. 4), evaluation (Chap. 5), and deployment (Chap. 6). Following the `FAT Flow Framework´, where FAT stands for fairness, accountability, and transparency.

Do not expect much maths, stats, or anything quantitative: this book is mostly about concepts, even though some (mostly well-known) illustrations are provided. Chapter 2 includes a description of encryption (with homomorphic encryption treated in Chapter 4). And somewhat improbably quantum computing. Differential privacy gets a few pages with not a single formula (until Chapter 4, again).

Chapter 3 covers k-anonymity, record linkage, reidentification, (through cautionary tales) and discrimination through biases in the (learning) dataset.  Chapter 4 is defining ε differential privacy with the Laplace randomization as a possible implementation and with no critical stance on the limitations of the concept. The computation limitations of homomorphic encryption are more clearly pointed out. Federated learning is only quickly mentioned. The section about measuring fairness and reducing bias implies that some prior knowledge is available about whom is potentially discriminated and which covariates to add to the model. The last section on explicability of predictions is worthwhile in signalling the difficulty with most (black box) AI but the example opposing an SVM model to a logistic model is not tremendously convincing in that neither model is true.

Chapter 5 addresses the crucial challenge of ethical evaluation in a rather verbose and vague manner. For instance, with no instruction on how to resist adversarial attacks. Or criticising p-hacking and multiple testing while missing the elephant in the room (p-values!). Drifting from the topic when discussing the misdeeds of Diederik Stapel. Most of the same goes about Chapter 6 and its take on ethical deployment, when going through examples such as Google’s policies in China. Or general musing on the impact of AI on societal inequalities (with mentions of companies and CEOs who have since then back-pedalled on their ethical engagement). These chapters are lacking in tools and (more) practical recommendations.

One interesting aspect of the book is the attention paid to the EU(ropean) aspect of these concerns, through the GDPR (General DAta Protection Regulations) adopted by the European Parliament in 2016. (There is also a brief mention of China’s regulations, but no details beyond a reference. Maybe the Chinese edition differs.)

bias reduction in self-normalised importance sampling

Posted in Books, Statistics with tags , , , , , , on December 22, 2023 by xi'an

Gabriel Cardoso and coauthors (among whom Éric Moulines and Achille Thin, with whom I collaborated on the inFINE/NEO algorithm), have arXived a nice entry on a cheap way to reduce bias in the famously biased self-normalised importance sampling estimator. Which is a standard solution when the target density is not normalised. They reconsider a 2004 technical paper by Tjemeland—I remember reading at the time—, which constructs a sampling resampling algorithm by creating a Markov chain and choosing between the current value and a pool of M proposed values (from the importance function), according to the importance weight, which, thanks to Tjemeland’s reformulation with two copies of the current state, constitutes a Gibbs sampler with the correct target. As in Tjemeland (2004), they propose to recycle all proposed values into the integral estimate, which then turned being unbiased under stationarity, rather unexpectedly. The paper then proceeds to analyse convergence towards this expectation, linearly in the size of the pool and exponentially in the number of Markov iterations.


one bridge further

Posted in Books, R, Statistics, University life with tags , , , , , , , , , , , , on June 30, 2020 by xi'an

Jackie Wong, Jon Forster (Warwick) and Peter Smith have just published a paper in Statistics & Computing on bridge sampling bias and improvement by splitting.

“… known to be asymptotically unbiased, bridge sampling technique produces biased estimates in practical usage for small to moderate sample sizes (…) the estimator yields positive bias that worsens with increasing distance between the two distributions. The second type of bias arises when the approximation density is determined from the posterior samples using the method of moments, resulting in a systematic underestimation of the normalizing constant.”

Recall that bridge sampling is based on a double trick with two samples x and y from two (unnormalised) densities f and g that are interverted in a ratio

m \sum_{i=1}^n g(x_i)\omega(x_i) \Big/ n \sum_{i=1}^m f(y_i)\omega(y_i)

of unbiased estimators of the inverse normalising constants. Hence biased. The more the less similar these two densities are. Special cases for ω include importance sampling [unbiased] and reciprocal importance sampling. Since the optimal version of the bridge weight ω is the inverse of the mixture of f and g, it makes me wonder at the performance of using both samples top and bottom, since as an aggregated sample, they also come from the mixture, as in Owen & Zhou (2000) multiple importance sampler. However, a quick try with a positive Normal versus an Exponential with rate 2 does not show an improvement in using both samples top and bottom (even when using the perfectly normalised versions)

morc=(sum(f(y)/(nx*dnorm(y)+ny*dexp(y,2)))+
            sum(f(x)/(nx*dnorm(x)+ny*dexp(x,2))))/(
  sum(g(x)/(nx*dnorm(x)+ny*dexp(x,2)))+
         sum(g(y)/(nx*dnorm(y)+ny*dexp(y,2))))

at least in terms of bias… Surprisingly (!) the bias almost vanishes for very different samples sizes either in favour of f or in favour of g. This may be a form of genuine defensive sampling, who knows?! At the very least, this ensures a finite variance for all weights. (The splitting approach introduced in the paper is a natural solution to create independence between the first sample and the second density. This reminded me of our two parallel chains in AMIS.)