 Last week, Gegor Zens, Sylvia Frühwirth-Schnatter, and Helga Wagner arXived a revision of their paper on latent Pólya-Gamma random variables for logistic regression models (which I had not read before). The central idea follows from Albert and Chib 1993 paper on a Gibbs sampler for binary and polychotomous data, namely a data augmentation (a.k.a. Gibbs sampling) that is natural as it allows for direct and uncalibrated sampling, but is not necessarily the best choice, since the completion by latent variables is prone to increase computing time and slow down exploration. In addition, since the posterior is close to Normal, a Metropolis scheme based on the MLE asymptotic distribution could perform well, w/o the completion step. As for other latent variable models such as mixtures, I keep wondering how efficiency could be improved by some latent variates not be changing at every iteration, given their almost Dirac (conditional) distribution. Especially in imbalanced cases. The paper proposes several novel mixture representations that lead to know distributions on the mixing parameter, constructed as in Jun Liu’s and Xiao-Li Meng’s auxiliary scale (or location-scale) completions, but these require an artificial parameter that need be calibrated.
Archive for Polya
ulΓimaΓe Pólγa
Posted in Books, pictures, Statistics, Travel with tags auxiliary variables, Data augmentation, Gibbs sampling, latent variable models, Polya, Schönbrunn palace, TU Wien, Vienna, Wien on July 18, 2023 by xi'anon approximations of Φ and Φ⁻¹
Posted in Books, Kids, R, Statistics with tags approximation, cdf, inverse cdf, Φ, logistic regression, numerical inversion, pnorm, Polya, qnorm(), R on June 3, 2021 by xi'anAs I was working on a research project with graduate students, I became interested in fast and not necessarily very accurate approximations to the normal cdf Φ and its inverse. Reading through this 2010 paper of Richards et al., using for instance Polya’s
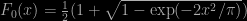
(with another version replacing 2/π with the squared root of π/8) and
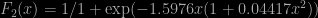
not to mention a rational faction. All of which are more efficient (in R), if barely, than the resident pnorm() function.
      test replications elapsed relative user.self
3 logistic       100000   0.410    1.000     0.410
2    polya       100000   0.411    1.002     0.411
1 resident       100000   0.455    1.110     0.455
For the inverse cdf, the approximations there are involving numerical inversion except for

which proves slightly faster than qnorm()
       test replications elapsed relative user.self
2 inv-polya       100000   0.401    1.000     0.401
1  resident       100000   0.450    1.000     0.450


