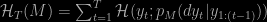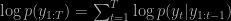Archive for Lévy diffusion process

All about that Bayes seminar [27 March, Paris Dauphine]

Posted in pictures, Statistics, Travel, University life with tags , , , , , , on March 25, 2024 by xi'an

The next All about that Bayes seminar will take place in Paris Dauphine, next Wednesday 27 March, at 2:00 p.m. (Room B Bis, 3rd floor) and will be delivered by François Caron (Oxford, visiting Paris Dauphine over the next two weeks) on

Deep Neural Networks with Dependent Weights: Gaussian Process Mixture Limit, Heavy Tails, Sparsity and Compressibility

This work studies the infinite-width limit of deep feedforward neural networks whose weights are dependent, and modelled via a mixture of Gaussian distributions. Each hidden node of the network is assigned a nonnegative random variable that controls the variance of the outgoing weights of that node. We make minimal assumptions on these per-node random variables: they are iid and their sum, in each layer, converges to some finite random variable in the infinite-width limit. Under this model, we show that each layer of the infinite-width neural network can be characterised by two simple quantities: a non-negative scalar parameter and a Lévy measure on the positive reals. If the scalar parameters are strictly positive and the Lévy measures are trivial at all hidden layers, then one recovers the classical Gaussian process (GP) limit, obtained with iid Gaussian weights. More interestingly, if the Lévy measure of at least one layer is non-trivial, we obtain a mixture of Gaussian processes (MoGP) in the large-width limit. The behaviour of the neural network in this regime is very different from the GP regime. One obtains correlated outputs, with non-Gaussian distributions, possibly with heavy tails. Additionally, we show that, in this regime, the weights are compressible, and some nodes have asymptotically non-negligible contributions, therefore representing important hidden features. Many sparsity-promoting neural network models can be recast as special cases of our approach, and we discuss their infinite-width limits; we also present an asymptotic analysis of the pruning error. We illustrate some of the benefits of the MoGP regime over the GP regime in terms of representation learning and compressibility on simulated, MNIST and Fashion MNIST datasets.

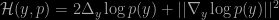
the Hyvärinen score is back

Posted in pictures, Statistics, Travel with tags , , , , , , , , , , , , , on November 21, 2017 by xi'an

Stéphane Shao, Pierre Jacob and co-authors from Harvard have just posted on arXiv a new paper on Bayesian model comparison using the Hyvärinen score

\mathcal{H}(y, p) = 2\Delta_y \log p(y) + ||\nabla_y \log p(y)||^2

which thus uses the Laplacian as a natural and normalisation-free penalisation for the score test. (Score that I first met in Padova, a few weeks before moving from X to IX.) Which brings a decision-theoretic alternative to the Bayes factor and which delivers a coherent answer when using improper priors. Thus a very appealing proposal in my (biased) opinion! The paper is mostly computational in that it proposes SMC and SMC² solutions to handle the estimation of the Hyvärinen score for models with tractable likelihoods and tractable completed likelihoods, respectively. (Reminding me that Pierre worked on SMC² algorithms quite early during his Ph.D. thesis.)

A most interesting remark in the paper is to recall that the Hyvärinen score associated with a generic model on a series must be the prequential (predictive) version

\mathcal{H}_T (M) = \sum_{t=1}^T \mathcal{H}(y_t; p_M(dy_t|y_{1:(t-1)}))

rather than the version on the joint marginal density of the whole series. (Followed by a remark within the remark that the logarithm scoring rule does not make for this distinction. And I had to write down the cascading representation

\log p(y_{1:T})=\sum_{t=1}^T \log p(y_t|y_{1:t-1})

to convince myself that this unnatural decomposition, where the posterior on θ varies on each terms, is true!) For consistency reasons.

This prequential decomposition is however a plus in terms of computation when resorting to sequential Monte Carlo. Since each time step produces an evaluation of the associated marginal. In the case of state space models, another decomposition of the authors, based on measurement densities and partial conditional expectations of the latent states allows for another (SMC²) approximation. The paper also establishes that for non-nested models, the Hyvärinen score as a model selection tool asymptotically selects the closest model to the data generating process. For the divergence induced by the score. Even for state-space models, under some technical assumptions.  From this asymptotic perspective, the paper exhibits an example where the Bayes factor and the Hyvärinen factor disagree, even asymptotically in the number of observations, about which mis-specified model to select. And last but not least the authors propose and assess a discrete alternative relying on finite differences instead of derivatives. Which remains a proper scoring rule.

I am quite excited by this work (call me biased!) and I hope it can induce following works as a viable alternative to Bayes factors, if only for being more robust to the [unspecified] impact of the prior tails. As in the above picture where some realisations of the SMC² output and of the sequential decision process see the wrong model being almost acceptable for quite a long while…