 Last week, Gegor Zens, Sylvia Frühwirth-Schnatter, and Helga Wagner arXived a revision of their paper on latent Pólya-Gamma random variables for logistic regression models (which I had not read before). The central idea follows from Albert and Chib 1993 paper on a Gibbs sampler for binary and polychotomous data, namely a data augmentation (a.k.a. Gibbs sampling) that is natural as it allows for direct and uncalibrated sampling, but is not necessarily the best choice, since the completion by latent variables is prone to increase computing time and slow down exploration. In addition, since the posterior is close to Normal, a Metropolis scheme based on the MLE asymptotic distribution could perform well, w/o the completion step. As for other latent variable models such as mixtures, I keep wondering how efficiency could be improved by some latent variates not be changing at every iteration, given their almost Dirac (conditional) distribution. Especially in imbalanced cases. The paper proposes several novel mixture representations that lead to know distributions on the mixing parameter, constructed as in Jun Liu’s and Xiao-Li Meng’s auxiliary scale (or location-scale) completions, but these require an artificial parameter that need be calibrated.
Archive for Data augmentation
ulΓimaΓe Pólγa
Posted in Books, pictures, Statistics, Travel with tags auxiliary variables, Data augmentation, Gibbs sampling, latent variable models, Polya, Schönbrunn palace, TU Wien, Vienna, Wien on July 18, 2023 by xi'andistributed evidence
Posted in Books, pictures, Statistics, University life with tags Bayesian Analysis, Bayesian model choice, belief aggregation, CDT, conditionally conjugate models, conjugate priors, consensus Monte Carlo, CREST, Data augmentation, data privacy, evidence, importance sampling, infinite variance estimators, marginal likelihood, MCMC, OxWaSP, parallel processing, reversible jump MCMC, University of Cambridge on December 16, 2021 by xi'an Alexander Buchholz (who did his PhD at CREST with Nicolas Chopin), Daniel Ahfock, and my friend Sylvia Richardson published a great paper on the distributed computation of Bayesian evidence in Bayesian Analysis. The setting is one of distributed data from several sources with no communication between them, which relates to consensus Monte Carlo even though model choice has not been particularly studied from that perspective. The authors operate under the assumption of conditionally conjugate models, i.e., the existence of a data augmentation scheme into an exponential family so that conjugate priors can be used. For a division of the data into S blocks, the fundamental identity in the paper is

where α is the normalising constant of the sub-prior exp{log[p(θ)]/S} and the other terms are associated with this prior. Under the conditionally conjugate assumption, the integral can be approximated based on the latent variables. Most interestingly, the associated variance is directly connected with the variance of
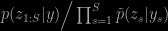
under the joint:
“The variance of the ratio measures the quality of the product of the conditional sub-posterior as an importance sample proposal distribution.”
Assuming this variance is finite (which is likely). An approximate alternative is proposed, namely to replace the exact sub-posterior with a Normal distribution, as in consensus Monte Carlo, which should obviously require some consideration as to which parameterisation of the model produces the “most normal” (or the least abnormal!) posterior. And ensures a finite variance in the importance sampling approximation (as ensured by the strong bounds in Proposition 5). A problem shared by the bridgesampling package.
“…if the error that comes from MCMC sampling is relatively small and that the shard sizes are large enough so that the quality of the subposterior normal approximation is reasonable, our suggested approach will result in good approximations of the full data set marginal likelihood.”
The resulting approximation can also be handy in conjunction with reversible jump MCMC, in the sense that RJMCMC algorithms can be run in parallel on different chunks or shards of the entire dataset. Although the computing gain may be reduced by the need for separate approximations.
ordered allocation sampler
Posted in Books, Statistics with tags Data augmentation, Galaxy, Gibbs sampling, hidden Markov models, JASA, label switching, latent variable models, MCMC, partition function, random partition trees, SMC, statistical methodology on November 29, 2021 by xi'an Recently, Pierpaolo De Blasi and María Gil-Leyva arXived a proposal for a novel Gibbs sampler for mixture models. In both finite and infinite mixture models. In connection with Pitman (1996) theory of species sampling and with interesting features in terms of removing the vexing label switching features.
“The key idea is to work with the mixture components in the random order of appearance in an exchangeable sequence from the mixing distribution (…) In accordance with the order of appearance, we derive a new Gibbs sampling algorithm that we name the ordered allocation sampler. “
This central idea is thus a reinterpretation of the mixture model as the marginal of the component model when its parameter is distributed as a species sampling variate. An ensuing marginal algorithm is to integrate out the weights and the allocation variables to only consider the non-empty component parameters and the partition function, which are label invariant. Which reminded me of the proposal we made in our 2000 JASA paper with Gilles Celeux and Merrilee Hurn (one of my favourite papers!). And of the [first paper in Statistical Methodology] 2004 partitioned importance sampling version with George Casella and Marty Wells. As in the later, the solution seems to require the prior on the component parameters to be conjugate (as I do not see a way to produce an unbiased estimator of the partition allocation probabilities).
The ordered allocation sample considers the posterior distribution of the different object made of the parameters and of the sequence of allocations to the components for the sample written in a given order, ie y¹,y², &tc. Hence y¹ always gets associated with component 1, y² with either component 1 or component 2, and so on. For this distribution, the full conditionals are available, incl. the full posterior on the number m of components, only depending on the data through the partition sizes and the number m⁺ of non-empty components. (Which relates to the debate as to whether or not m is estimable…) This sequential allocation reminded me as well of an earlier 2007 JRSS paper by Nicolas Chopin. Albeit using particles rather than Gibbs and applied to a hidden Markov model. Funny enough, their synthetic dataset univ4 almost resembles the Galaxy dataset (as in the above picture of mine)!
congrats [IMS related]
Posted in Statistics with tags associate editor, Biometrika, COPSS Award, Data augmentation, ERC, European Research Council, IMS, IMS Bulletin, Institute of Mathematical Statistics, JRSSB, MCMC, Series B on July 21, 2021 by xi'an When I read through the June-July issue of the IMS Bulletin, I saw many causes for celebration and congratulations!, from Richard Samworth’s award of an Advanced ERC grant, to the new IMS fellows, including my friends, Ismael Castillo, Steve Mc Eachern, and Natesh Pillai, as well as my current or former associate editors, Johan Segers (JRSS B) and Changbao Wu (Biometrika). To my friends Alicia Carriquiry, David Dunson, and Tamara Broderick receiving 2021 COPSS awards, along others, including Wing Hung Wong (of the precursor Tanner & Wong, 1987 fame!). Natesh also figures among the “Quadfecta 23”, the exclusive club of authors having published at least one paper in each of the four Annals published by the IMS!
Roberto Casarin’s talk at CREST tomorrow
Posted in Statistics with tags Bayesian econometrics, Ca' Foscari University, CREST, Data augmentation, financial network, Gibbs sampler, Gran Canale, hidden Markov chain, Markov switching models, seminar, Université Paris-Saclay, Venezia on March 13, 2019 by xi'an My former student and friend Roberto Casarin (University Ca’Foscari, Venice) will talk tomorrow at the CREST Financial Econometrics seminar on
“Bayesian Markov Switching Tensor Regression for Time-varying Networks”
Time: 10:30
Date: 14 March 2019
Place: Room 3001, ENSAE, Université Paris-Saclay
Abstract : We propose a new Bayesian Markov switching regression model for multi-dimensional arrays (tensors) of binary time series. We assume a zero-inflated logit dynamics with time-varying parameters and apply it to multi-layer temporal networks. The original contribution is threefold. First, in order to avoid over-fitting we propose a parsimonious parameterisation of the model, based on a low-rank decomposition of the tensor of regression coefficients. Second, the parameters of the tensor model are driven by a hidden Markov chain, thus allowing for structural changes. The regimes are identified through prior constraints on the mixing probability of the zero-inflated model. Finally, we model the jointly dynamics of the network and of a set of variables of interest. We follow a Bayesian approach to inference, exploiting the Pólya-Gamma data augmentation scheme for logit models in order to provide an efficient Gibbs sampler for posterior approximation. We show the effectiveness of the sampler on simulated datasets of medium-big sizes, finally we apply the methodology to a real dataset of financial networks.


