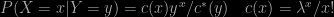Archive for exponential families

Information Geometry, Privacy and Monte Carlo workshop, ISM, 6-7 July 2026

Posted in Mountains, pictures, Statistics, Travel, University life with tags , , , , , , , , , , , , , , , , , , , , , , , , , , , , , on July 8, 2026 by xi'an

Although some of the participants of the workshop left for ICML²⁶ or the 4th Bayesian Nonparametrics networking workshop, both taking place in Seoul this week, the following days of the workshop were as intense and captivating as the first two, with a return to MCMC “basics” but also more geometrical and maethematical aspects.

To wit, Radu Craiu talked on MCMC for DAG processes with revisiting the landmark paper of Geyer & Møller (1994) on replacing discrete time MCMC with a birth & death process and cutting on complexity by restricted set imposing some edges, set from a redetermined run. Galin Jones presented some (novel) Lower bounds on the rate of convergence for accept-reject-based Markov chains in Wasserstein and total variation distances, showing the massive dependence of the convergence rates on the scaling factors of the proposal, especially in relation with the data size n when considering posterior targets. James Flegal discussed Simultaneous confidence bands for (MC)MC simulations that aimed at returning a confidence band on marginal density estimates; it reminded me of our 2005 simultaneous coverage paper with Wilfrid Kendall and Jean-Michel Marin and got me wondering why not going full Bayes by adopting a GP prior modelling.

Michiko Okudo spoke about Applications of information geometry to Bayesian prediction and estimation in curved exponential families, returning to point estimation with a mention of Marchand & Strawderman (2025)! Marta Catalano presented results on Distances on random measures for Bayesian nonparametrics, involving random measures like Dirichlet processes, that was connected with Hugo Lavenant’s talk at ISBA, but more focussed on the mathematical aspects albeit algorithmic aspects were mentioned. With highly intuitive arguments (making the accronym WoW for Wasserstein on Wasserstein quite appropriate!).

Takemasa Miyoshi made a presentation of the Osaka Expo 2025 Weather [prediction] on Fugaku: Synergizing Big Data Assimilation and AIRIKEN, with impressive predictive abilities achieved using RIKEN super-computer (but no technical details). Björn Sprung exposed how they obtained Dimension-independent MCMC [convergence speed] on the sphere, using retroprojections of random walks outside the sphere (as in Frederica’s talk yesterday), which comes as a surprise given the deterioration of random walk performances with increasing dimensions.

Geoffrey Wolfer’s Characterization of Exponential Families of Lumpable Stochastic Matrices was a very mathematical talk set firmly in the Japanese probability school, going too fast with too many new definitions for my abilities (and attention span) but setting the scene for exponential families on stochastic matrices and being one of the rate cases I eve rsaw lumpability à la Kemeny & Snell (1983) mentionned! Daniel Paulin followed with Stochastic gradient Langevin dynamics: convergence and bias, via an UBU algorithm using splitting integrators that sound very much like the leapfrog for an HMC with unscented Langevin steps where the gradient is replaced with an unbiased estimator (connecting to the poster of Jack Jewson on Sunday, when he mentioned the opposition between pseudo-marginal MCMC, requiring an unbiased estimator of the target, and schemes using the log-target, for which unbiased estimators of the log can be used). Shahab Asoodeh concluded Monday with Recent Advances in Metropolis-Hastings Algorithms, actually developing multi-marginal coupling with freely coupling chains.

On the final morning, Weiming Feng showed results about a Faster mixing of the Jerrum-Sinclair chain, reminding me of the 1989 paper, with a Metropolis algorithm on graphs allowing for specific mixing time results with spectral gap and log-Sobolev inequalities (and a Poincáre typo!). Michael Choi produced convergence properties by Optimising two-block averaging kernels to speed up Markov chains, with a (rather formal) Gibbs sampler on orbits (in a finite state space) again connecting to Jerrum.

Yuga Iguchi discussed Diffusion models for high-dimensional clustered data: Intrinsic-dimension adaptivity via Bayesian classification, producing a rigorous characterisation of the phase transition property of their diffusion denoising probabilistic model when the target is a mixture with separation constraints on the components, phase transition meaning that eventually concentrating on a single cluster as the forward diffusion moves toward pure noise. (Although being fully awake, having mostly recovered from the longest jetlag period ever, I had trouble understanding the process per se.) Edric Tam discussed Fundamental Limits to Neural Monte Carlo by returning to standard variance reduction techniques like stratifying and antithetic-ying (!) and applying normalising flows on them. Victor Elvira concluded the meeting by Rethinking self-normalized importance sampling, with a fun interlude of Eric Veach’s Oscars joke, but I unfortunately had to miss the end to gather my bags and leave for the Alps! But Victor should be in Paris in the Fall and hopfefully giving a talk at mostly Monte Carlo!

This workshop was most efficiently supported by the Institute of Statistical Mathematics and its staff, including over the weekend days! On a personal foodie note, the coffee breaks featured the same unbelievable matcha cakes (“Chez Kobe”) as at ISBA²⁶, we enjoyed a terrific full tofu dinner at Umenohana Tachikawa shop and there were plenty French (or pseudo-French) bakeries in Tachekima, enough to find rye (raimugi) bread for breakfast!

Objective Bayesian Inference [book review]

Posted in Books, Statistics, University life with tags , , , , , , , , , , , , , , , , , , , , , on July 2, 2024 by xi'an

As advertised earlier on the ‘Og, the reference book on reference priors and relatives by my long-time friends Jim Berger, José Bernardo, and Dongchu Sun is at last out! I received a copy from the editor, World Scientific, and read through it, mostly in train rides to Normandy and Brittany. The construction of this book took decades and I remember many O’Bayes meetings when we were discussing of the progress made that far. As I knew from a few months back that the book was at last completed, I was quite eager to dig into it. And get this review ready for ISBA 2024. Given this prior knowledge, completed with sequential observations, I thus fear my review will be far from objective! And most likely more critical than it should be as fantasying how I would have written a book on that topic…

“Some of the best statisticians (not named Fisher or Neyman)…” (p1)

The book covers traditional approaches to principled ways of selecting prior distributions, culminating with the reference prior introduced by José Bernardo in his PhD thesis in the late 1970’s and expanded by all three authors over their academic careers. (Why is the acute accent missing from José on the front pages?!) The cover connects to the three founding fathers of objective Bayesian inference, Bayes, Laplace, and Jeffreys. The contents are not overly surprising from a personal viewpoint, i.e. as a card-carrying O’Bayes member. Namely that the chapters set the scene of parametric models and Bayesian inference (“a data driven probability transformation machine”), mostly supported by decision theory (including intrinsic losses!) but skipping testing and (mostly) model choice. This is unsurprisingly in the same spirit as Berger (1985) and Bernardo & Smith (1992). Not covering advanced Bayesian asymptotics, any flavour of Bayesian nonparametrics, the more recent generalized Bayesian inference, and the impact of misspecified models. The likelihood section does not mention Deborah Mayo’s criticism of the Likelihood Principle, or the Pitman Koopman lemma (although the examples are predominantly connected with exponential families).  The section (1.8) on MCMC implies that the Metropolis algorithm is less accurate that the Gibbs sampler, which is an exaggerated generalisation from a simple example, accrued by a comparison that does not seem to account for mixing behaviours.

“Our own belief is that the effort [seeking objective prior distributions] is a misguided search for the holy grail” (p.68)

The basics of objective priors repeats the useful warning that a truncation of parameter space is far from advised, as is the call for vague proper priors à la BUGS (a “nonsense”). A remark on the alternative weakly informative priors à la BDA require subjective input, a whole section on the legitimacy of improper priors as KL limits of sequences of proper priors. Plus a nice recall of the data dependent prior of Wasserman (2000) forcing mixtures to avoid empty clusters. This was the prior Jean Diebolt and I implemented in our 1990 Gibbs sampling paper. (I do not really see it as data dependent to impose that no component comes empty in the sample, but rather as a different model removing some terms from the likelihood.) There is even a chapter dedicated to constant priors—the historical meaning of inverse probability—, with a section on the modern advocates of this constant prior, that mostly focus on Binomial model. The book goes on justifying this prior by an invariance under reparameterisation argument (p108), but the discussion may seem stretched for some newcomers. This is followed by a nice chapter on frequentist matching, covering the bivariate Normal case and some asymptotics, followed by confidence distributions, quite topical and then fiducial inference, that imagines a posterior without a prior, one short too short chapter on invariance priors arguing for the right-Haar vs the left-Haar prior measure in invariance settings as exact matching, completed by a useful if short chapter—I would not have thought of including—on the performances of objective priors, like over-dispersion or under-dispersion. A mention is made there of the (now well-known) danger of using MCMC with improper posteriors as the issue potentially goes undetected, as it did in the early 1990s. Within its coherence section, the authors recall the fundamentals of the lovely marginalisation paradoxes. While addressing some computational issues, the book does not mention the derivation of the Jeffreys prior for mixtures Clara Grazian and I examined. The chapter ends by a rather expedited dismissal of maximum entropy. Which many still regard as the default approach to (partly informed) objective prior modelling. (They’ll be back in Chapter 13.)

The last hundred pages (Chap. 9-14) of the book are focussing on reference priors, as should be given the priorities of the authors. Starting with the rather convincing concept of maximising missing information, getting asymptotic to remove the impact of the data, and turning recursive in case of multidimensional parameters, while resorting to compact parameter spaces to avoid improprieties (the Achille’s heel of reference priors!). Reaching a definition (p176) in the univariate case that coherently does not depend on the sample size but on an arbitrary dominating measure (p179), interestingly sharing this feature with the definition of conjugate priors. In multivariate settings, things get… more complicated! And force a separation between nuisance and interesting parameters lest the resulting priors prove underperforming. Asymptotic normality again helps, but the derivation remains involved witness a one page (p201) theorem (Proposition 10.2).  My favourite example of selecting the prior for a Normal mean squared norm is there, with the original Jeffreys prior based on the Normal vector failing badly while the reference prior based on the norm of the observation does much better! (An open problem is the construction of the Jeffreys prior in that example.) A large table (p210) illustrates the plethora of reference priors depending on the parameter ordering. A short chapter (11) specialises on discrete parameters as in population sizes. And in model choice, a resolution I had not seen previously, with prior weights depending on the number of parameters in the respective models. But not accounting for embedded models. Chapter 12 addresses the “overall objective” prior construction when all parameters are equal (and none more equal than others). Supporting in the end the best overall prior defined in terms of distance to a family of reference priors. With a special treatment of the hierarchical Normal model following Berger & al. (2020). Chapter 13 is a short incursion into partial information reference priors, incl. maxent priors. Chapter 14 is about special reference priors exploiting special structures. And, at last, Chapter 15 a non-chapter pointing out to a catalogue of objective priors, following Yang & Berger (1997) as well as an initiative set during one of the O’Bayes meetings.

On the minor (nitpicking) side, I found a few “the the” (the typo no one can escape!) throughout the book, informality in some statements like Proposition 1.6, whose limit (in n) depends on n (a shortcut from which we try to wean our students). Also a somewhat anecdotal appearance of the ratio of uniforms algorithm with a mistaken statement that the method doesn’t depend on a proposal (p61), the references to Jeffreys’ main book clashing between the 1930s  and 1961 (final edition). The “random posterior” section 1.8 6 seems unfinished.

In conclusion, this much awaited reference book does deliver! It brings a perspective on reference priors that no other book does and reflects (well) on the authors’ careful completion of a coherent theory, hence should appeal to anyone working on the foundations and principles of Bayesian inference. Obviously, it will not change the position of strict subjectivists, nor convince non-Bayesians, but it should inspire current and future researchers, as well as complement graduate courses on Bayesian inference. In addition, the huge bibliography retraces the work in the area till today (if less intensely in the most recent years). Kudos to the authors, then!

[Disclaimer about potential self-plagiarism: this post or an edited version will eventually appear in my Books Review section in CHANCE!]

Saddlepoint Monte Carlo and its application to vote transfers

Posted in Books, Statistics, University life with tags , , , , , , , , , , , , on January 3, 2024 by xi'an


Our former Dauphine Master student Théo Voldoire (now PhD-ing at Harvard), along with Nicolas Chopin, Guillaume Rateau, and Robin Ryder (now at Imperial), arXived a month ago a paper with title Saddlepoint Monte Carlo and its Application to Exact Ecological Inference, essentially the outcome of his Master thesis last summer. Nicolas came to present the paper at our Mostly MC seminar. The motivating example is about vote transfers (to surviving candidates for a second round, as in the French presidential and deputorial elections) based on results from polling stations across rounds, which equates filling a contingency table with known margins, exploiting multiple tools like characteristic functions, inverse Fourier transform, its Monte Carlo version, pseudo-marginal MCMC, tilting, exponential families, quasi Monte Carlo! Which also reminded me of the time Reuven Rubinstein was occasionally visiting Paris, defending the cross entropy approach. Among multiple questions raised by this original approach to an “old” problem, one may think of the model misspecification issue that political analysts would not fail to raise, namely that the transfer estimates are based on multinomial models, that all models are wrong, &tc. We discussed briefly about this during the seminar, the suggestion being a predictive check by cross validation. The talk also brought to mind highly probable applications to privacy, and possibly to capture recapture.

mean simulations

Posted in Books, Statistics with tags , , , , , , , , on May 10, 2023 by xi'an


A rather intriguing question on X validated, namely a simulation approach to sampling a bivariate distribution fully specified by one conditional p(x|y) and the symmetric conditional expectation IE[Y|X=x]. The book Conditional Specification of Statistical Models, by Arnold, Castillo and Sarabia, as referenced by and in the question, contains (§7.7) illustrations of such cases. As for instance with some power series distribution on ℕ but also for some exponential families (think Laplace transform). An example is when

P(X=x|Y=y) = c(x)y^x/c^*(y)\quad c(x)=\lambda^x/x!

which means X conditional on Y=y is exponential E(λy). The expectation IE[Y|X=x] is then sufficient to identify the joint. As I figured out before checking the book, this result is rather immediate to establish by solving a linear system, but it does not help in finding a way to simulating the joint. (I am afraid it cannot be connected to the method of simulated moments!)


latest math stats exam

Posted in Books, Kids, R, Statistics, University life with tags , , , , , , , , , on January 28, 2023 by xi'an


As I finished grading our undergrad math stats exam (in Paris Dauphine) over the weekend, which was very straightforward this year, the more because most questions had already been asked on weekly quizzes or during practicals, some answers stroke me as atypical (but ChatGPT is not to blame!). For instance, in question 1, (c) received a fair share of wrong eliminations as g not being necessarily bounded. Rather than being contradicted by (b) being false. (ChatGPT managed to solve that question, except for the L² convergence!)

Question 2 was much less successful than we expected, most failures due to a catastrophic change of parameterisation for computing the mgf that could have been ignored given this is a Bernoulli model, right?! Although the students wasted quite a while computing the Fisher information for the Binomial distribution in Question 3… (ChatGPT managed to solve that question!)

Question 4 was intentionally confusing and while most (of those who dealt with the R questions) spotted the opposition between sample and distribution, hence picking (f), a few fell into the trap (d).

Question 7 was also surprisingly incompletely covered by a significant fraction of the students, as they missed the sufficiency in (c). (ChatGPT did not manage to solve that question, starting with the inverted statement that “a minimal sufficient statistic is a sufficient statistic that is not a function of any other sufficient statistic”…)

And Question 8 was rarely complete, even though many recalled Basu’s theorem for (a) [more rarely (d)] and flunked (c). A large chunk of them argued that the ancilarity of statistics in (a) and (d) made them [distributionally] independent of μ, therefore [probabilistically] of the empirical mean! (Again flunked by ChatGPT, confusing completeness and sufficiency.)