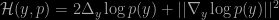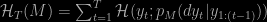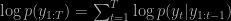Archive for penalisation

a versatile alternative to ABC

Posted in Books, Statistics with tags , , , , , , , , , on July 25, 2023 by xi'an

“We introduce the Fixed Landscape Inference MethOd, a new likelihood-free inference method for continuous state-space stochastic models. It applies deterministic gradient-based optimization algorithms to obtain a point estimate of the parameters, minimizing the difference between the data and some simulations according to some prescribed summary statistics. In this sense, it is analogous to Approximate Bayesian Computation (ABC). Like ABC, it can also provide an approximation of the distribution of the parameters.”

I quickly read this arXival by Monard et al. that is presented as an alternative to ABC, while outside a Bayesian setup. The central concept is that a deterministic gradient descent provides an optimal parameter value when replacing the likelihood with a distance between the observed data and simulated synthetic data indexed by the current value of the parameter (in the descent). In order to operate the descent the synthetic data is assumed to be available as a deterministic transform of the parameter value and of a vector of basic random objects, eg Uniforms. In order to make the target function differentiable, the above Uniform vector is fixed for the entire gradient descent. A puzzling aspect of the paper is that it seems to compare the (empirical) distribution of the resulting estimator with a posterior distribution, unless the comparison is with the (empirical) distribution of the Bayes estimators. The variability due to the choice of the fixed vector of basic random objects does not seem to be taken into account either, apparently. Furthermore, the method is presented as able to handle several models at once, which I find difficult to fathom as (a) the random vectors behind each model necessarily vary and (b) there is no apparent penalisation for complexity.

robust inference using posterior bootstrap

Posted in Books, Statistics, University life with tags , , , , , , , , , , , , , , , on February 18, 2022 by xi'an

The famous 1994 Read Paper by Michael Newton and Adrian Raftery was entitled Approximate Bayesian inference, where the boostrap aspect is in randomly (exponentially) weighting each observation in the iid sample through a power of the corresponding density, a proposal that happened at about the same time as Tony O’Hagan suggested the related fractional Bayes factor. (The paper may also be equally famous for suggesting the harmonic mean estimator of the evidence!, although it only appeared as an appendix to the paper.) What is unclear to me is the nature of the distribution g(θ) associated with the weighted bootstrap sample, conditional on the original sample, since the outcome is the result of a random Exponential sample and of an optimisation step. With no impact of the prior (which could have been used as a penalisation factor), corrected by Michael and Adrian via an importance step involving the estimation of g(·).

At the Algorithm Seminar today in Warwick, Emilie Pompe presented recent research, including some written jointly with Pierre Jacob, [which I have not yet read] that does exactly that inclusion of the log prior as penalisation factor, along with an extra weight different from one, as motivated by the possibility of a misspecification. Including a new approach to cut models. An alternative mentioned during the talk that reminds me of GANs is to generate a pseudo-sample from the prior predictive and add it to the original sample. (Some attendees commented on the dependence of the later version on the chosen parameterisation, which is an issue that had X’ed my mind as well.)

Drogue : sortir du tout-répressif [reposted]

Posted in Books, Kids, Travel, Wines with tags , , , , , , , , , , , , , , on September 13, 2020 by xi'an

[Here is an editorial (my take at a Google translation) from Le Monde about the installment last week of a fixed fine of €200 for drug possession. Introduced in 2018 by the French Parliament, it is presented by the French government as a way to fight drug-trafficking (and its far reaching consequences in the (de)structuration of some suburbs) by turning consumers into de facto accomplices. Which I find counterproductive and irrational as prohibition never works and ultimately benefits criminals. Drug legalisation or at least drug decriminalisation, adopted in many other countries, would be much more beneficial. Disclaimer #1: I am not supporting the use of drugs, except tea of course. Disclaimer #2: I do not agree with the entirety of the editorial below.]

Continue reading →

the Hyvärinen score is back

Posted in pictures, Statistics, Travel with tags , , , , , , , , , , , , , on November 21, 2017 by xi'an

Stéphane Shao, Pierre Jacob and co-authors from Harvard have just posted on arXiv a new paper on Bayesian model comparison using the Hyvärinen score

\mathcal{H}(y, p) = 2\Delta_y \log p(y) + ||\nabla_y \log p(y)||^2

which thus uses the Laplacian as a natural and normalisation-free penalisation for the score test. (Score that I first met in Padova, a few weeks before moving from X to IX.) Which brings a decision-theoretic alternative to the Bayes factor and which delivers a coherent answer when using improper priors. Thus a very appealing proposal in my (biased) opinion! The paper is mostly computational in that it proposes SMC and SMC² solutions to handle the estimation of the Hyvärinen score for models with tractable likelihoods and tractable completed likelihoods, respectively. (Reminding me that Pierre worked on SMC² algorithms quite early during his Ph.D. thesis.)

A most interesting remark in the paper is to recall that the Hyvärinen score associated with a generic model on a series must be the prequential (predictive) version

\mathcal{H}_T (M) = \sum_{t=1}^T \mathcal{H}(y_t; p_M(dy_t|y_{1:(t-1)}))

rather than the version on the joint marginal density of the whole series. (Followed by a remark within the remark that the logarithm scoring rule does not make for this distinction. And I had to write down the cascading representation

\log p(y_{1:T})=\sum_{t=1}^T \log p(y_t|y_{1:t-1})

to convince myself that this unnatural decomposition, where the posterior on θ varies on each terms, is true!) For consistency reasons.

This prequential decomposition is however a plus in terms of computation when resorting to sequential Monte Carlo. Since each time step produces an evaluation of the associated marginal. In the case of state space models, another decomposition of the authors, based on measurement densities and partial conditional expectations of the latent states allows for another (SMC²) approximation. The paper also establishes that for non-nested models, the Hyvärinen score as a model selection tool asymptotically selects the closest model to the data generating process. For the divergence induced by the score. Even for state-space models, under some technical assumptions.  From this asymptotic perspective, the paper exhibits an example where the Bayes factor and the Hyvärinen factor disagree, even asymptotically in the number of observations, about which mis-specified model to select. And last but not least the authors propose and assess a discrete alternative relying on finite differences instead of derivatives. Which remains a proper scoring rule.

I am quite excited by this work (call me biased!) and I hope it can induce following works as a viable alternative to Bayes factors, if only for being more robust to the [unspecified] impact of the prior tails. As in the above picture where some realisations of the SMC² output and of the sequential decision process see the wrong model being almost acceptable for quite a long while…

a day for comments

Posted in Mountains, Statistics, Travel, University life with tags , , , , , , , , , , , , , , , , , , , , , , , , , on April 21, 2014 by xi'an

As I was flying over Skye (with [maybe] a first if hazy perspective on the Cuillin ridge!) to Iceland, three long sets of replies to some of my posts appeared on the ‘Og:

Thanks to them for taking the time to answer my musings…