 Ian Waudby-Smith and Aaditya Ramdas are presenting next month a Read Paper to the Royal Statistical Society in London on constructing a conservative confidence interval on the mean of a bounded random variable. Here is an extended abstract from within the paper:
For each m ∈ [0, 1], we set up a “fair” multi-round game of statistician
against nature whose payoff rules are such that if the true mean happened
to equal m, then the statistician can neither gain nor lose wealth in
expectation (their wealth in the m-th game is a nonnegative martingale),
but if the mean is not m, then it is possible to bet smartly and make
money. Each round involves the statistician making a bet on the next
observation, nature revealing the observation and giving the appropriate
(positive or negative) payoff to the statistician. The statistician then plays
all these games (one for each m) in parallel, starting each with one unit of
wealth, and possibly using a different, adaptive, betting strategy in each.
The 1 − α confidence set at time t consists of all m 2 [0, 1] such that the
statistician’s money in the corresponding game has not crossed 1/α. The
true mean μ will be in this set with high probability.
I read the paper on the flight back from Venice and was impressed by its universality, especially for a non-asymptotic method, while finding the expository style somewhat unusual for Series B, with notions late into being defined if at all defined. As an aside, I also enjoyed the historical connection to Jean Ville‘s 1939 PhD thesis (examined by Borel, Fréchet—his advisor—and Garnier) on a critical examination of [von Mises’] Kollektive. (The story by Glenn Shafer of Ville’s life till the war is remarkable, with the de Beauvoir-Sartre couple making a surprising and rather unglorious appearance!). Himself inspired by a meeting with Wald while in Berlin. The paper remains quite allusive about Ville‘s contribution, though, while arguing about its advance respective to Ville’s work… The confidence intervals (and sequences) depend on a supermartingale construction of the form
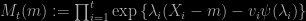
which allows for a universal coverage guarantee of the derived intervals (and can optimised in λ). As I am getting confused by that point about the overall purpose of the analysis, besides providing an efficient confidence construction, and am lacking in background about martingales, betting, and sequential testing, I will not contribute to the discussion. Especially since ChatGPT cannot help me much, with its main “criticisms” (which I managed to receive while in Italy, despite the Italian Government banning the chabot!)
However, there are also some potential limitations and challenges to this approach. One limitation is that the accuracy of the method is dependent on the quality of the prior distribution used to set the odds. If the prior distribution is poorly chosen, the resulting estimates may be inaccurate. Additionally, the method may not work well for more complex or high-dimensional problems, where there may not be a clear and intuitive way to set up the betting framework.
and
Another potential consequence is that the use of a betting framework could raise ethical concerns. For example, if the bets are placed on sensitive or controversial topics, such as medical research or political outcomes, there may be concerns about the potential for manipulation or bias in the betting markets. Additionally, the use of betting as a method for scientific or policy decision-making may raise questions about the appropriate role of gambling in these contexts.
being totally off the radar… (No prior involved, no real-life consequence for betting, no gambling.)


