
Archive for exact sampling
mostly MC’ruary [14 Feb 2025]
Posted in Books, Statistics, University life with tags diffusions, exact sampling, irreducibility, Issy-les-Moulineaux, MCMC, Mostly MC, Mostly MCMC seminar, Ocean, Paris, PariSanté campus, PDMP, Porte de Versailles, reversibility, seminar on February 12, 2025 by xi'an
Arnak Dalalyan at the RSS Journal Webinar
Posted in Books, pictures, Statistics, Travel, University life with tags approximate sampling, discussion paper, exact sampling, Journal of the Royal Statistical Society, Langevin MCMC algorithm, London, OUP, Oxford University Press, Palaiseau, Paris-Saclay campus, Read paper, Royal Statistical Society, RSS, RSS Journal Webinar, webinar on October 15, 2023 by xi'an
My friend and CREST colleague Arnak Dalalyan will (re)present [online] a Read Paper at the RSS on 31 October with my friends Hani Doss and Alain Durmus as discussants:
‘Theoretical Guarantees for Approximate Sampling and Log-Concave Densities’
Arnak Dalalyan ENSAE Paris, France
Sampling from various kinds of distributions is an issue of paramount importance in statistics since it is often the key ingredient for constructing estimators, test procedures or confidence intervals. In many situations, exact sampling from a given distribution is impossible or computationally expensive and, therefore, one needs to resort to approximate sampling strategies. However, there is no well-developed theory providing meaningful non-asymptotic guarantees for the approximate sampling procedures, especially in high dimensional problems. The paper makes some progress in this direction by considering the problem of sampling from a distribution having a smooth and log-concave density defined on ℝᵖ, for some integer p > 0. We establish non-asymptotic bounds for the error of approximating the target distribution by the distribution obtained by the Langevin Monte Carlo method and its variants. We illustrate the effectiveness of the established guarantees with various experiments. Underlying our analysis are insights from the theory of continuous time diffusion processes, which may be of interest beyond the framework of log-concave densities that are considered in the present work.
retrospective Monte Carlo
Posted in pictures, Running, Statistics, Travel, University life with tags cigarettes, CRiSM, debiasing, exact estimation, exact sampling, Monte Carlo Statistical Methods, multi-level Monte Carlo, perfect sampling, retrospective Monte Carlo, University of Warwick, Zig-Zag on July 12, 2016 by xi'an The past week I spent in Warwick ended up with a workshop on retrospective Monte Carlo, which covered exact sampling, debiasing, Bernoulli factory problems and multi-level Monte Carlo, a definitely exciting package! (Not to mention opportunities to go climbing with some participants.) In particular, several talks focussed on the debiasing technique of Rhee and Glynn (2012) [inspired from von Neumann and Ulam, and already discussed in several posts here]. Including results in functional spaces, as demonstrated by a multifaceted talk by Sergios Agapiou who merged debiasing, deburning, and perfect sampling.
From a general perspective on unbiasing, while there exist sufficient conditions to ensure finite variance and aim at an optimal version, I feel a broader perspective should be adopted towards comparing those estimators with biased versions that take less time to compute. In a diffusion context, Chang-han Rhee presented a detailed argument as to why his debiasing solution achieves a O(√n) convergence rate in opposition the regular discretised diffusion, but multi-level Monte Carlo also achieves this convergence speed. We had a nice discussion about this point at the break, with my slow understanding that continuous time processes had much much stronger reasons for sticking to unbiasedness. At the poster session, I had the nice surprise of reading a poster on the penalty method I discussed the same morning! Used for subsampling when scaling MCMC.
 On the second day, Gareth Roberts talked about the Zig-Zag algorithm (which reminded me of the cigarette paper brand). This method has connections with slice sampling but it is a continuous time method which, in dimension one, means running a constant velocity particle that starts at a uniform value between 0 and the maximum density value and proceeds horizontally until it hits the boundary, at which time it moves to another uniform. Roughly. More specifically, this approach uses piecewise deterministic Markov processes, with a radically new approach to simulating complex targets based on continuous time simulation. With computing times that [counter-intuitively] do not increase with the sample size.
Mark Huber gave another exciting talk around the Bernoulli factory problem, connecting with perfect simulation and demonstrating this is not solely a formal Monte Carlo problem! Some earlier posts here have discussed papers on that problem, but I was unaware of the results bounding [from below] the expected number of steps to simulate B(f(p)) from a (p,1-p) coin. If not of the open questions surrounding B(2p). The talk was also great in that it centred on recursion and included a fundamental theorem of perfect sampling! Not that surprising given Mark’s recent book on the topic, but exhilarating nonetheless!!!
The final talk of the second day was given by Peter Glynn, with connections with Chang-han Rhee’s talk the previous day, but with a different twist. In particular, Peter showed out to achieve perfect or exact estimation rather than perfect or exact simulation by a fabulous trick: perfect sampling is better understood through the construction of random functions φ¹, φ², … such that X²=φ¹(X¹), X³=φ²(X²), … Hence,

which helps in constructing coupling strategies. However, since the φ’s are usually iid, the above is generally distributed like
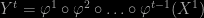
which seems pretty similar but offers a much better concentration as t grows. Cutting the function composition is then feasible towards producing unbiased estimators and more efficient. (I realise this is not a particularly clear explanation of the idea, detailed in an arXival I somewhat missed. When seen this way, Y would seem much more expensive to compute [than X].)


