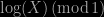Archive for Haar measure

model uncertainty and missing data: an objective BAyesian perspective

Posted in Books, Statistics, Travel, University life with tags , , , , , , , , , , , , , , , , , , , , , , , , , , , , , , , on September 16, 2025 by xi'an

My Spanish and objective Bayesian friends Gonzalo García-Donato, María Eugenia Castellanos, Stefano Cabras, Alicia Quirós, and Anabel Forte wrote an fairly exciting paper in BA that is open to discussion (for a few more days), to be discussed on 05 November (4:00 PM UTC | 11:00 AM EST | 5:00 PM CET).

The interplay between missing data and model uncertainty—two classic statistical problems—leads to primary questions that we formally address from an objective Bayesian perspective. For the general regression problem, we discuss the probabilistic justification of Rubin’s rules applied to the usual components of Bayesian variable selection, arguing that prior predictive marginals should be central to the pursued methodology. In the regression settings, we explore the conditions of prior distributions that make the missing data mechanism ignorable, provided that it is missing at random or completely at random. Moreover, when comparing multiple linear models, we provide a complete methodology for dealing with special cases, such as variable selection or uncertainty regarding model errors. In numerous simulation experiments, we demonstrate that our method outperforms or equals others, in consistently producing results close to those obtained using the full dataset. In general, the difference increases with the percentage of missing data and the correlation between the variables used for imputation.

The so-called Rubin’s identity is simply the representation of the posterior probability of a model γ given the observed data x⁰, p(γ|x⁰), as the integrated posterior probability of a model given both observed and latent data,  p(γ|x⁰, x¹), against the marginal of latent x¹ given observed x⁰. Since this marginal involves the probabilities p(γ|x⁰), this representation is not directly useful for a numerical implementation.

In this paper, missingness relates to some entries of either the covariates or the response variate. Which is less common but more realistic, especially if some covariates do not contribute to the response. (The missingness mechanism does not matter if the data is missing at random (à la Rubin). The computational solution (p9) is rather standard, simulating the missing variables given the observed variables. In my opinion, the elephant in the room is the super-delicate selection of a prior distribution on the missing covariates, as methinks this impacts in a considerable manner the actual value of the Bayes factor, hence the selection of the surviving model. (As a side remark, we are credited in Celeux et al. (2006) to have “extended DIC for missing data models or when missing data were present”, but our point was instead to point out the arbitrariness of the very definition of DIC in such contexts.)

“The standard Bayesian method for addressing the absence of prior information uses improper distributions. In estimation problems (the model is fixed), the impropriety of priors does not imply any additional difficulty as long as the posterior is proper” (p9)

The authors point out the well-known difficulty with improper priors but still resort to improper priors on the parameters shared by all models—which I dispute as being adequate, despite the arguments put forward on p15, right Haar measure or not—, while sticking to proper priors on the model-dependent parameters. Which unsurprisingly become Zellner’s g-priors. Or rather g’-priors, although the discussion seems to resolve into the (model-free) factor g’ being equal to 1 as for the g-priors. Again a strong term in the derivation of the Bayes factor.

non-reversible guided Metropolis–Hastings

Posted in Mountains, pictures, Statistics, Travel with tags , , , , , , , , , , , , on June 4, 2020 by xi'an

Kengo Kamatani and Xiaolin Song, whom I visited in Osaka last summer in what seems like another reality!, just arXived another paper on a non-reversible Metropolis version. That exploits a group action and the associated Haar measure.

Following a proposal of Gustafson (1998), a ∆-guided Metropolis–Hastings kernel is based on a statistic ∆ that is totally ordered and determine the acceptance of a proposed value y~Q(x,.) by adding a direction (-,+) to the state space and moving from x if ∆x≤∆y in the positive direction and if ∆y≤∆x in the negative direction [with the standard Metropolis–Hastings acceptance probability]. The sign of the direction switches in case of a rejection. And the statistic ∆ is such that the proposal kernel Q(x,.) is unbiased, i.e., agnostic to the sign, i.e., it gives the same probability to ∆x≤∆y and ∆y≤∆x. This modification reduces the asymptotic variance compared with the original Metropolis–Hastings kernel.

To construct a random walk proposal that is unbiased, the authors assume that the ∆ transform takes values in a topological group, G, with Q further being invariant under the group actions. This can be constructed from a standard proposal by averaging the transforms of Q under all elements of the group over the associated right Haar measure. (Which I thought implied that the group is compact, except I forgot to account for the data update into a posterior..!) The worked-out example is based on a multivariate autoregressive kernel with ∆x being a rescaled non-central chi-squared variate. In dimension 24. The results show a clear improvement in effective sample size per second evaluation over off-the-shelf random walk and Hamiltonian Monte Carlo versions.

Seeing the Haar measure appearing in the setting of Markov chain Monte Carlo is fun!, as my last brush with it was not algorithmic. I would think the proposal only applies to settings where the components of the simulated vector are somewhat homogeneous in that the determinationthe determination of both the group action and a guiding statistic seem harder in cases where these components take different meaning (or live in a weird topology). I also lazily wonder if selecting the guiding statistic as a gradient of the log-target would have any interest.

revisiting marginalisation paradoxes [Bayesian reads #1]

Posted in Books, Kids, pictures, Statistics, Travel, University life with tags , , , , , , , , , , , , , , , , , on February 8, 2019 by xi'an

As a reading suggestion for my (last) OxWaSP Bayesian course at Oxford, I included the classic 1973 Marginalisation paradoxes by Phil Dawid, Mervyn Stone [whom I met when visiting UCL in 1992 since he was sharing an office with my friend Costas Goutis], and Jim Zidek. Paper that also appears in my (recent) slides as an exercise. And has been discussed many times on this  ‘Og.

Reading the paper in the train to Oxford was quite pleasant, with a few discoveries like an interesting pike at Fraser’s structural (crypto-fiducial?!) distributions that “do not need Bayesian improper priors to fall into the same paradoxes”. And a most fascinating if surprising inclusion of the Box-Müller random generator in an argument, something of a precursor to perfect sampling (?). And a clear declaration that (right-Haar) invariant priors are at the source of the resolution of the paradox. With a much less clear notion of “un-Bayesian priors” as those leading to a paradox. Especially when the authors exhibit a red herring where the paradox cannot disappear, no matter what the prior is. Rich discussion (with none of the current 400 word length constraint), including the suggestion of neutral points, namely those that do identify a posterior, whatever that means. Funny conclusion, as well:

“In Stone and Dawid’s Biometrika paper, B1 promised never to use improper priors again. That resolution was short-lived and let us hope that these two blinkered Bayesians will find a way out of their present confusion and make another comeback.” D.J. Bartholomew (LSE)

and another

“An eminent Oxford statistician with decidedly mathematical inclinations once remarked to me that he was in favour of Bayesian theory because it made statisticians learn about Haar measure.” A.D. McLaren (Glasgow)

and yet another

“The fundamentals of statistical inference lie beneath a sea of mathematics and scientific opinion that is polluted with red herrings, not all spawned by Bayesians of course.” G.N. Wilkinson (Rothamsted Station)

Lindley’s discussion is more serious if not unkind. Dennis Lindley essentially follows the lead of the authors to conclude that “improper priors must go”. To the point of retracting what was written in his book! Although concluding about the consequences for standard statistics, since they allow for admissible procedures that are associated with improper priors. If the later must go, the former must go as well!!! (A bit of sophistry involved in this argument…) Efron’s point is more constructive in this regard since he recalls the dangers of using proper priors with huge variance. And the little hope one can hold about having a prior that is uninformative in every dimension. (A point much more blatantly expressed by Dickey mocking “magic unique prior distributions”.) And Dempster points out even more clearly that the fundamental difficulty with these paradoxes is that the prior marginal does not exist. Don Fraser may be the most brutal discussant of all, stating that the paradoxes are not new and that “the conclusions are erroneous or unfounded”. Also complaining about Lindley’s review of his book [suggesting prior integration could save the day] in Biometrika, where he was not allowed a rejoinder. It reflects on the then intense opposition between Bayesians and fiducialist Fisherians. (Funny enough, given the place of these marginalisation paradoxes in his book, I was mistakenly convinced that Jaynes was one of the discussants of this historical paper. He is mentioned in the reply by the authors.)

approximation of improper by vague priors

Posted in Statistics, University life with tags , , , on November 18, 2013 by xi'an

“…many authors prefer to replace these improper priors by vague priors, i.e. probability measures that aim to represent very few knowledge on the parameter.”

Christèle Bioche and Pierre Druihlet arXived a few days ago a paper with this title. They aim at bringing a new light on the convergence of vague priors to their limit. Their notion of convergence is a pointwise convergence in the quotient space of Radon measures, quotient being defined by the removal of the “normalising” constant. The first results contained in the paper do not show particularly enticing properties of the improper limit of proper measures as the limit cannot be given any (useful) probabilistic interpretation. (A feature already noticeable when reading Jeffreys.) The first result that truly caught my interest in connection with my current research is the fact that the Haar measures appear as a (weak) limit of conjugate priors (Section 2.5). And that the Jeffreys prior is the limit of the parametrisation-free conjugate priors of Druilhet and Pommeret (2012, Bayesian Analysis, a paper I will discuss soon!). The result about the convergence of posterior means is rather anticlimactic as the basis assumption is the uniform integrability of the sequence of the prior densities. An interesting counterexample (somehow familiar to invariance fans): the sequence of Poisson distributions with mean n has no weak limit. And the Haldane prior does appear as a limit of Beta distributions (less surprising). On (0,1) if not on [0,1].

The paper contains a section on the Jeffreys-Lindley paradox, which is only considered from the second perspective, the one I favour. There is however a mention made of the noninformative answer, which is the (meaningless) one associated with the Lebesgue measure of normalising constant one. This Lebesgue measure also appears as a weak limit in the paper, even though the limit of the posterior probabilities is 1. Except when the likelihood has bounded variations outside compacts. Then the  limit of the probabilities is the prior probability of the null… Interesting, truly, but not compelling enough to change my perspective on the topic. (And thanks to the authors for their thanks!)

Versions of Benford’s Law

Posted in Books, Statistics with tags , , , , on May 20, 2010 by xi'an

A new arXived note by Berger and Hill discusses how [my favourite probability introduction] Feller’s Introduction to Probability Theory (volume 2) gets Benford’s Law “wrong”. While my interest in Benford’s Law is rather superficial, I find the paper of interest as it shows a confusion between different folk theorems! My interpretation of Benford’s Law is that the first significant digit of a random variable (in a basis 10 representation) is distributed as

f(i) \propto \log_{10}(1+\frac{1}{i})

and not that \log(X) \,(\text{mod}\,1) is uniform, which is the presentation given in the arXived note…. The former is also the interpretation of William Feller (page 63, Introduction to Probability Theory), contrary to what the arXived note seems to imply on page 2, but Feller indeed mentioned as an informal/heuristic argument in favour of Benford’s Law that when the spread of the rv X is large,  \log(X) is approximately uniformly distributed. (I would no call this a “fundamental flaw“.) The arXived note is then right in pointing out the lack of foundation for Feller’s heuristic, if muddling the issue by defining several non-equivalent versions of Benford’s Law. It is also funny that this arXived note picks at the scale-invariant characterisation of Benford’s Law when Terry Tao’s entry represents it as a special case of Haar measure!