Archive for Newton-Raphson algorithm

robust privacy

Posted in Books, Statistics, University life with tags , , , , , , , , , , , , on May 14, 2024 by xi'an

During a recent working session, some Oceanerc (incl. me) went reading Privacy-Preserving Parametric Inference: A Case for Robust Statistics by Marco Avella-Medina (JASA, 2022), where robust criteria are advanced as efficient statistical tools in private settings. In this paper, robustness means using M-estimators T—as function of the empirical cdf—with basis score functions Ψ, defined as
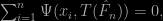
\sum_{i=1}^n\Psi(x_i,T(\hat F_n))=0,

where Ψ is bounded. A construction further requiring that one can assess the sensitivity (in Dwork et al, 2006, sense) of a queried function, sensitivity itself linked with a measure of differential privacy. Because standard robustness approaches à la Huber allow for a portion of the sample to issue from an outlying (arbitrary) distribution, as in ε-contaminations, it makes perfect sense that robustness emerges within the differential framework. However, this common sense perception does not seem good enough for achieving differential privacy and the paper introduces a further randomization with noise scaled by (n,ε,δ) in the following way

T(\hat F_n)+\gamma(T,\hat F_n)5\sqrt{2\log(n)\log(2/\delta)/\epsilon_n}Z

that also applies to test statistics. This scaling seems to constitute the central result of the paper, which establishes asymptotically validity in the sense of statistical consistency (with the sample size n). But I am left wondering whether this outcome counts as supporting differential privacy as a sensible notion…

“…our proofs for the convergence of noisy gradient descent and noisy Newton’s method rely on showing that with high probability, the noise introduced to the gradients and Hessians has a negligible effect on the convergence of the iterates (up to the order of the statistical error of the non-noisy versions of the algorithms).” Avella-Medina, Bradshaw, & Loh

As a sequel I then read a more recent publication of Avella-Medina, Differentially private inference via noisy optimization, written with Casey Bradshaw & Po-Ling Loh, which appeared in the Annals of Statistics (2023). Again considering privatised estimation and inference for M-estimators, obtained by using noisy optimization procedures (noisy gradient descent, noisy Newton’s method) and constructing noisy confidence regions, that output differentially private avatars of standard M-estimators. Here the noisification goes through a randomisation of the gradient step like
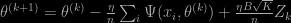
\theta^{(k+1)}=\theta^{(k)}-\frac{\eta}{n}\sum_i\Psi(x_i,\theta^{(k)})+\frac{\eta B\sqrt K}{n}Z_k

where B is an upper bound on the gradient Ψ, η is a discretization step, and K is the total number of iterations (thus fixed in advance). The above stochastic gradient sequence converges with high probability to the actual M-estimator in n and not in K, since the upper bound on the distance scales in √K/n. Where does the attached privacy guarantee come from? It proceeds by an argument of a composition of a sequence of differentially private outputs, all based on the same dataset.

“…the larger the number [K] of data (gradient) queries of the algorithm, the more prone it will be to privacy leakage.”

The Newton method version is a variation on the above stochastic gradient descent. Except it seems to converge faster, as illustrated above.

Bayesian learning

Posted in Statistics with tags , , , , , , , , on May 4, 2023 by xi'an

“…many well-known learning-algorithms, such as those used in optimization, deep learning, and machine learning in general, can now be derived directly following the above scheme using a single algorithm”

The One World ABC webinar today was delivered by Emtiyaz Khan (RIKEN), about the Bayesian Learning Rule, following Khan and Rue 2021 arXival on Bayesian learning. (It had a great intro featuring a video of the speaker’s daughter learning about the purpose of a ukulele in her first year!) The paper argues about a Bayesian interpretation/version of gradient descent algorithms, starting with Zellner’s (1988, the year I first met him!) identity that the posterior is solution to

\min_q \mathbb E_q[\ell(\theta,x)] + KL(q||\pi)

when ℓ is the likelihood and π the prior. This identity can be generalised to an arbitrary loss function (also dependent on the data)  replacing the likelihood and considered for a posterior chosen within an exponential family just as variational Bayes. Ending up with a posterior adapted to this target (in the KL sense). The optimal hyperparameter or pseudo-hyperparameter of this approximation can be recovered by some gradient algorithm, recovering as well stochastic gradient and Newton’s methods. While constructing a prior out of a loss function would have pleased the late Herman Rubin, this is not the case, but rater an approach to deriving a generalised Bayes distribution within a parametric family, including mixtures of Gaussians. At some point in the talk, the uncertainty endemic to the Bayesian approach seeped back into the picture, but since most of the intuition came from machine learning, I was somewhat lost at the nature of this uncertainty.


the Bayesian learning rule [One World ABC’minar, 27 April]

Posted in Books, Statistics, University life with tags , , , , , , , , , , , on April 24, 2023 by xi'an

The next One World ABC seminar is taking place (on-line, requiring pre-registration) on 27 April, 9:30am UK time, with Mohammad Emtiyaz Khan (RIKEN-AIP, Tokyo) speaking about the Bayesian learning rule:

We show that many machine-learning algorithms are specific instances of a single algorithm called the Bayesian learning rule. The rule, derived from Bayesian principles, yields a wide-range of algorithms from fields such as optimization, deep learning, and graphical models. This includes classical algorithms such as ridge regression, Newton’s method, and Kalman filter, as well as modern deep-learning algorithms such as stochastic-gradient descent, RMSprop, and Dropout. The key idea in deriving such algorithms is to approximate the posterior using candidate distributions estimated by using natural gradients. Different candidate distributions result in different algorithms and further approximations to natural gradients give rise to variants of those algorithms. Our work not only unifies, generalizes, and improves existing algorithms, but also helps us design new ones.

on arithmetic derivations of square roots

Posted in Books, Kids, pictures, R, Statistics with tags , , , , , , , , , on November 13, 2020 by xi'an

An intriguing question made a short-lived appearance on the CodeGolf section of Stack Exchange, before being removed, namely the (most concise possible) coding of an arithmetic derivation of the square root of an integer, S, with a 30 digit precision and using only arithmetic operators. I was not aware of the myriad of solutions available, as demonstrated on the dedicated WIkipedia page. And ended playing with three of them during a sleepless pre-election night!

The first solution for finding √S is based on a continued fraction representation of the root,

\sqrt{S}=a+\cfrac{r}{2a+\cfrac{r}{2a+\ddots}}

with a²≤S and r=S-a². It is straightforward to code-golf:

while((r<-S-T*T)^2>1e-9)T=(F<-2*T+r/(2*T+F))-T;F

but I found it impossible to reach the 30 digit precision (even when decreasing the error bound from 10⁻⁹). Given the strict rules of the game, this would have been considered to be a failure.

The second solution is Goldschmidt’s algorithm

b=S
T=1/sum((1:S)^2<S) 
while((1-S*prod(T)^2)^2>1e-9){
  b=b*T[1]^2
  T=c((3-b)/2,T)}
S*prod(T)

which is longer for code-golfing but produces both √S and 1/√S (and is faster than the Babylonian method and Newton-Raphson). Again no luck with high precision and almost surely unacceptable for the game.

The third solution is the most interesting [imho] as it mimicks long division, working two digits at a time (and connection with Napier’s bones)

`~`=length
D=~S
S=c(S,0*(1:30))
p=d=0
a=1:9
while(~S){ 
  F=c(F,x<-sum(a*(20*p+a)<=(g<-100*d+10*S[1]+S[2])))
  d=g-x*(20*p+x)
  p=x+10*p
  S=S[-1:-2]}
sum(10^{1+D/2-1:~F}*F)

plus providing an arbitrary number of digits with no error. This code requires S to be entered as a sequence of digits (with a possible extra top digit 0 to make the integer D even). Returning one digit at a time, it would further have satisfied the constraints of the question (if in a poorly condensed manner).

Leave the Pima Indians alone!

Posted in Books, R, Statistics, University life with tags , , , , , , , , , , , , , , , , on July 15, 2015 by xi'an

“…our findings shall lead to us be critical of certain current practices. Specifically, most papers seem content with comparing some new algorithm with Gibbs sampling, on a few small datasets, such as the well-known Pima Indians diabetes dataset (8 covariates). But we shall see that, for such datasets, approaches that are even more basic than Gibbs sampling are actually hard to beat. In other words, datasets considered in the literature may be too toy-like to be used as a relevant benchmark. On the other hand, if ones considers larger datasets (with say 100 covariates), then not so many approaches seem to remain competitive” (p.1)

Nicolas Chopin and James Ridgway (CREST, Paris) completed and arXived a paper they had “threatened” to publish for a while now, namely why using the Pima Indian R logistic or probit regression benchmark for checking a computational algorithm is not such a great idea! Given that I am definitely guilty of such a sin (in papers not reported in the survey), I was quite eager to read the reasons why! Beyond the debate on the worth of such a benchmark, the paper considers a wider perspective as to how Bayesian computation algorithms should be compared, including the murky waters of CPU time versus designer or programmer time. Which plays against most MCMC sampler.

As a first entry, Nicolas and James point out that the MAP can be derived by standard a Newton-Raphson algorithm when the prior is Gaussian, and even when the prior is Cauchy as it seems most datasets allow for Newton-Raphson convergence. As well as the Hessian. We actually took advantage of this property in our comparison of evidence approximations published in the Festschrift for Jim Berger. Where we also noticed the awesome performances of an importance sampler based on the Gaussian or Laplace approximation. The authors call this proposal their gold standard. Because they also find it hard to beat. They also pursue this approximation to its logical (?) end by proposing an evidence approximation based on the above and Chib’s formula. Two close approximations are provided by INLA for posterior marginals and by a Laplace-EM for a Cauchy prior. Unsurprisingly, the expectation-propagation (EP) approach is also implemented. What EP lacks in theoretical backup, it seems to recover in sheer precision (in the examples analysed in the paper). And unsurprisingly as well the paper includes a randomised quasi-Monte Carlo version of the Gaussian importance sampler. (The authors report that “the improvement brought by RQMC varies strongly across datasets” without elaborating for the reasons behind this variability. They also do not report the CPU time of the IS-QMC, maybe identical to the one for the regular importance sampling.) Maybe more surprising is the absence of a nested sampling version.

pimcisIn the Markov chain Monte Carlo solutions, Nicolas and James compare Gibbs, Metropolis-Hastings, Hamiltonian Monte Carlo, and NUTS. Plus a tempering SMC, All of which are outperformed by importance sampling for small enough datasets. But get back to competing grounds for large enough ones, since importance sampling then fails.

“…let’s all refrain from now on from using datasets and models that are too simple to serve as a reasonable benchmark.” (p.25)

This is a very nice survey on the theme of binary data (more than on the comparison of algorithms in that the authors do not really take into account design and complexity, but resort to MSEs versus CPus). I however do not agree with their overall message to leave the Pima Indians alone. Or at least not for the reason provided therein, namely that faster and more accurate approximations methods are available and cannot be beaten. Benchmarks always have the limitation of “what you get is what you see”, i.e., the output associated with a single dataset that only has that many idiosyncrasies. Plus, the closeness to a perfect normal posterior makes the logistic posterior too regular to pause a real challenge (even though MCMC algorithms are as usual slower than iid sampling). But having faster and more precise resolutions should on the opposite be  cause for cheers, as this provides a reference value, a golden standard, to check against. In a sense, for every Monte Carlo method, there is a much better answer, namely the exact value of the integral or of the optimum! And one is hardly aiming at a more precise inference for the benchmark itself: those Pima Indians [whose actual name is Akimel O’odham] with diabetes involved in the original study are definitely beyond help from statisticians and the model is unlikely to carry out to current populations. When the goal is to compare methods, as in our 2009 paper for Jim Berger’s 60th birthday, what matters is relative speed and relative ease of implementation (besides the obvious convergence to the proper target). In that sense bigger and larger is not always relevant. Unless one tackles really big or really large datasets, for which there is neither benchmark method nor reference value.