
Archive for Akaike’s criterion
At the Akaike Guest House
Posted in pictures, Statistics, Travel, University life with tags AIC, Akaike's criterion, guest house, Hiroki Akaike, information geometry, Institute of Statistical Mathematics, ISBA, Japan, jatp, Monte Carlo methods, privacy, satellite workshop, Tachikawa, Tokyo on July 26, 2026 by xi'an
filogenesi della pasta ripiena
Posted in Books, pictures, R, Statistics, University life with tags Akaike's criterion, article, Bayesian inference, culurgiones, Discover Food, dumplings, evolution tree, food science, gyoza, history of food, mandu, MCMC, momo, MrBayes, nested clade, pasta ripiena, philogenetic trees, R, ravioli, stuffed pasta, tortellini, wonton on November 13, 2024 by xi'an
Naturally amazed at non-identifiability
Posted in Books, Statistics, University life with tags Akaike's criterion, birth-and-death process, extant timetrees, identifiability, missing species problem, Nature, Ockham's razor, phylogeny, PNAS, population genetics, speciation rate, Steve Fienberg on May 27, 2020 by xi'an A Nature paper by Stilianos Louca and Matthew W. Pennell, Extant time trees are consistent with a myriad of diversification histories, comes to the extraordinary conclusion that birth-&-death evolutionary models cannot distinguish between several scenarios given the available data! Namely, stem ages and daughter lineage ages cannot identify the speciation rate function λ(.), the extinction rate function μ(.) and the sampling fraction ρ inherently defining the deterministic ODE leading to the number of species predicted at any point τ in time, N(τ). The Nature paper does not seem to make a point beyond the obvious and I am rather perplexed at why it got published [and even highlighted]. A while ago, under the leadership of Steve, PNAS decided to include statistician reviewers for papers relying on statistical arguments. It could time for Nature to move there as well.
“We thus conclude that two birth-death models are congruent if and only if they have the same rp and the same λp at some time point in the present or past.” [S.1.1, p.4]
Or, stated otherwise, that a tree structured dataset made of branch lengths are not enough to identify two functions that parameterise the model. The likelihood looks like

where E(.) is the probability to survive to the present and ψ(s,t) the probability to survive and be sampled between times s and t. Sort of. Both functions depending on functions λ(.) and μ(.). (When the stem age is unknown, the likelihood changes a wee bit, but with no changes in the qualitative conclusions. Another way to write this likelihood is in term of the speciation rate λp
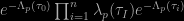
where Λp is the integrated rate, but which shares the same characteristic of being unable to identify the functions λ(.) and μ(.). While this sounds quite obvious the paper (or rather the supplementary material) goes into fairly extensive mode, including “abstract” algebra to define congruence.
“…we explain why model selection methods based on parsimony or “Occam’s razor”, such as the Akaike Information Criterion and the Bayesian Information Criterion that penalize excessive parameters, generally cannot resolve the identifiability issue…” [S.2, p15]
As illustrated by the above quote, the supplementary material also includes a section about statistical model selections techniques failing to capture the issue, section that seems superfluous or even absurd once the fact that the likelihood is constant across a congruence class has been stated.
An objective prior that unifies objective Bayes and information-based inference
Posted in Books, pictures, Statistics, Travel, University life with tags AIC, Akaike's criterion, free energy, information criterion, objective Bayes, Spain, Valencia conferences, w-prior on June 8, 2015 by xi'an During the Valencia O’Bayes 2015 meeting, Colin LaMont and Paul Wiggins arxived a paper entitled “An objective prior that unifies objective Bayes and information-based inference”. It would have been interesting to have the authors in Valencia, as they make bold claims about their w-prior as being uniformly and maximally uninformative. Plus achieving this unification advertised in the title of the paper. Meaning that the free energy (log transform of the inverse evidence) is the Akaike information criterion.
The paper starts by defining a true prior distribution (presumably in analogy with the true value of the parameter?) and generalised posterior distributions as associated with any arbitrary prior. (Some notations are imprecise, check (3) with the wrong denominator or the predictivity that is supposed to cover N new observations on p.2…) It then introduces a discretisation by considering all models within a certain Kullback divergence δ to be undistinguishable. (A definition that does not account for the assymmetry of the Kullback divergence.) From there, it most surprisingly [given the above discretisation] derives a density on the whole parameter space

where N is the number of observations and K the dimension of θ. Dimension which may vary. The dependence on N of the above is a result of using the predictive on N points instead of one. The w-prior is however defined differently: “as the density of indistinguishable models such that the multiplicity is unity for all true models”. Where the log transform of the multiplicity is the expected log marginal likelihood minus the expected log predictive [all expectations under the sampling distributions, conditional on θ]. Rather puzzling in that it involves the “true” value of the parameter—another notational imprecision, since it has to hold for all θ’s—as well as possibly improper priors. When the prior is improper, the log-multiplicity is a difference of two terms such that the first term depends on the constant used with the improper prior, while the second one does not… Unless the multiplicity constraint also determines the normalising constant?! But this does not seem to be the case when considering the following section on normalising the w-prior. Mentioning a “cutoff” for the integration that seems to pop out of nowhere. Curiouser and curiouser. Due to this unclear handling of infinite mass priors, and since the claimed properties of uniform and maximal uninformativeness are not established in any formal way, and since the existence of a non-asymptotic solution to the multiplicity equation is neither demonstrated, I quickly lost interest in the paper. Which does not contain any worked out example. Read at your own risk!
reading classics (#4,5,6)
Posted in Books, Kids, Statistics, University life with tags AIC, Akaike's criterion, ARMA models, Benjamini, classics, FAR, generalised linear models, GLMs, Hochberg, John Nelder, Master program, multiple comparisons, seminar, Université Paris Dauphine, Valencia conferences on December 9, 2013 by xi'an This week, thanks to a lack of clear instructions (from me) to my students in the Reading Classics student seminar, four students showed up with a presentation! Since I had planned for two teaching blocks, three of them managed to fit within the three hours, while the last one nicely accepted to wait till next week to present a paper by David Cox…
The first paper discussed therein was A new look at the statistical model identification, written in 1974 by Hirotugu Akaike. And presenting the AIC criterion. My student Rozan asked to give the presentation in French as he struggled with English, but it was still a challenge for him and he ended up being too close to the paper to provide a proper perspective on why AIC is written the way it is and why it is (potentially) relevant for model selection. And why it is not such a definitive answer to the model selection problem. This is not the simplest paper in the list, to be sure, but some intuition could have been built from the linear model, rather than producing the case of an ARMA(p,q) model without much explanation. (I actually wonder why the penalty for this model is (p+q)/T, rather than (p+q+1)/T for the additional variance parameter.) Or simulation ran on the performances of AIC versus other xIC’s…
[speakerdeck https://speakerdeck.com/xianblog/akaikes-aic-presentation-by-rozan-karagoz%5D
 The second paper was another classic, the original GLM paper by John Nelder and his coauthor Wedderburn, published in 1972 in Series B. A slightly easier paper, in that the notion of a generalised linear model is presented therein, with mathematical properties linking the (conditional) mean of the observation with the parameters and several examples that could be discussed. Plus having the book as a backup. My student Ysé did a reasonable job in presenting the concepts, but she would have benefited from this extra-week in including properly the computations she ran in R around the glm() function… (The definition of the deviance was somehow deficient, although this led to a small discussion during the class as to how the analysis of deviance was extending the then flourishing analysis of variance.) In the generic definition of the generalised linear models, I was also reminded of the
generality of the nuisance parameter modelling, which made the part of interest appear as an exponential shift on the original (nuisance) density.
[speakerdeck https://speakerdeck.com/xianblog/glms-by-nelder-and-wedderburn-discussed-by-yse-wanono%5D
The third paper, presented by Bong, was yet another classic, namely the FDR paper, Controlling the false discovery rate, of Benjamini and Hochberg in Series B (which was recently promoted to the should-have-been-a-Read-Paper category by the RSS Research Committee and discussed at the Annual RSS Conference in Edinburgh four years ago, as well as published in Series B). This 2010 discussion would actually have been a good start to discuss the paper in class, but Bong was not aware of it and mentioned earlier papers extending the 1995 classic. She gave a decent presentation of the problem and of the solution of Benjamini and Hochberg but I wonder how much of the novelty of the concept the class grasped. (I presume everyone was getting tired by then as I was the only one asking questions.) The slides somewhat made it look too much like a simulation experiment… (Unsurprisingly, the presentation did not include any Bayesian perspective on the approach, even though they are quite natural and emerged very quickly once the paper was published. I remember for instance the Valencia 7 meeting in Teneriffe where Larry Wasserman discussed about the Bayesian-frequentist agreement in multiple testing.)
[speakerdeck https://speakerdeck.com/xianblog/controlling-the-false-discovery-rate-by-bing-wong%5D


