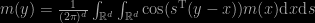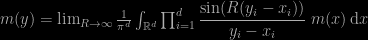Archive for Monte Carlo approximations

P(X<Y)

Posted in Books, Kids, Statistics with tags , , , , on July 17, 2023 by xi'an

A simple X-validated question on approximating P(X<Y) from two independent samples of X and Y. Which can be solved by a Monte Carlo approximation to

\mathbb{E}[\mathbb{I}_{X<Y}]

using all pairs of X’s and Y’s if the samples are not too large and a subsample of this set otherwise. However, I am (still) wondering if there is a more efficient way of using both samples, for instance by comparing the empirical cdfs of through using a Mann-Whitney statistic… (ChatGPT version 3.5 first returned a nonsense solution mentioning approximating the above probability when both distributions are equal [!], before acknowledging its error.)

Monte Carlo swindles

Posted in Statistics with tags , , , , , , , , , on April 2, 2023 by xi'an

While reading Boos and Hugues-Olivier’s 1998 American Statistician paper on the applications of Basu’s theorem I can across the notion of Monte Carlo swindles. Where a reduced variance can be achieved without the corresponding increase in Monte Carlo budget. For instance, approximating the variance of the median statistic Μ for a Normal location family can be sped up by considering that
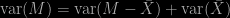
\text{var}(M)=\text{var}(M-\bar X)+\text{var}(\bar X)

by Basu’s theorem. However, when reading the originating 1973 paper by Gross (although the notion is presumably due to Tukey), the argument boils down to Rao-Blackwellisation (without the Rao-Blackwell theorem being mentioned). The related 1985 American Statistician paper by Johnstone and Velleman exploits a latent variable representation. It also makes the connection with the control variate approach, noticing the appeal of using the score function as a (standard) control and (unusual) swindle, since its expectation is zero. I am surprised at uncovering this notion only now… Possibly because the method only applies in special settings.

A side remark from the same 1998 paper, namely that the enticing decomposition

\mathbb E[(X/Y)^k] = \mathbb E[X^k] \big/ \mathbb E[Y^k]

when X/Y and Y are independent, should be kept out of reach from my undergraduates at all costs, as they would quickly get rid of the assumption!!!

integral theorems for Monte Carlo

Posted in Books, pictures, Statistics with tags , , , , , , , on August 12, 2021 by xi'an

Nhat Ho and Stephen G. Walker have just arXived a paper on the use of (Fourier) integral theorems for Monte Carlo estimators, following the earlier entry of Parzen: namely that for any integrable function,

m(y)=\frac{1}{(2\pi)^d}\int_{\mathbb R^d}\int_{\mathbb R^d}\cos(s^\text{T}(y-x))m(x)\text dx\text ds

which can be turned into an estimator of a density m based on a sample from m. This identity can be rewritten as

m(y)=\lim_{R\to\infty}\frac{1}{\pi^d}\int_{\mathbb R^d}\prod_{i=1}^d\dfrac{\sin(R(y_i-x_i))}{y_i-x_i}\;m(x)\,\text dx

and the paper generalises this identity to all cyclic functions. Even though it establishes that sin is the optimal choice. After reading this neat result, I however remain uncertain on how this could help with Monte Carlo integration.

a common confusion between sample and population moments

Posted in Books, Kids, R, Statistics with tags , , , , , , , on April 29, 2021 by xi'an

dial e for Buffon

Posted in Books, Kids, Statistics with tags , , , , , , , on January 29, 2021 by xi'an

The use of Buffon’s needle to approximate π by a (slow) Monte Carlo estimate is a well-known Monte Carlo illustration. But that a similar experiment can be used for approximating e seems less known, if judging from the 08 January riddle from The Riddler. When considering a sequence of length n exchangeable random variables, the probability of a particuliar ordering of the sequence is 1/n!. Thus, counting how many darts need be thrown on a target until the distance to the centre increases produces a random number N≥2 with pmf 1/n!-1/(n+1)! and with expectation equal to e. Which can be checked as follows

p=diff(c(0,1+which(diff(rt(1e5))>0)))
sum((p>1)*((p+1)*(p+2)/2-1)+2*(p==1))

which recycles simulations by using every one as starting point (codegolfers welcome!).

An earlier post on the ‘Og essentially covered the same notion, also linking it to Forsythe’s method and to Gnedenko. (Rényi could also be involved!) Paradoxically, the extra-credit given to the case when the target is divided into equal distance tori is much less exciting…