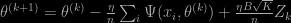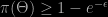Archive for robustness

mostly Monte Carlo [new season]

Posted in Books, Statistics, University life with tags , , , , , , , , , on September 9, 2026 by xi'an

The new season of mostly Monte Carlo has started with three talks this very Friday! At Paris Santé Campus as usual.

14h El Mahdi Khribch (ESSEC)

Contributions to the Theory of Bayesian Computation: Bias, Information, and Robustness.

Abstract: Bayesian inference is rarely computable exactly, and every practical substitute, whether a Monte Carlo sampler, a tempered posterior or a variational approximation, carries an error. This thesis gives finite-sample guarantees for three of them: the bias of sampling-based integration, the information cost of data-dependent posteriors, and the robustness of inference under misspecification. The unifying tools throughout are PAC-Bayesian change-of-measure inequalities and their information-theoretic counterparts.

15h Federica Milinanni (Northwestern University)

Rapid Mixing of Stereographic MCMC for Heavy-Tailed Sampling

Abstract: Sampling from high-dimensional, heavy-tailed distributions is a fundamental challenge in computational statistics, as many standard Markov chain Monte Carlo (MCMC) methods mix poorly in such settings. Recently, Stereographic MCMC [Yang et al., 2024] and the Sub-Cauchy Projection Sampler [Grazzi et al., 2026] have been shown to perform successfully on such tasks. However, establishing their non-asymptotic convergence properties remains an important open problem. In this work, we fill this gap by establishing non-asymptotic upper bounds on the mixing time of the stereographic projection and sub-Cauchy projection samplers. Our results demonstrate that, under certain conditions on the target and initial distributions, the mixing time is polynomial in dimension for a broad class of distributions, including light- and heavy-tailed cases.

Motivated by the theoretical analysis, we further establish a new weighted isoperimetric inequality that extends the classical version for (strongly) log-concave distributions to the heavy-tailed setting with optimal dimension dependence.

The proof techniques provide new insights into the geometric properties of heavy-tailed distributions that govern rapid mixing in high dimensions.

This is joint work with Tyler Farghly (Inria) and Jun Yang (University of Copenhagen)

16h Sylvain Procope-Mamert (INRAe)

A forward only method to construct proposal distributions in particle filters

Abstract: Particle filters are powerful algorithms used to sample from a sequence of distributions. It is useful notably, for Bayesian inference with different types of models and real data applications. In particular, when we try to recover a hidden signal from sequentially produced data with state-space models, the canonically defined proposals known as the bootstrap particle filter are rarely well-behaved and need extra work to be turned into useful sampling algorithms. Previous works on iterated methods for the automated construction of sequential Monte Carlo proposals, which were based on a backward scheme, have shown how to gradually improve proposals to reach a global optimality criterion, but they require a good initial proposal and cannot be used online.

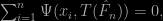
robust privacy

Posted in Books, Statistics, University life with tags , , , , , , , , , , , , on May 14, 2024 by xi'an

During a recent working session, some Oceanerc (incl. me) went reading Privacy-Preserving Parametric Inference: A Case for Robust Statistics by Marco Avella-Medina (JASA, 2022), where robust criteria are advanced as efficient statistical tools in private settings. In this paper, robustness means using M-estimators T—as function of the empirical cdf—with basis score functions Ψ, defined as

\sum_{i=1}^n\Psi(x_i,T(\hat F_n))=0,

where Ψ is bounded. A construction further requiring that one can assess the sensitivity (in Dwork et al, 2006, sense) of a queried function, sensitivity itself linked with a measure of differential privacy. Because standard robustness approaches à la Huber allow for a portion of the sample to issue from an outlying (arbitrary) distribution, as in ε-contaminations, it makes perfect sense that robustness emerges within the differential framework. However, this common sense perception does not seem good enough for achieving differential privacy and the paper introduces a further randomization with noise scaled by (n,ε,δ) in the following way

T(\hat F_n)+\gamma(T,\hat F_n)5\sqrt{2\log(n)\log(2/\delta)/\epsilon_n}Z

that also applies to test statistics. This scaling seems to constitute the central result of the paper, which establishes asymptotically validity in the sense of statistical consistency (with the sample size n). But I am left wondering whether this outcome counts as supporting differential privacy as a sensible notion…

“…our proofs for the convergence of noisy gradient descent and noisy Newton’s method rely on showing that with high probability, the noise introduced to the gradients and Hessians has a negligible effect on the convergence of the iterates (up to the order of the statistical error of the non-noisy versions of the algorithms).” Avella-Medina, Bradshaw, & Loh

As a sequel I then read a more recent publication of Avella-Medina, Differentially private inference via noisy optimization, written with Casey Bradshaw & Po-Ling Loh, which appeared in the Annals of Statistics (2023). Again considering privatised estimation and inference for M-estimators, obtained by using noisy optimization procedures (noisy gradient descent, noisy Newton’s method) and constructing noisy confidence regions, that output differentially private avatars of standard M-estimators. Here the noisification goes through a randomisation of the gradient step like

\theta^{(k+1)}=\theta^{(k)}-\frac{\eta}{n}\sum_i\Psi(x_i,\theta^{(k)})+\frac{\eta B\sqrt K}{n}Z_k

where B is an upper bound on the gradient Ψ, η is a discretization step, and K is the total number of iterations (thus fixed in advance). The above stochastic gradient sequence converges with high probability to the actual M-estimator in n and not in K, since the upper bound on the distance scales in √K/n. Where does the attached privacy guarantee come from? It proceeds by an argument of a composition of a sequence of differentially private outputs, all based on the same dataset.

“…the larger the number [K] of data (gradient) queries of the algorithm, the more prone it will be to privacy leakage.”

The Newton method version is a variation on the above stochastic gradient descent. Except it seems to converge faster, as illustrated above.

Bayesian differential privacy for free?

Posted in Books, pictures, Statistics with tags , , , , , , , , , , , , on September 24, 2023 by xi'an

“We are interested in the question of how we can build differentially-private algorithms within the Bayesian framework. More precisely, we examine when the choice of prior is sufficient to guarantee differential privacy for decisions that are derived from the posterior distribution (…) we show that the Bayesian statistician’s choice of prior distribution ensures a base level of data privacy through the posterior distribution; the statistician can safely respond to external queries using samples from the posterior.”

Recently I came across this 2016 JMLR paper of Christos Dimitrakakis et al. on “how Bayesian inference itself can be used directly to provide private access to data, with no modification.” Which comes as a surprise since it implies that Bayesian sampling would be enough, per se, to keep both the data private and the information it conveys available. The main assumption on which this result is based is one of Lipschitz continuity of the model density, namely that, for a specific (pseudo-)distance ρ

|\log f(x|\theta)-\log f(y|\theta)|\le L\rho(x,y)

uniformly in θ over a set Θ with enough prior mass

\pi(\Theta)\ge 1-e^{-\epsilon}

for an ε>0. In this case, the Kullback-Leibler divergence between the posteriors π(θ|x) and π(θ|y) is bounded by a constant times ρ(x,y). (The constant being 2L when Θ is the entire parameter space.) This condition ensures differential privacy on the posterior distribution (and even more on the associated MCMC sample). More precisely, (2L,0)-differentially private in the case Θ is the entire parameter space. While there is an efficiency issue linked with the result since the bound L being set by the model and hence immovable, this remains a fundamental result for the field (as shown by its high number of citations).

nonparametric ABC [seminar]

Posted in pictures, Statistics, University life with tags , , , , , , , , , , , , , on June 3, 2022 by xi'an

Puzzle: How do you run ABC when you mistrust the model?! We somewhat considered this question in our misspecified ABC paper with David and Judith. An AISTATS 2022 paper by Harita Dellaporta (Warwick), Jeremias Knoblauch,  Theodoros Damoulas (Warwick), and François-Xavier Briol (formerly Warwick) is addressing this same question and Harita presented the paper at the One World ABC webinar yesterday.

It is inspired from Lyddon, Walker & Holmes (2018), who place a nonparametric prior on the generating model, in top of the assumed parametric model (with an intractable likelihood). This induces a push-forward prior on the pseudo-true parameter, that is, the value that brings the parametric family the closest possible to the true distribution of the data. Here defined as a minimum distance parameter, the maximum mean discrepancy (MMD). Choosing RKHS framework allows for a practical implementation, resorting to simulations for posterior realisations from a Dirichlet posterior and from the parametric model, and stochastic gradient for computing the pseudo-true parameter, which may prove somewhat heavy in terms of computing cost.

The paper also containts a consistency result in an ε-contaminated setting (contamination of the assumed parametric family). Comparisons like the above with a fully parametric Wasserstein-ABC approach show that this alter resists better misspecification, as could be expected since the later is not constructed for that purpose.

Next talk is on 23 June by Cosma Shalizi.

[The Art of] Regression and other stories

Posted in Books, R, Statistics, University life with tags , , , , , , , , , , , , , , , , , , , on July 23, 2020 by xi'an

CoI: Andrew sent me this new book [scheduled for 23 July on amazon] of his with Jennifer Hill and Aki Vehtari. Which I read in my garden over a few sunny morns. And as Andrew and Aki are good friends on mine, this review is definitely subjective and biased! Hence to take with a spoonful of salt.

The “other stories’ in the title is a very nice touch. And a clever idea. As the construction of regression models comes as a story to tell, from gathering and checking the data, to choosing the model specifications, to analysing the output and setting the safety lines on its interpretation and usages. I added “The Art of” in my own title as the exercise sounds very much like an art and very little like a technical or even less mathematical practice. Even though the call to the resident stat_glm R function is ubiquitous.

The style itself is very story-like, very far from a mathematical statistics book as, e.g., C.R. Rao’s Linear Statistical Inference and Its Applications. Or his earlier Linear Models which I got while drafted in the Navy. While this makes the “Stories” part most relevant, I also wonder how I could teach from this book to my own undergrad students without acquiring first (myself) the massive expertise represented by the opinions and advice on what is correct and what is not in constructing and analysing linear and generalised linear models. In the sense that I would find justifying or explaining opinionated sentences an amathematical challenge. On the other hand, it would make for a great remote course material, leading the students through the many chapters and letting them experiment with the code provided therein, creating new datasets and checking modelling assumptions. The debate between Bayesian and likelihood solutions is quite muted, with a recommendation for weakly informative priors superseded by the call for exploring the impact of one’s assumption. (Although the horseshoe prior makes an appearance, p.209!) The chapter on math and probability is somewhat superfluous as I hardly fathom a reader entering this book without a certain amount of math and stats background. (While the book warns about over-trusting bootstrap outcomes, I find the description in the Simulation chapter a wee bit too vague.) The final chapters about causal inference are quite impressive in their coverage but clearly require a significant amount of investment from the reader to truly ingest these 110 pages.

“One thing that can be confusing in statistics is that similar analyses can be performed in different ways.” (p.121)

Unsurprisingly, the authors warn the reader about simplistic and unquestioning usages of linear models and software, with a particularly strong warning about significance. (Remember Abandon Statistical Significance?!) And keep (rightly) arguing about the importance of fake data comparisons (although this can be overly confident at times). Great Chapter 11 on assumptions, diagnostics and model evaluation. And terrific Appendix B on 10 pieces of advice for improving one’s regression model. Although there are two or three pages on the topic, at the very end, I would have also appreciated a more balanced and constructive coverage of machine learning as it remains a form of regression, which can be evaluated by simulation of fake data and assessed by X validation, hence quite within the range of the book.

The document reads quite well, even pleasantly once one is over the shock at the limited amount of math formulas!, my only grumble being a terrible handwritten graph for building copters(Figure 1.9) and the numerous and sometimes gigantic square root symbols throughout the book. At a more meaningful level, it may feel as somewhat US centric, at least given the large fraction of examples dedicated to US elections. (Even though restating the precise predictions made by decent models on the eve of the 2016 election is worthwhile.) The Oscar for the best section title goes to “Cockroaches and the zero-inflated negative binomial model” (p.248)! But overall this is a very modern, stats centred, engaging and careful book on the most common tool of statistical modelling! More stories to come maybe?!