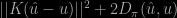Archive for posterior mean

broken random generators

Posted in Statistics with tags , , , , , , on July 22, 2026 by xi'an

Nothing exciting or catastrophic here! Just a Friday afternoon puzzle entry on the successor to The Riddler (which I had not visited for a long while)… The first riddle reads as follows:

A random number generator on my calculator should generate random numbers between 0 and 1. But my suspicion is that the calculator is “tanked,” meaning it only generates random numbers between 0 and some value 0 < a < 1. Beyond that, I have no knowledge regarding the value of a. At the moment, it’s equally likely to be any value from 0 to 1. As an experiment, I ask the calculator to generate one random number. It produces a value of exactly 0.5. Based on this result, what can I expect the value of a to be, on average?

This is a direct (Bayesian) calculation of a posterior expectation when a given x=0.5 (a Uniform (0,a) realisation) is distributed as 1/(a log(2)) over (½,1), with expectation 1/(2 log(2)), about 0.72.

The added riddle just modifies the conditioning event (bringing it closer to Bayes experiment):

A second calculator is similarly “tanked.” As before, every value of a between 0 and 1 is equally likely at first. A friend generates one random number and only reveals that it’s somewhere between 0 and 0.5. On average, what can I expect the value of a to be?

This is also a direct (Bayesian) calculation with a Bernoulli output z, with probability min(0.5,a)/a, which results in a posterior expectation of a equal to 3/(4*(1+log(2))), about 0.44. And… I happened to get selected for my (correct) answer to this question!

linearity, reversed

Posted in Books, Kids with tags , , , , , on September 19, 2020 by xi'an

While answering a question on X validated on the posterior mean being a weighted sum of the prior mean and of the maximum likelihood estimator, when the weights do not depend on the data, which is true in conjugate natural exponential family settings, I re-read this wonderful 1979 paper of Diaconis & Ylvisaker establishing the converse, namely that when the linear combination holds, the prior need be conjugate! This holds within exponential families, but I cannot think of a reasonable case outside exponential families where the linearity holds (again with constant weights, as otherwise it always holds in dimension one, albeit with weights possibly outside [0,1]).

MAP or mean?!

Posted in Statistics, Travel, University life with tags , , , on March 5, 2014 by xi'an

“A frequent matter of debate in Bayesian inversion is the question, which of the two principle point-estimators, the maximum-a-posteriori (MAP) or the conditional mean (CM) estimate is to be preferred.”

An interesting topic for this arXived paper by Burger and Lucka that I (also) read in the plane to Montréal, even though I do not share the concern that we should pick between those two estimators (only or at all), since what matters is the posterior distribution and the use one makes of it. I thus disagree there is any kind of a “debate concerning the choice of point estimates”. If Bayesian inference reduces to producing a point estimate, this is a regularisation technique and the Bayesian interpretation is both incidental and superfluous.

Maybe the most interesting result in the paper is that the MAP is expressed as a proper Bayes estimator! I was under the opposite impression, mostly because the folklore (and even The Bayesian Core)  have it that it corresponds to a 0-1 loss function does not hold for continuous parameter spaces and also because it seems to conflict with the results of Druihlet and Marin (BA, 2007), who point out that the MAP ultimately depends on the choice of the dominating measure. (Even though the Lebesgue measure is implicitly chosen as the default.) The authors of this arXived paper start with a distance based on the prior; called the Bregman distance. Which may be the quadratic or the entropy distance depending on the prior. Defining a loss function that is a mix of this Bregman distance and of the quadratic distance

||K(\hat u-u)||^2+2D_\pi(\hat u,u)

produces the MAP as the Bayes estimator. So where did the dominating measure go? In fact, nowhere: both the loss function and the resulting estimator are clearly dependent on the choice of the dominating measure… (The loss depends on the prior but this is not a drawback per se!)