 One morning session on optimal transport after first-hand witnessing the impressive ballet of orderly lines entering the subway at Nagoya Station (and a very early run along the river and a high humidity rate, hence the picture of empty street at 5am). With Hugo Lavenant exhibiting optimal rates for Bayesian nonparametrics using Wasserstein distances, Pierre Jacob coupling MCMC chains, and Anya Katsevich investigating non-Gaussian asymptotic distributions in high dimensions (beyond Bernstein-von Mises). Then I tried to attend the session on Bayesian Uncertainty Quantification and Posterior Sampling for Large-Scale Generative Models, but it proved too popular for the number of seats, and I ended up discussing with others. After a nap related to my jetlag induced, early, rise I went back to chair Sid Chib’s Foundation Lecture, where he discussed the use of an orbit of models in Bayesian model choice, rather than the (MAP) most likely one. Based on their 2018 JASA paper which I already discussed in Paris with Anna Simoni presenting. Hence reminding me of points I presumably already made, from the issue of having too many models to realistically explore to constructing coherent priors across them, with the fractional, empirical, proxy of using a (same) fraction of the sample as a learning sample, to more philosophical issues like missing a utility function about having to chose a model, especially with all models being wrong, missing an uncertainty quantification on the evidence itself, rather than using most likely models (MAP!), called an orbit by Sid (which requires some calibration). Since the uncertainty represented by the sample induces an uncertainty in the ranking of models. And a most appropriate, almost local, occurrence of the Rashomon principle!!! And I finished the day mixing with many friends in the poster session¹, where Darren Wraith presented our ongoing work on novel, adaptive, importance, sampling.
Archive for Sid Chib
ISBA 2026²
Posted in Books, pictures, Running, Statistics, Travel, University life with tags Bayesian model averaging, Bayesian model choice, Bernstein-von Mises theorem, Chib's approximation, evidence, ISBA 2026, ISBA World Meeting, Japan, map, model uncertainty, Nagoya, Rashomon, Sid Chib, Wasserstein distance on July 1, 2026 by xi'anghost [parameters] in the [Bayesian] shell
Posted in Books, Kids, Statistics with tags Bayesian model comparison, Bayesian textbook, Brad Carlin, cross validated, Doing Bayesian Data Analysis, model posterior probabilities, Sid Chib, Stack Exchange on August 3, 2017 by xi'an This question appeared on Stack Exchange (X Validated) two days ago. And the equalities indeed seem to suffer from several mathematical inconsistencies, as I pointed out in my Answer. However, what I find most crucial in this question is that the quantity on the left hand side is meaningless. Parameters for different models only make sense within their own model. Hence when comparing models parameters cannot co-exist across models. What I suspect [without direct access to Kruschke’s Doing Bayesian Data Analysis book and as was later confirmed by John] is that he is using pseudo-priors in order to apply Carlin and Chib (1995) resolution [by saturation of the parameter space] of simulating over a trans-dimensional space…
Savage-Dickey supermodels
Posted in Books, Mountains, pictures, Statistics, Travel, University life with tags astrostatistics, Bayes factor, Biometrika, Brad Carlin, bridge sampling, cosmology, encompassing model, MCMC, mixtures of distributions, nested sampling, Péru, Sid Chib on September 13, 2016 by xi'an A. Mootoovaloo, B. Bassett, and M. Kunz just arXived a paper on the computation of Bayes factors by the Savage-Dickey representation through a supermodel (or encompassing model). (I wonder why Savage-Dickey is so popular in astronomy and cosmology statistical papers and not so much elsewhere.) Recall that the trick is to write the Bayes factor in favour of the encompasssing model as the ratio of the posterior and of the prior for the tested parameter (thus eliminating nuisance or common parameters) at its null value,
B10=π(φ⁰|x)/π(φ⁰).
Modulo some continuity constraints on the prior density, and the assumption that the conditional prior on nuisance parameter is the same under the null model and the encompassing model [given the null value φ⁰]. If this sounds confusing or even shocking from a mathematical perspective, check the numerous previous entries on this topic on the ‘Og!
The supermodel created by the authors is a mixture of the original models, as in our paper, and… hold the presses!, it is a mixture of the likelihood functions, as in Phil O’Neill’s and Theodore Kypraios’ paper. Which is not mentioned in the current paper and should obviously be. In the current representation, the posterior distribution on the mixture weight α is a linear function of α involving both evidences, α(m¹-m²)+m², times the artificial prior on α. The resulting estimator of the Bayes factor thus shares features with bridge sampling, reversible jump, and the importance sampling version of nested sampling we developed in our Biometrika paper. In addition to O’Neill and Kypraios’s solution.
The following quote is inaccurate since the MCMC algorithm needs simulating the parameters of the compared models in realistic settings, hence representing the multidimensional integrals by Monte Carlo versions.
“Though we have a clever way of avoiding multidimensional integrals to calculate the Bayesian Evidence, this new method requires very efficient sampling and for a small number of dimensions is not faster than individual nested sampling runs.”
I actually wonder at the sheer rationale of running an intensive MCMC sampler in such a setting, when the weight α is completely artificial. It is only used to jump from one model to the next, which sound quite inefficient when compared with simulating from both models separately and independently. This approach can also be seen as a special case of Carlin’s and Chib’s (1995) alternative to reversible jump. Using instead the Savage-Dickey representation is of course infeasible. Which makes the overall reference to this method rather inappropriate in my opinion. Further, the examples processed in the paper all involve (natural) embedded models where the original Savage-Dickey approach applies. Creating an additional model to apply a pseudo-Savage-Dickey representation does not sound very compelling…
Incidentally, the paper also includes a discussion of a weird notion, the likelihood of the Bayes factor, B¹², which is plotted as a distribution in B¹², most strangely. The only other place I met this notion is in Murray Aitkin’s book. Something’s unclear there or in my head!
“One of the fundamental choices when using the supermodel approach is how to deal with common parameters to the two models.”
This is an interesting question, although maybe not so relevant for the Bayes factor issue where it should not matter. However, as in our paper, multiplying the number of parameters in the encompassing model may hinder convergence of the MCMC chain or reduce the precision of the approximation of the Bayes factor. Again, from a Bayes factor perspective, this does not matter [while it does in our perspective].
a day for comments
Posted in Mountains, Statistics, Travel, University life with tags AISTATS 2014, Bayesian variable selection, Brad Carlin, Cuillin ridge, Gaussian mixture, Gibbs sampler, hierarchical models, Iceland, ICML, Langevin MCMC algorithm, MCMC, Metropolis-Hastings algorithms, mixtures, model complexity, penalisation, reference priors, Reykjavik, RJMCMC, Russian doll, Scotland, sequential Monte Carlo, Sid Chib, Skye, speedup, spike-and-slab prior, variable dimension models on April 21, 2014 by xi'an As I was flying over Skye (with [maybe] a first if hazy perspective on the Cuillin ridge!) to Iceland, three long sets of replies to some of my posts appeared on the ‘Og:
- Dan Simpson replied to my comments of last Tuesday about his PC construction;
- Arnaud Doucet precised some issues about his adaptive subsampling paper;
- Amandine Schreck clarified why I had missed some points in her Bayesian variable selection paper;
- Randal Douc defended the efficiency of using Carlin and Chib (1995) method for mixture simulation.
Thanks to them for taking the time to answer my musings…
Carlin and Chib (1995) for fixed dimension problems
Posted in Books, Kids, Statistics, University life with tags asbestos, Brad Carlin, Jussieu, Paris, Peskun ordering, PhD thesis, pseudo-priors, Sid Chib, Université Pierre et Marie Curie on February 25, 2014 by xi'an Yesterday, I was part of a (public) thesis committee at the Université Pierre et Marie Curie, in down-town Paris. After a bit of a search for the defence room (as the campus is still undergoing a massive asbestos clean-up, 20 years after it started…!), I listened to Florian Maire delivering his talk on an array of work in computational statistics ranging from the theoretical (Peskun ordering) to the methodological (Monte Carlo online EM) to the applied (unsupervised learning of classes shapes via deformable templates). The implementation of the online EM algorithm involved the use of pseudo-priors à la Carlin and Chib (1995), even though the setting was a fixed-dimension one, in order to fight the difficulty of exploring the space of templates by a regular Gibbs sampler. (As usual, the design of the pseudo-priors was crucial to the success of the method.) The thesis also included a recent work with Randal Douc and Jimmy Olsson on ranking inhomogeneous Markov kernels of the type
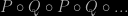
against alternatives with components (P’,Q’). The authors were able to characterise minimal conditions for a Peskun-ordering domination on the components to transfer to the combination. Quite an interesting piece of work for a PhD thesis!


