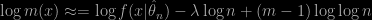Archive for BIC

BayesComp 2025.4

Posted in pictures, Running, Statistics, Travel, University life with tags , , , , , , , , , , , , , , , , , , , , , , , , , , , , , , , , , , , , , , , , , , , , , , , , , , , , , , , , , on June 21, 2025 by xi'an

The third and final day of the (main) conference started tih Emtiyaz Khan’s plenary talk on adaptive Bayesian intelligence. Or, imho, [adaptive [Bayesian]] intelligence, with the brackets indicating redundancy since intelligence need include adaptivity and [intelligent] adaptivity need proceed in a Bayesian way! Focussing first on the Bayesian learning rule via variational Bayes (with a stress on Kingma’s 1994 Adam optimisation algorithm, the “most cited paper” [in machine learning]) where learning boils down to gradient steps (due to the exponential family structure), themselves versions of Taylor (or Laplace) approximations). With an interesting vision of Bayesian updating as accounting for prediction mismatch. (I missed the connection Roberta in IMDb appearing in one slide!)

 The following session offered no dilemma [sorry, Alex, Axel, Chris, Robert, Sumeet, Victor!] since it included the federated learning session I organised, with Louis Asslet, Conor Hassan, and Jean-Michel Marin as speakers. Louis’ talk was on confidential [homomorphic] accept-reject algorithms to learn from other sources, while preserving (differential?) privacy, part of which came during Les Houches workshops I organised this Spring and the one before. Exploiting the additive features of log-likelihoods and exponential variates and adopting a testing perspective on privacy. Conor motivated his model with the Australian cancer atlas project Kerrie Mengersen and others have been developing over the years. The federated approach relies on variational approximations that return the same answer as an exact resolution, but more efficiently. (From a privacy perspective, I wonder at the impact of variational approximations on protecting the data, which boils down to a choice of (sufficient) statistics for the exponential families behind those approximations.) For more complicated models incorporating spatial dependence prohibits full Bayesian inference, unfortunately. Jean-Michel commented on the richness of methods for simulation-based inference, incl. model choice. His focus was on using sequential neural likelihood estimation and sequential importance sampling to approximate evidence. As in the Read Paper of Del Moral et al. (2006). Mentioning a neural version of the harmonic mean estimator by Spurio Mancini et al.  (2023)! I wondered at the degree of (Rao-Blackwell) recycling involved in the computation, Jean-Michel’s answer being that AMIS is soon coming [in a theatre near you!].

The afternoon sessions did offer any reprieve in the choice of topic! I first went to Approximate Methods for Accelerated Sampling, with Rong Tang evaluating the informativeness of summary statistics through a divergence evaluation. Using autoencoders to replace the intractable posterior, with sliced minimal model discrepancy (MMD) and (pseudo?) score matching loss for divergences (reminding me of indirect inference and synthetic likelihood). Yun Yang discussed a variational proposal to estimate the number of components in a mixture model. Surprising given the multimodal structure of mixture posteriors. And the overall irregularity of (evil!) mixture models. But I could not figure out from the talk the form of the approximation.

On the food scene, tasted a nice and spicy Peranakan rice vermicelli dish called Mee Siam yesterday in a campus restaurant, which sustained me fore the rest of the day, including the ABC s/webinar. And another spicy hot pot today at NUS, to catch up on veggies, while missing the chili crab local specialty on that trip.

Bayesian Inference: Theory, Methods, Computations [book review]

Posted in Statistics with tags , , , , , , , , , , , , , , , , , , , , , on November 12, 2024 by xi'an

Bayesian Inference: Theory, Methods, Computations by Silvelyn Zwanzig and Rauf Ahmad, both from Uppsala University, is a recent book published by Chapman & Hall / CRC Press. About 300p long (plus appendices), it covers the core aspects of Bayesian inference, namely the decision theoretic motivations, its asymptotic validation, the specifics of estimation and testing, and the computational approximations (MC, MCMC, ABC, VB), with entries on prior specification and Normal linear models. And some R codes. It is (and feels like) constructed from Master and PhD courses (at Uppsala University), with a rigorous mathematical presentation and many examples, some related to biostatistics. Drawings from the first author’s daughter are included in most chapters, to this reviewer’s bemusement. From a further personal viewpoint, the book also reads rather close to my (Bayesian) choice of a Bayesian textbook, which proves rather accurate since several chapters are inspired by my own Bayesian Choice. as acknowledged therein. As well as by the more recent Statistical Decision Theory: Estimation, Testing, and Selection by Liese & Miescke (2008) and Introduction to the Theory of Statistical Inference by Liero & Zwanzig (2011). Witness, for instance, an example of prior construction for capture-recapture experiments on lizards as analysed by my PhD student Dupuis (1995) [with a curious switch to the authors on p.263] and  also included in The Bayesian Choice (with drawing 2.9 incorrect in that the lizards there have marks on their backs, instead of the code adopted by the ecologists, namely cutting one specific phalange for each capture).

Other minor quandaries: The usual issue of quoting the wrong edition for creating a method, as when citing Jeffreys (1946) for inventing non-informative priors [p.53], failing to point out the parameterisation invariance of intrinsic losses [p.95]considering that Bayes factors are only relevant for obtaining evidence against the null hypothesis [p.216], recommending BIC and DIC (!) [pp.232-6], advocating sampling importance resampling (SIR) for approximate sampling from the target (omitting infinite variance issues) [p.253], defining annealing as using “several trial distributions” [p.261], a mistake in ABC-MCMC [p.274] since the case when the simulated data is too far from the actual data should lead to a repetition rather than a pure rejection.

All in all, a reasonable textbook with some recent input, but still lacking in originality, if I may subjectively say so.

[Disclaimer about potential self-plagiarism: this post or an edited version of it could possibly appear in my Books Review section in CHANCE.]

Measuring abundance [book review]

Posted in Books, Statistics with tags , , , , , , , , , , , , on January 27, 2022 by xi'an

This 2020 book, Measuring Abundance:  Methods for the Estimation of Population Size and Species Richness was written by Graham Upton, retired professor of applied statistics, for the Data in the Wild series published by Pelagic Publishing, a publishing company based in Exeter.

“Measuring the abundance of individuals and the diversity of species are core components of most ecological research projects and conservation monitoring. This book brings together in one place, for the first time, the methods used to estimate the abundance of individuals in nature.”

Its purpose is to provide a collection of statistical methods for measuring animal abundance or lack thereof. There are four parts: a primer on statistical methods, going no further than maximum likelihood estimation and bootstrap. The term Bayesian only occurs once, in connection with the (a-Bayesian) BIC. (I first spotted a second entry, until I realised this was not a typo and the example truly was about Bawean warty pigs!) The second part is about stationary (or static) individuals, such as trees, and it mostly exposes different recognised ways of sampling, with a focus on minimising the surveyor’s effort. Examples include forestry sampling (with a chainsaw method!) and underwater sampling. There is very little statistics involved in this part apart from the rare appearance of a MLE with an asymptotic confidence interval. There is also very little about misspecified models, except for the occasional warning that the estimates may prove completely wrong. The third part is about mobile individuals, with capture-recapture methods receiving the lion’s share (!). No lion was actually involved in the studies used as examples (but there were grizzly bears from Yellowstone and Banff National Parks). Given the huge variety of capture-recapture models, very little input is found within the book as the practical aspects are delegated to R software like the RMark and mra packages. Very little is written on using covariates or spatial features in such models, mostly dedicated to printed output from R packages with AIC as the sole standard for comparing models. I did not know of distance methods (Chapter 8), which are less invasive counting methods. They however seem to rely on a particular model of missing on individuals as the distance increases. The last section is about estimating the number of species. With again a model assumption that may prove wrong. With the inclusion of diversity measures,

The contents of the book are really down to earth and intended for field data gatherers. For instance, “drive slowly and steadily at 20 mph with headlights and hazard lights on ” (p.91) or “Before starting to record, allow fish time to acclimatize to the presence of divers” (p.91). It is unclear to me how useful the book would prove to be for general statisticians, apart from revealing the huge diversity of methods actually employed in the field. To either build upon these or expose students to their reassessment. More advanced books are McCrea and Morgan (2014), Buckland et al. (2016) and the most recent Seber and Schofield (2019).

[Disclaimer about potential self-plagiarism: this post or an edited version will eventually appear in my Book Review section in CHANCE.]

estimating the marginal likelihood (or an information criterion)

Posted in Books, pictures, Statistics, University life with tags , , , , , , , , , , , on December 28, 2019 by xi'an

Tory Imai (from Kyoto University) arXived a paper last summer on what first looked like a novel approximation of the marginal likelihood. Based on the variance of thermodynamic integration. The starting argument is that there exists a power 0<t⁰<1 such that the expectation of the logarithm of the product of the prior by the likelihood to the power t⁰ or t⁰-powered likelihood  is equal to the standard log-marginal

\log m(x) = \mathbb{E}^{t^0}[ \log f(X|\theta) ]

when the expectation is under the posterior corresponding to the t⁰-powered likelihood (rather than the full likelihood). By an application of the mean value theorem. Watanabe’s (2013) WBIC replaces the optimum t⁰ with 1/log(n), n being the sample size. The issue in terms of computational statistics is of course that the error of WBIC (against the true log m(x)) is only characterised as an order of n.

The second part of the paper is rather obscure to me, as the motivation for the real log canonical threshold is missing, even though the quantity is connected with the power likelihood. And the DIC effective dimension. It then goes on to propose a new approximation of sBIC, where s stands for singular, of Drton and Plummer (2017) which I had missed (and may ask my colleague Martin later today at Warwick!). Quickly reading through the later however brings explanations about the real log canonical threshold being simply the effective dimension in Schwarwz’s BIC approximation to the log marginal,

\log m(x) \approx= \log f(x|\hat{\theta}_n) - \lambda \log n +(m-1)\log\log n

(as derived by Watanabe), where m is called the multiplicity of the real log canonical threshold. Both λ and m being unknown, Drton and Plummer (2017) estimate the above approximation in a Bayesian fashion, which leads to a double indexed marginal approximation for a collection of models. Since this thread leads me further and further from a numerical resolution of the marginal estimation, but brings in a different perspective on mixture Bayesian estimation, I will return to this highly  in a later post. The paper of Imai discusses a different numerical approximation to sBIC, With a potential improvement in computing sBIC. (The paper was proposed as a poster to BayesComp 2020, so I am looking forward discussing it with the author.)


Lindley’s paradox as a loss of resolution

Posted in Books, pictures, Statistics with tags , , , , , , , , on November 9, 2016 by xi'an

“The principle of indifference states that in the absence of prior information, all mutually exclusive models should be assigned equal prior probability.”

lindleypColin LaMont and Paul Wiggins arxived a paper on Lindley’s paradox a few days ago. The above quote is the (standard) argument for picking (½,½) partition between the two hypotheses, which I object to if only because it does not stand for multiple embedded models. The main point in the paper is to argue about the loss of resolution induced by averaging against the prior, as illustrated by the picture above for the N(0,1) versus N(μ,1) toy problem. What they call resolution is the lowest possible mean estimate for which the null is rejected by the Bayes factor (assuming a rejection for Bayes factors larger than 1). While the detail is missing, I presume the different curves on the lower panel correspond to different choices of L when using U(-L,L) priors on μ… The “Bayesian rejoinder” to the Lindley-Bartlett paradox (p.4) is in tune with my interpretation, namely that as the prior mass under the alternative gets more and more spread out, there is less and less prior support for reasonable values of the parameter, hence a growing tendency to accept the null. This is an illustration of the long-lasting impact of the prior on the posterior probability of the model, because the data cannot impact the tails very much.

“If the true prior is known, Bayesian inference using the true prior is optimal.”

This sentence and the arguments following is meaningless in my opinion as knowing the “true” prior makes the Bayesian debate superfluous. If there was a unique, Nature provided, known prior π, it would loose its original meaning to become part of the (frequentist) model. The argument is actually mostly used in negative, namely that since it is not know we should not follow a Bayesian approach: this is, e.g., the main criticism in Inferential Models. But there is no such thing as a “true” prior! (Or a “true’ model, all things considered!) In the current paper, this pseudo-natural approach to priors is utilised to justify a return to the pseudo-Bayes factors of the 1990’s, when one part of the data is used to stabilise and proper-ise the (improper) prior, and a second part to run the test per se. This includes an interesting insight on the limiting cases of partitioning corresponding to AIC and BIC, respectively, that I had not seen before. With the surprising conclusion that “AIC is the derivative of BIC”!