Archive for ASC 2012

Seminal ideas and controversies in Statistics [book review]

Posted in Books, Mountains, pictures, Statistics, Travel, University life with tags , , , , , , , , , , , , , , , , , , , , , , , , , , , , , , , , , , , , , , , , , , , , , , , , , , , , , , , , , , , , , , , , on May 24, 2025 by xi'an

CRC Press sent CHANCE this book for review. Since the topic was of clear interest to me, with an author who significantly contributed to the field—my only recollection meeting Roderick Little was during the Australian Statistical Conference in Adelaïde, in 2012, at the start of my Oz 2012 Tour!—, I took the opportunity of the nearest weekend to browse through Seminal ideas and controversies in Statistics. I like very much the idea of selecting a dozen key papers in the history of Statistics and of discussing why. In fact, this reminded me of my classics seminar, which lasted the few years I was 100% in charge of the Master program in Dauphine (and which I hope I could restart!). Checking the list of the papers I then suggested my students, I see some overlap with 9 papers out of the 15 groups. (I also remember Steve Fienberg making suggestions for that list, while he was spending a sabbatical in Paris at CREST.) Given that community of focus and purpose, and contrary to my wont, I have really very little of substance to criticize or wish about the book. The less when reading the following

“On a personal note, I met Yates [author of a 1984 paper on tests for 2×2 contingency tables discussing the relevance of conditioning on one or both margins], a charming man, when I was a young graduate student who knew next to nothing about statistics; we discussed the joys of traversing the Cuillin Ridge in Skye.”

since completing that ridge remains high in my mountain-climbing bucket-list! (Possibly next year, since we are running an ICMS workshop on the Island.)

The first paper in the series is more than a foundational paper since (The) Fisher’s 1922 paper is about creating (almost) ex nihilo the field of (modern) mathematical statistics. I don’t know if there is any equivalence in other scientific disciplines of such an impact (and of such a man)… Roderick Little manages to convincingly engage with Fisher’s dismissive views on (not yet called) Bayesian analysis, although, to the latter’s defence, the formalisation of Bayesian inference at that time had not yet emerged. The second chapter is discussing Yates’ 1984 paper on tests for 2×2 contingency tables that he wrote 50 years after writing the original one in the first volume of JRSS. Roderick Little adds a detailed Bayesian analysis with the three standard reference priors, Jeffreys’ version proving quite close to Fisher’s exact test (conditional on both margins). The third chapter is aiming at the generic challenge of hypothesis testing, from the well-known opposition between Fisher and Neyman (both on the cover), to questioning the sanity of hard-set thresholds (with a mention of our American Statistician call to abandon (shi)p!). The later (thus) refers to the recent literature on the replicability crisis and the now famous ASA statement on p-values by Ron Wasserstein and Nicole Lazar, analysed in the chapter. But I would have like to read another full section on alternatives to hypothesis testing. While now a niche interest (imho), Fisher’s attempt at creating a posterior distribution without a prior, aka fiducial inference, is discussed in Chapter 4 with the Behrens-Fisher problem as the illustrating example. The chapter feels rather anticlimactic, with the comparison relying on the (Malay) Ghosh and Kim (2001) simulation results.

Birnbaum’s (1962) likelihood principle is the topic of Chapter 5 (and I cannot remember any of my students choosing this paper over the years, although there was at least one). Roderick Little recalls some sentences from the JASA discussion as an appetiser, a reminder of the time when these discussions could turn in scathing attacks. The chapter contains excerpts from Berger and Wolpert (1988)—which they were writing while I was spending a year at Purdue and which I have always recommended to my PhD students, albeit not for the classic seminar. It then moves to the controversies that surround this principle since its inception, in particular those accumulated by Deborah Mayo (also on the cover) as reported on the ‘Og. In the recent years, I have become less excited about the LP, in part due to the imprecision in its statement, which opens the door to conflicting interpretations. And in part due to the scarcity of models with non-trivial sufficient statistics. (I am also wondering if the sufficiency issue we highlighted in our ABC model choice criticism does relate to the mixture example at the end of the chapter.)

The next chapter is one all for compromise, through the calibrated Bayes perspective that credible statements should be close to confidence statements in the long run. Which I remember him presenting at ASC 2012. The concept is found in the very 1984 paper by Don Rubin (also on the cover) that contains the concept behind Approximate Bayesian Computation (ABC). And the chapter proceeds by listing strengths and weaknesses of frequentist and Bayesian perspectives, towards a fusion of both., e.g. though posterior predictive checks.

While the choice of a (general public) paper from Scientific American may sound surprising in Chapter 7, with Efron’s (on the cover) and Morris’ 1977 Stein’s paradox, I cannot but applaud, the more because this was the first paper I read when starting my PhD on the James-Stein estimators. Although this may sound like happening eons ago, the James and Stein (1961) paper—which is my age!—”created a considerable backlash” by toppling unbiasedness from its pedestal and exhibiting a paradox that 1+1+1≠3… Which Little reinterprets via a random effect (or Bayesian hierarchical) model. (And a chapter where I learned that Little’s father was a journalist, a characteristic he shared with Bruce Lindsay, as I found at Blonde, Glasgow, during an ICMS workshop). Relatedly, the next chapter is about the “57 varieties [of regression] paper” by Demptster, Schatzoff and Wermuth (1977). Apparently connected with Heinz 57 varieties of pickles. The paper considers Stein and ridge and variable selections versions for variable selection. The chapter also covers (Bayesian) Lasso and BART, as well as a brief all too brief mention of Spike & Slab priors—with my friend Veronika Ročková missing from the authors’ index!—,  but I was expecting from the title other, robust, forms of regression like L¹ regression and econometrics digressions. Chapter 10 can however been seen as a proxy since covering generalized estimating equations from a 1986 Biometrika paper of Liang and Zeger, with no Bayesian aspect (and an expected appearance of Communications in Statistics B).

Chapter 9 covers the almost immediately classic 1995 paper of Benjamini and Hochbeg on multiple regressions (that Series B turned into a discussion paper ten years later!). Although it spends more time on Berry’s (2012) recommendations than on FDR. The computational Chapter 11 brings together Efron’s (1979) bootstrap [with his picture on the cover] and MCMC, represented by the founding paper of Gelfand and Smith (1990, if mistakenly set in 1988 on p140). A bit of a strange mix imho as the former is more inferential than computational. And not giving the EM algorithm that much space. And not questioning MCMC methods as a good proxy to posterior distributions. Tukey’s Future of Data Analysis (as founding exploratory data analysis) and Breiman’s Two cultures (as launching statistical machine learning) meet in Chapter 12. (With a reminder that the latter invokes Occam’s razor—which may not be that appropriate for hugely overparameterised machine learning black boxes—and…the Rashomon principle! Meaning that distinct models may all fit the same data. Let me nitpickingly add the reference to Ryûnosuke Akutagawa as the author of Rashômon and other stories that Kurosawa adapted in his splendid movie). The chapter contains critical remarks from David Cox, Brad Efron, David Bickel, and Andrew Gelman, with a further section on Little’s view on modelling.

The last three chapters are on design and sampling, in connection with Little’s (and Rubin’s) works in the area. With a 1934 paper of Neyman (whose picture on the cover could have been chosen differently, albeit no fault of Neyman [or of Little!] that his toothbrush style of moustache dramatically got out of fashion!). With a return to calibrated Bayes and a reminiscence of Little’s time at the World Fertility Survey but (apparently) no mention of the probabilistic aspects of modern censuses (that saw my friends Steve Fienberg on the one side and Larry Brown and Marty Wells on the other side argue for and against it!), again relating to the reliance on statistical models. Chapter 14 relates randomized clinical trials to causality, which makes a (worthy) appearance there. Roderick Little also makes a clear case there against the retracted study linking vaccines and autism, a call that will unlikely not reach the current Trump administration and its Secretary of Health.

The book concludes with a list of twenty style and grammar suggestions for improved writing.

As should be crystal-clear from the above, I quite enjoyed the book and would definitely use its reading list in a graduate course whenever the opportunity arises. Once again, some choices are more personal to the author than others, and I would have place more emphasis on the fantastic Dawid, Stone and Zidek (1973)—with Jim Zidek also missing from the author index—, but all make sense in a walk through statistical classics. Let me however regret the absence therein of major actors like, e.g., D. Blackwell, C.R. Rao,  or G. Wahba (except in a stylistic example p199), two of whom were awarded the International Prize in Statistics.

[Disclaimer about potential self-plagiarism: this post or an edited version will eventually appear in my Books Review section in CHANCE.]

simulating Nature

Posted in Books, Statistics with tags , , , , , , , , , , , , , , , on July 25, 2012 by xi'an

This book, Simulating Nature: A Philosophical Study of Computer-Simulation Uncertainties and Their Role in Climate Science and Policy Advice, by Arthur C. Petersen, was sent to me twice by the publisher for reviewing it for CHANCE. As I could not find a nearby “victim” to review the book, I took it with me to Australia and read it by bits and pieces along the trip.

“Models are never perfectly reliable, and we are always faced with ontic uncertainty and epistemic uncertainty, including epistemic uncertainty about ontic uncertainty.” (page 53)

The author, Arthur C. Petersen, was a member of the United Nations’ Intergovernmental Panel on Climate Change (IPCC) and works as chief scientist at the PBL Netherlands Environmental Assessment Agency. He mentions that the first edition of this book, Simulating Nature, has achieved some kind of cult status, while being now out of print,  which is why he wrote this second edition. The book centres on the notion of uncertainty connected with computer simulations in the first part (pages 1-94) and on the same analysis applied to the simulation of climate change, based on the experience of the author, in the second part (pages 95-178). I must warn the reader that, as the second part got too focussed and acronym-filled for my own taste, I did not read it in depth, even though the issues of climate change and of the human role in this change are definitely of interest to me. (Readers of CHANCE must also realise that there is very little connection with Statistics in this book or my review of it!) Note that the final chapter is actually more of a neat summary of the book than a true conclusion, so a reader eager to get an idea about the contents of the book can grasp them through the eight pages of the eighth chapter.

“An example of the latter situation is a zero-dimensional (sic) model that aggregates all surface temperatures into a single zero-dimensional (re-sic) variable of globally averaged surface temperature.” (page 41)

The philosophical questions of interest therein are that a computer simulation of reality is not reproducing reality and that the uncertainty(ies) pertaining to this simulation cannot be assessed in its (their) entirety. (This the inherent meaning of the first quote, epistemic uncertainty relating to our lack of knowledge about the genuine model reproducing Nature or reality…) The author also covers the more practical issue of the interface between scientific reporting and policy making, which reminded me of Christl Donnelly’s talk at the ASC 2012 meeting (about cattle epidemics in England). The book naturally does not bring answers to any of those questions, naturally because a philosophical perspective should consider different sides of the problem, but I find it more interested in typologies and classifications (of types of uncertainties, in crossing those uncertainties with panel attitudes, &tc.) than in the fundamentals of simulation. I am obviously incompetent in the matter, however, as a naïve bystander, it does not seem to me that the book makes any significant progress towards setting epistemological and philosophical foundations for simulation. The part connected with the author’s implication in the IPCC shed more light on the difficulties to operate in committees and panels made of members with heavy political agendas than on the possible assessments of uncertainties within the models adopted by climate scientists…With the same provision as above, the philosophical aspects do not seem very deep: the (obligatory?!) reference to Karl Popper does not bring much to the debate, because what is falsification to simulation? Similarly, Lakatos’ prohibition of “direct[ing] the modus tollens at [the] hard core” (page 40) does not turn into a methodological assessment of simulation praxis.

“I argue that the application of statistical methods is not sufficient for adequately dealing with uncertainty.” (page 18)

“I agree (…) that the theory behind the concepts of random and systematic errors is purely statistical and not related to the locations and other dimensions of uncertainty.” (page 55)

Statistics is mostly absent from the book, apart from the remark that statistical uncertainty (understood as the imprecision induced by a finite amount of data) differs from modelling errors (the model is not reality), which the author considers cannot be handled by statistics (stating that Deborah Mayo‘s theory of statistical error analysis cannot be extended to simulation, see the footnote on page 55). [In other words, this book has no connection with Monte Carlo Statistical Methods! With or without capitals… Except for a mention of `real’ random number generators on—one of many—footnotes on page 35.]  Mention is made of “subjective probabilities” (page 54), presumably meaning a Bayesian perspective. But the distinction between statistical uncertainty and scenario uncertainty which “cannot be adequately described in terms of chances or probabilities” (page 54) misses the Bayesian perspective altogether, as does the following sentence that “specifying a degree of probability or belief [in such uncertainties] is meaningless since the mechanism that leads to the events are not sufficiently known” (page 54).

“Scientists can also give their subjective probability for a claim, representing their estimated chance that the claim is true. Provided that they indicate that their estimate for the probability is subjective, they are then explicitly allowing for the possibility that their probabilistic claim is dependent on expert judgement and may actually turn out to be false.” (page 57)

In conclusion, I fear the book does not bring enough of a conclusion on the philosophical justifications of using a simulation model instead of the actual reality and on the more pragmatic aspects of validating/invalidating a computer model and of correcting its imperfections with regards to data/reality. I am quite conscious that this is an immensely delicate issue and that, were it to be entirely solved, the current level of fight between climate scientists and climatoskeptics would not persist. As illustrated by the “Sound Science debate” (pages 68-70), politicians and policy-makers are very poorly equipped to deal with uncertainty and even less with decision under uncertainty. I however do not buy the (fuzzy and newspeak) concept of “post-normal science” developed in the last part of Chapter 4, where the scientific analysis of a phenomenon is abandoned for decision-making, “not pretend[ing] to be either value-free or ethically neutral” (page 75).

AMSI-SSAI Lecture #1 at University of Adelaide

Posted in pictures, Statistics, Travel, University life with tags , , , , on July 16, 2012 by xi'an

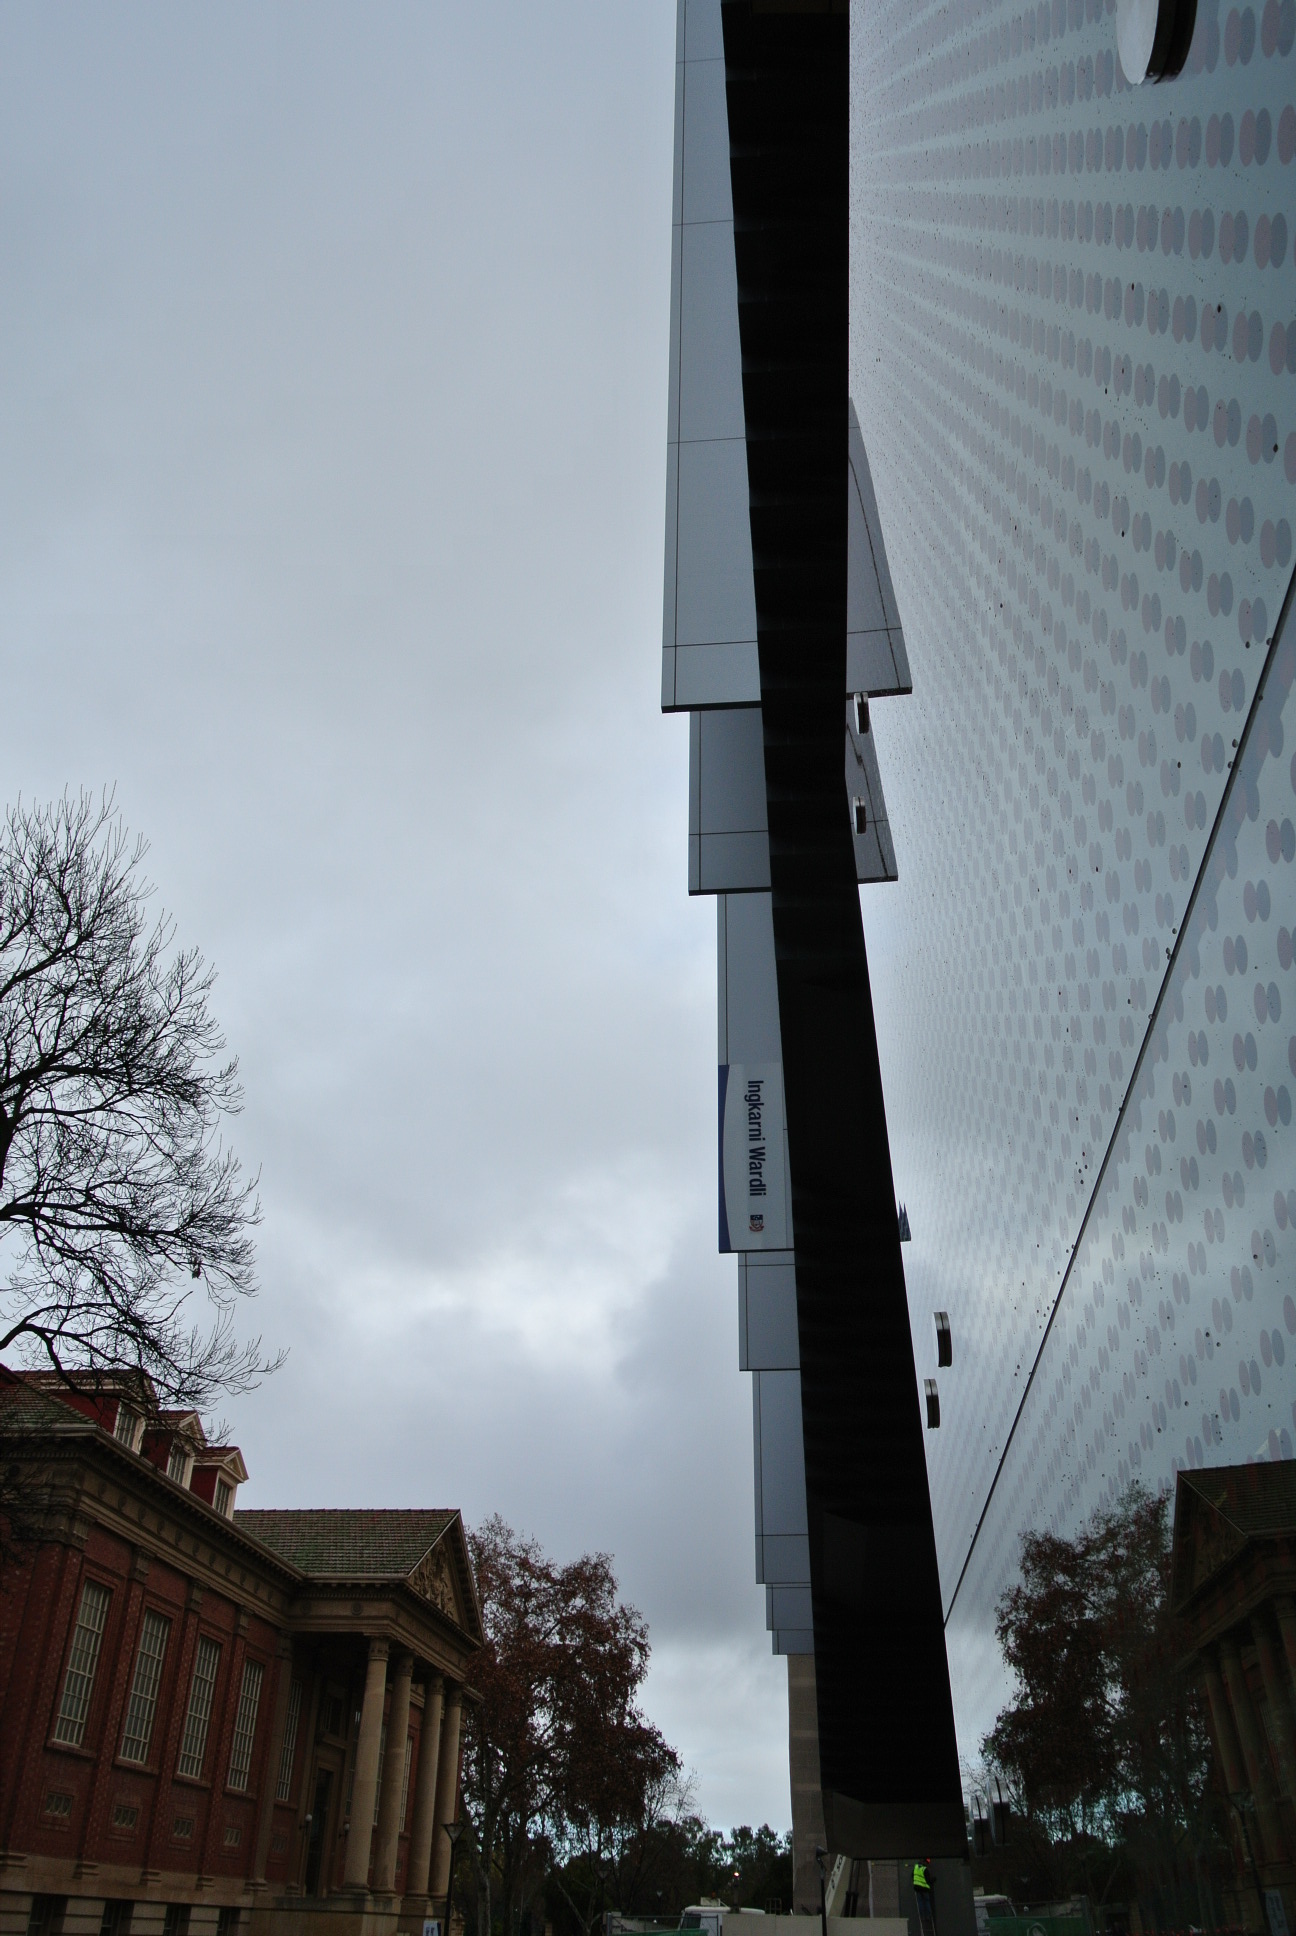
On Friday, I gave my first AMSI Lecture, at the University of Adelaide. The talk attracted a fair number of people, esp. when considering that I had already given a talk on ABC the day before. There also were several interesting questions at the end, mostly related to the (ABC) empirical likelihood part which seems to have a high power of attraction! This talk furthermore gave me the opportunity to visit the superb Ingkarni Wardli building housing math and engineering. This means “house of enquiry” in the local indigenous language, well-suited to a science building indeed! (My next talk is at UNSW on Monday afternoon, the very same talk I gave at the ASC 2012 conference last Thursday.)

ACS 2012 (#2)

Posted in pictures, Running, Statistics, Travel, University life with tags , , , , , , , , , on July 12, 2012 by xi'an

This morning, after a nice and cool run along the river Torrens amidst almost unceasing bird songs, I attended another Bayesian ASC 2012 session with Scott Sisson presenting a simulation method aimed at correcting for biased confidence intervals and Robert Kohn giving the same talk in Kyoto. Scott’s proposal, which is rather similar to parametric bootstrap bias correction, is actually more frequentist than Bayesian as the bias is defined in terms of an correct frequentist coverage of a given confidence (or credible) interval. (Thus making the connection with Roderick Little’s calibrated Bayes talk of yesterday.) This perspective thus perceives ABC as a particular inferential method, instead of a computational approximation to the genuine Bayesian object. (We will certainly discuss the issue with Scott next week in Sydney.)

Then Peter Donnely gave a particularly exciting and well-attended talk on the geographic classification of humans, in particular of the (early 1900’s) population of the British isles, based on a clever clustering idea derived from an earlier paper of Na Li and Matthew Stephens: using genetic sequences from a group of individuals, each individual was paired with the rest of the sample as if it descended from this population. Using an HMM model, this led to clustering the sample into about 50 groups, with a remarkable geographic homogeneity: for instance, Cornwall and Devon made two distinct groups, an English speaking pocket of Wales (Little England) was identified as a specific group and so on, the central, eastern and southern England constituting an homogenous group of its own…

quick impressions from Japan

Posted in pictures, Running, Travel with tags , , , , , , , , , on July 9, 2012 by xi'an

Just like last year trip to Shanghai was my first visit to China, this trip to Kyoto was my first time in Japan. I found the experience so exhilarating that I am already considering a trip back next year! (Especially since I could have lost all of my Kyoto pictures with my hard drive!) The mix of tradition and modernity, of history and high-tech, of chaotic architecture and smooth interactions, of rice fields in the shade of high-rises and of houses in the shade of expressways; all those snapshots, caught from the train as much as from the few hours I spent exploring the modern part of the city, are starting to blur already and I feel a need to go beyond to get a broader and deeper perspective on this fascinating country! Continue reading →