Archive for noise contrasting estimation

gentle importance sampling

Posted in Books, pictures, Statistics with tags , , , , , , , , , , , , on February 24, 2025 by xi'an

A new (and gentle!) survey by Luca Martino! And by Fernando Llorente. On importance sampling, with coverage of normalised and self-normalised versions. And their usage in different configurations (one vs several integrals, one vs several families of distributions). Some points relating to earlier remarks or musing of mine’s:

  • the fact that the optimal importance function does not lead to a zero variance importance estimator when the integrand f is not of constant sign (p.7) can be cancelled by first decomposing f as f⁺-f⁻, since both allow for a zero variance importance estimator, if formally requiring two different samples (of size zero!), a trick considered later on p.18 and repeated for the ratio in self-normalised importance (p.19)
  • the special case when the integrand f is constant is not of practical interest but relevant for checking properties of different estimators. For instance, this case allowed George and myself to spot a mistake in an early importance paper. In the same volume of the Comptes Rendus as an early paper of Lions and Villani.
  • the remark that self-normalised (SNIS) importance sampling can prove more efficient than (properly normalised) importance sampling, although the property that SNIS is always bounded should not be seen as a major point given that it is simply due to using a finite sample and hence a finite set of images of f
  • the case of integrals involving several target pdfs or several integrands is not necessarily of major interest if simulating different samples for each unidimensional integral can be implemented (again formally leading to zero variance at no cost)
  • the issue of merging several estimators in an optimal way is briefly mentioned in §5.4, a challenge Victor Elvira and I have been approaching over the past years, if not yet concluding satisfactorily (mea culpa)
  • when replacing the target with a noisy estimate (p.22), the fact that this estimate must be normalised is correct, but pales against the impact of using this estimate, which may prove catastrophic. And unbiasedness is not particularly crucially important in this setup for the same reason
  • the section on evidence approximation (§7) is more standard, with the harmonic mean estimator being called reverse importance sampling, which brings us to the “elephant in the room”, namely that
  • the issue of infinite variance of some importance sampling estimators is not directly covered (except once in §8, p.34), thus perceiving importance sampling as a variance reduction method being somewhat misleading (unless the authors consider solely the optimal importance function, which is rarely of practical use)

The paper concludes with an interesting notion that

“we suggest the analysis of the relevant connection between importance sampling and contrastive learning Gutmann and Hyvärinen (2012)”

that I also have been pointing out for a while. All in all, a useful summing-up that I will likely suggest to my students.

deep Bayes factor

Posted in Books, pictures, Statistics, University life with tags , , , , , , , , , , , , , , , , on August 8, 2024 by xi'an

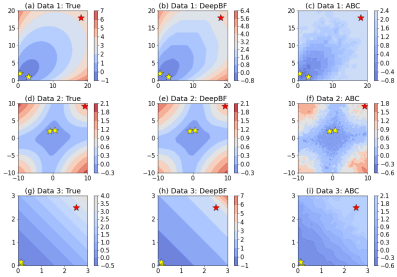
A recently arXived paper proposes an alternative approach to computing Bayes factors via deep learning, Deep Bayes Factors written by Jungeum Kim (presenting her work at JSM this very morning) and Veronika Ročková (whom I have known from her PhD years and whose COPSS Award we very gladly celebrated yesterday!). Which is obviously of interest to me, given my repeated visits to the challenge.

“we introduce Deep Bayes Factor (DeepBF), a neural classifier trained on simulated datasets to learn a mapping whose functional constitutes a Bayes factor estimator.”

Their approach is directly connected with various classification approaches to ABF, incl. the mythical inverse logistic version of Geyer (1994) and noise contrastive estimation of Gutmann and Hyvärinen (2010) (as well as our forested version). Which is called the likelihood-ratio trick here.

“Viewing the Bayes factor through the lens of binary classification aligns with Pudlo et al. (2016), who recast ABC model selection as a classification problem. They employ random forests to select a model by a majority vote. Instead, we focus on binary classification where the purpose is to learn marginal likelihood ratios.  Contrary to the method in Pudlo et al. (2016), our strategy circumvents a secondary learning phase for gauging model posterior estimates, delivering results in only one stage.”

The authors‘ solution stands with learning a classifier from simulated data from both models (and a basic log ratio utility), along iterations updating D from the gradient of the utility, the associated Bayes factor being the ratio D/(1-D) derived from the estimated classifier. There is a cost in producing new samples from the (same) predictives at each iteration (and I wonder if some recycling would be helpful, as well as reducing the sample size for the simpler model). In one of the remarks, the authors point out that “in the effort to see the best ABC performance, we intentionally use the full data Y as a summary statistic”, a remark that I find surprising given the overall consensus that the Bayes factor itself [when based on the full data] is close to optimal.

The method is overall consistent (in the data size n) under classical Bayesian asymptotics, sometimes even when the Bayes factor estimator is inconsistent, naturally expands to pseudo Bayes factors like intrinsic and fractional Bayes factors, also mileage varies in terms of numerical stability.

In the Bayesian model criticism section, the notion of opposing the actual dataset to a simulated one relates very much to Geyer’s (1994) solution. As well as to GANs, as noted in the paper. I did not look closely at the numerical comparisons in the experimental section, but they sound rich enough.

BayesComp²³ [aka MCMski⁶]

Posted in Books, Mountains, pictures, Running, Statistics, Travel, University life with tags , , , , , , , , , , , , , , , , , , , on March 20, 2023 by xi'an

The main BayesComp meeting started right after the ABC workshop and went on at a grueling pace, and offered a constant conundrum as to which of the four sessions to attend, the more when trying to enjoy some outdoor activity during the lunch breaks. My overall feeling is that it went on too fast, too quickly! Here are some quick and haphazard notes from some of the talks I attended, as for instance the practical parallelisation of an SMC algorithm by Adrien Corenflos, the advances made by Giacommo Zanella on using Bayesian asymptotics to assess robustness of Gibbs samplers to the dimension of the data (although with no assessment of the ensuing time requirements), a nice session on simulated annealing, from black holes to Alps (if the wrong mountain chain for Levi), and the central role of contrastive learning à la Geyer (1994) in the GAN talks of Veronika Rockova and Éric Moulines. Victor  Elvira delivered an enthusiastic talk on our massively recycled importance on-going project that we need to complete asap!

While their earlier arXived paper was on my reading list, I was quite excited by Nicolas Chopin’s (along with Mathieu Gerber) work on some quadrature stabilisation that is not QMC (but not too far either), with stratification over the unit cube (after a possible reparameterisation) requiring more evaluations, plus a sort of pulled-by-its-own-bootstrap control variate, but beating regular Monte Carlo in terms of convergence rate and practical precision (if accepting a large simulation budget from the start). A difficulty common to all (?) stratification proposals is that it does not readily applies to highly concentrated functions.

I chaired the lightning talks session, which were 3mn one-slide snapshots about some incoming posters selected by the scientific committee. While I appreciated the entry into the poster session, the more because it was quite crowded and busy, if full of interesting results, and enjoyed the slide solely made of “0.234”, I regret that not all poster presenters were not given the same opportunity (although I am unclear about which format would have permitted this) and that it did not attract more attendees as it took place in parallel with other sessions.

In a not-solely-ABC session, I appreciated Sirio Legramanti speaking on comparing different distance measures via Rademacher complexity, highlighting that some distances are not robust, incl. for instance some (all?) Wasserstein distances that are not defined for heavy tailed distributions like the Cauchy distribution. And using the mean as a summary statistic in such heavy tail settings comes as an issue, since the distance between simulated and observed means does not decrease in variance with the sample size, with the practical difficulty that the problem is hard to detect on real (misspecified) data since the true distribution behing (if any) is unknown. Would that imply that only intrinsic distances like maximum mean discrepancy or Kolmogorov-Smirnov are the only reasonable choices in misspecified settings?! While, in the ABC session, Jeremiah went back to this role of distances for generalised Bayesian inference, replacing likelihood by scoring rule, and requirement for Monte Carlo approximation (but is approximating an approximation that a terrible thing?!). I also discussed briefly with Alejandra Avalos on her use of pseudo-likelihoods in Ising models, which, while not the original model, is nonetheless a model and therefore to taken as such rather than as approximation.

I also enjoyed Gregor Kastner’s work on Bayesian prediction for a city (Milano) planning agent-based model relying on cell phone activities, which reminded me at a superficial level of a similar exploitation of cell usage in an attraction park in Singapore Steve Fienberg told me about during his last sabbatical in Paris.

In conclusion, an exciting meeting that should have stretched a whole week (or taken place in a less congenial environment!). The call for organising BayesComp 2025 is still open, by the way.


evidence estimation in finite and infinite mixture models

Posted in Books, Statistics, University life with tags , , , , , , , , , , , , , on May 20, 2022 by xi'an

Adrien Hairault (PhD student at Dauphine), Judith and I just arXived a new paper on evidence estimation for mixtures. This may sound like a well-trodden path that I have repeatedly explored in the past, but methinks that estimating the model evidence doth remain a notoriously difficult task for large sample or many component finite mixtures and even more for “infinite” mixture models corresponding to a Dirichlet process. When considering different Monte Carlo techniques advocated in the past, like Chib’s (1995) method, SMC, or bridge sampling, they exhibit a range of performances, in terms of computing time… One novel (?) approach in the paper is to write Chib’s (1995) identity for partitions rather than parameters as (a) it bypasses the label switching issue (as we already noted in Hurn et al., 2000), another one is to exploit  Geyer (1991-1994) reverse logistic regression technique in the more challenging Dirichlet mixture setting, and yet another one a sequential importance sampling solution à la  Kong et al. (1994), as also noticed by Carvalho et al. (2010). [We did not cover nested sampling as it quickly becomes onerous.]

Applications are numerous. In particular, testing for the number of components in a finite mixture model or against the fit of a finite mixture model for a given dataset has long been and still is an issue of much interest and diverging opinions, albeit yet missing a fully satisfactory resolution. Using a Bayes factor to find the right number of components K in a finite mixture model is known to provide a consistent procedure. We furthermore establish there the consistence of the Bayes factor when comparing a parametric family of finite mixtures against the nonparametric ‘strongly identifiable’ Dirichlet Process Mixture (DPM) model.