
Archive for CDT
why don’t you wear a suit?!
Posted in Books, Kids, pictures, Travel, University life with tags baby Trump, black Friday, CDT, Centre for Doctoral Training, department of statistics, Des Moines, French Navy, Iowa, John Cairns, journalism, MAGA, objectivity, Oxford, OxWaSP, PhD students, Racoon River Brewing Co., Solidarity with Ukraine, Trump administration, University of Oxford, US politics, USA, Volodymyr Zelenskiy, White House on March 4, 2025 by xi'an
distributed evidence
Posted in Books, pictures, Statistics, University life with tags Bayesian Analysis, Bayesian model choice, belief aggregation, CDT, conditionally conjugate models, conjugate priors, consensus Monte Carlo, CREST, Data augmentation, data privacy, evidence, importance sampling, infinite variance estimators, marginal likelihood, MCMC, OxWaSP, parallel processing, reversible jump MCMC, University of Cambridge on December 16, 2021 by xi'an Alexander Buchholz (who did his PhD at CREST with Nicolas Chopin), Daniel Ahfock, and my friend Sylvia Richardson published a great paper on the distributed computation of Bayesian evidence in Bayesian Analysis. The setting is one of distributed data from several sources with no communication between them, which relates to consensus Monte Carlo even though model choice has not been particularly studied from that perspective. The authors operate under the assumption of conditionally conjugate models, i.e., the existence of a data augmentation scheme into an exponential family so that conjugate priors can be used. For a division of the data into S blocks, the fundamental identity in the paper is

where α is the normalising constant of the sub-prior exp{log[p(θ)]/S} and the other terms are associated with this prior. Under the conditionally conjugate assumption, the integral can be approximated based on the latent variables. Most interestingly, the associated variance is directly connected with the variance of
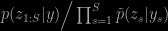
under the joint:
“The variance of the ratio measures the quality of the product of the conditional sub-posterior as an importance sample proposal distribution.”
Assuming this variance is finite (which is likely). An approximate alternative is proposed, namely to replace the exact sub-posterior with a Normal distribution, as in consensus Monte Carlo, which should obviously require some consideration as to which parameterisation of the model produces the “most normal” (or the least abnormal!) posterior. And ensures a finite variance in the importance sampling approximation (as ensured by the strong bounds in Proposition 5). A problem shared by the bridgesampling package.
“…if the error that comes from MCMC sampling is relatively small and that the shard sizes are large enough so that the quality of the subposterior normal approximation is reasonable, our suggested approach will result in good approximations of the full data set marginal likelihood.”
The resulting approximation can also be handy in conjunction with reversible jump MCMC, in the sense that RJMCMC algorithms can be run in parallel on different chunks or shards of the entire dataset. Although the computing gain may be reduced by the need for separate approximations.
NCE, VAEs, GANs & even ABC…
Posted in Statistics with tags ABC, Bayesian GANs, CDT, deep learning, energy based model, generative adversarial networks, noise contrasting estimation, normalising constant, normalising flow, partition function, PhD course, Teams, University of Warwick, variational autoencoders on May 14, 2021 by xi'anAs I was preparing my (new) lectures for a PhD short course “at” Warwick (meaning on Teams!), I read a few surveys and other papers on all these acronyms. It included the massive Guttmann and Hyvärinen 2012 NCE JMLR paper, Goodfellow’s NIPS 2016 tutorial on GANs, and Kingma and Welling 2019 introduction to VAEs. Which I found a wee bit on the light side, maybe missing the fundamentals of the notion… As well as the pretty helpful 2019 survey on normalising flows by Papamakarios et al., although missing on the (statistical) density estimation side. And also a nice (2017) survey of GANs by Shakir Mohamed and Balaji Lakshminarayanan with a somewhat statistical spirit, even though convergence issues are not again not covered. But misspecification is there. And the many connections between ABC and GANs, if definitely missing on the uncertainty aspects. While Deep Learning by Goodfellow, Bengio and Courville adresses both the normalising constant (or partition function) and GANs, it was somehow not deep enough (!) to use for the course, offering only a few pages on NCE, VAEs and GANs. (And also missing on the statistical references addressing the issue, incl. [or excl.] Geyer, 1994.) Overall, the infinite variations offered on GANs leave me uncertain about their statistical relevance, as it is unclear how good the regularisation therein is for handling overfitting and consistent estimation. (And if I spot another decomposition of the Kullback-Leibler divergence, I may start crying…)
PhD studenships at Warwick
Posted in Kids, pictures, Statistics, University life with tags Brexit, CDT, Centre for Doctoral Training in Mathematics and Statistics, computational statistics, European Union, mathematical statistics, OxWaSP, PhD fellowship, University of Warwick on May 2, 2019 by xi'an
There is an exciting opening for several PhD positions at Warwick, in the departments of Statistics and of Mathematics, as part of the Centre for Doctoral Training in Mathematics and Statistics newly created by the University. CDT studentships are funded for four years and funding is open to students from the European Union without restrictions. (No Brexit!) Funding includes a stipend at UK/RI rates and tuition fees at UK/EU rates. Applications are made via the University of Warwick Online Application Portal and should be made as quickly as possible since the funding will be allocated on a first come first serve basis. For more details, contact the CDT director, Martyn Plummer. I cannot but strongly encourage interested students to apply as this is a great opportunity to start a research career in a fantastic department!


