 I just learned that Paul Deheuvels died last week. He was head of the statistics department at Université Pierre & Marie Curie when I was a lecturer there (1987-1992). And a professor of statistics and probability there for his entire career, from 1974 to 2013. While we were working on completely different topics, and had divergent political views, we kept an amicable connection throughout the years, as we were living close enough to meet once in a while at the local farmers’ market and have a quick chat. When I was considering my options for pursuing a PhD, while writing a Master thesis on commutative Lie algebras with his father, René Deheuvels, he was one of the people who offered to supervise me (on a topic related with empirical processes, which were his forte). Later, he suggested I wrote a very short introduction to Bayesian statistics in the Que sais-je? collection (where he published three books) and, when my manuscript was found too theoretical, he proposed to publish an expanded version in the Economica collection, which ended up being the French version of The Bayesian Choice. I also remember a very kind email he sent me while I was recovering from my climbing accident, in 2013, as a fellow climber. (For a long while, he would drive to Fontainebleau once or twice a week for bouldering.) As alluded (to) above, Deheuvels’ political views were very conservative, with a proximity to the far-right Club de l’Horloge and a mix of vieille France traditionalism and libertarianism positions. For sure, he never was shy from embarking in controversies, from defending Allègre’s climato-scepticism to backing Séralini’s controversial study on the cancerogenic effects of Mosanto’s transgenic maize.
Archive for Paul Deheuvels
Paul Deheuvels (1948-2026)
Posted in Books, Mountains, University life with tags Bayesian Choice, Bayesian statistics, Book, bouldering, Bourg-la-Reine, climatosceptic, climbing accident, Club de l'Horloge, Economica, empirical process, Fontainebleau, functional estimation, Jussieu, Monsanto, obituary, Paris, Paris 6, Paul Deheuvels, Que sais-je?, The Bayesian Choice, thumb, transgenic corn, UMPC, Université Pierre et Marie Curie on February 5, 2026 by xi'antransport Monte Carlo
Posted in Books, pictures, Statistics, Travel with tags ABC, Approximate Bayesian computation, BayesComp 2020, Bayesian computation, Dirichlet mixture priors, Gainesville, Gaspard Monge, Hamiltonian Monte Carlo, HMC, macha tea, Monte Carlo error, normalizing flow, optimal transport, Paul Deheuvels, transportation model, University of Florida on August 31, 2020 by xi'an Read this recent arXival by Leo Duan (from UF in Gainesville) on transport approaches to approximate Bayesian computation, in connection with normalising flows. The author points out a “lack of flexibility in a large class of normalizing flows” to bring forward his own proposal.
“…we assume the reference (a multivariate uniform distribution) can be written as a mixture of many one-to-one transforms from the posterior”
The transportation problem is turned into defining a joint distribution on (β,θ) such that θ is marginally distributed from the posterior and β is one of an infinite collection of transforms of θ. Which sounds quite different from normalizing flows, to be sure. Reverting the order, if one manages to simulate β from its marginal the resulting θ is one of the transforms. Chosen to be a location-scale modification of β, s⊗β+m. The weights when going from θ to β are logistic transforms with Dirichlet distributed scales. All with parameters to be optimised by minimising the Kullback-Leibler distance between the reference measure on β and its inverse mixture approximation, and resorting to gradient descent. (This may sound a wee bit overwhelming as an approximation strategy and I actually had to make a large cup of strong macha to get over it, but this may be due to the heat wave occurring at the same time!) Drawing θ from this approximation is custom-made straightforward and an MCMC correction can even be added, resulting in an independent Metropolis-Hastings version since the acceptance ratio remains computable. Although this may defeat the whole purpose of the exercise by stalling the chain if the approximation is poor (hence suggesting this last step being used instead as a control.)

The paper also contains a theoretical section that studies the approximation error, going to zero as the number of terms in the mixture, K, goes to infinity. Including a Monte Carlo error in log(n)/n (and incidentally quoting a result from my former HoD at Paris 6, Paul Deheuvels). Numerical experiments show domination or equivalence with some other solutions, e.g. being much faster than HMC, the remaining $1000 question being of course the on-line evaluation of the quality of the approximation.
maximal spacing around order statistics
Posted in Books, R, Statistics, University life with tags ecdf, extreme value theory, Gumbel distribution, order statistics, Paul Deheuvels, riddle, spacings, The Riddler on May 17, 2018 by xi'an The riddle from the Riddler for the coming weeks is extremely simple to express in mathematical terms, as it summarises into characterising the distribution of
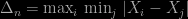
when the n-sample is made of iid Normal variates. I however had a hard time finding a result connected with this quantity since most available characterisations are for either Uniform or Exponential variates. I eventually found a 2017 arXival by Nagaraya et al. covering the issue. Since the Normal distribution belongs to the Gumbel domain of attraction, the extreme spacings, that is the spacings between the most extreme orders statistics [rescaled by nφ(Φ⁻¹{1-n⁻¹})] are asymptotically independent and asymptotically distributed as (Theorem 5, p.15, after correcting a typo):

where the ξ’s are Exp(1) variates. A crude approximation is thus to consider that the above Δ is distributed as the maximum of two standard and independent exponential distributions, modulo the rescaling by nφ(Φ⁻¹{1-n⁻¹})… But a more adequate result was pointed out to me by Gérard Biau, namely a 1986 Annals of Probability paper by Paul Deheuvels, my former head at ISUP, Université Pierre and Marie Curie. In this paper, Paul Deheuvels establishes that the largest spacing in a normal sample, M¹, satisfies
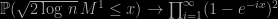
from which a conservative upper bound on the value of n required for a given bound x⁰ can be derived. The simulation below compares the limiting cdf (in red) with the empirical cdf of the above Δ based on 10⁴ samples of size n=10³. The limiting cdf is the cdf of the maximum of an infinite sequence of independent exponentials with scales 1,½,…. Which connects with the above result, in fine. For a practical application, the 99% quantile of this distribution is 4.71. To achieve a maximum spacing of, say 0.1, with probability 0.99, one would need 2 log(n) > 5.29²/0.1², i.e., log(n)>1402, which is a pretty large number…


