Archive for stochastic gradient descent

Elo rating systems via Markov Chains

Posted in pictures, Running, Statistics, University life with tags , , , , , , , , , , , on December 18, 2025 by xi'an

In preparation for meeting with a national sport association towards a Bayesian approach to ranking (I can only confirm this not for volleyball!), I was searching for advanced studies of the Elo (not ELO!) rating system and came across this 2024 arXival by Sam Olesker-Taylor (U Warwick) and Luca Zanetti. Where they analyse the online behaviour of the player ratings and their convergence (in Wasserstein distance), with fairly intricate proofs.

“Elo is not a reversible Markov chain and, while it has a unique stationary distribution, assuming a minor and natural condition, it does not converge to it in total variation.”

The analysis is based on the Bradley–Terry–Luce model of the probability of player i winning a game against player j. Which amounts to a logit or sigmoïd transform of the difference between the players’ true ratings. The practical Elo updates amounts to one stochastic gradient step for the associated likelihood. The authors also propose a random allocation of players into pairs that achieves optimal convergence to the true rating, by maximising the spectral gap of the allocation matrix. Although I did not spot how to derive it in practice.

robust privacy

Posted in Books, Statistics, University life with tags , , , , , , , , , , , , on May 14, 2024 by xi'an

During a recent working session, some Oceanerc (incl. me) went reading Privacy-Preserving Parametric Inference: A Case for Robust Statistics by Marco Avella-Medina (JASA, 2022), where robust criteria are advanced as efficient statistical tools in private settings. In this paper, robustness means using M-estimators T—as function of the empirical cdf—with basis score functions Ψ, defined as
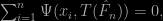
\sum_{i=1}^n\Psi(x_i,T(\hat F_n))=0,

where Ψ is bounded. A construction further requiring that one can assess the sensitivity (in Dwork et al, 2006, sense) of a queried function, sensitivity itself linked with a measure of differential privacy. Because standard robustness approaches à la Huber allow for a portion of the sample to issue from an outlying (arbitrary) distribution, as in ε-contaminations, it makes perfect sense that robustness emerges within the differential framework. However, this common sense perception does not seem good enough for achieving differential privacy and the paper introduces a further randomization with noise scaled by (n,ε,δ) in the following way

T(\hat F_n)+\gamma(T,\hat F_n)5\sqrt{2\log(n)\log(2/\delta)/\epsilon_n}Z

that also applies to test statistics. This scaling seems to constitute the central result of the paper, which establishes asymptotically validity in the sense of statistical consistency (with the sample size n). But I am left wondering whether this outcome counts as supporting differential privacy as a sensible notion…

“…our proofs for the convergence of noisy gradient descent and noisy Newton’s method rely on showing that with high probability, the noise introduced to the gradients and Hessians has a negligible effect on the convergence of the iterates (up to the order of the statistical error of the non-noisy versions of the algorithms).” Avella-Medina, Bradshaw, & Loh

As a sequel I then read a more recent publication of Avella-Medina, Differentially private inference via noisy optimization, written with Casey Bradshaw & Po-Ling Loh, which appeared in the Annals of Statistics (2023). Again considering privatised estimation and inference for M-estimators, obtained by using noisy optimization procedures (noisy gradient descent, noisy Newton’s method) and constructing noisy confidence regions, that output differentially private avatars of standard M-estimators. Here the noisification goes through a randomisation of the gradient step like
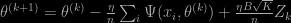
\theta^{(k+1)}=\theta^{(k)}-\frac{\eta}{n}\sum_i\Psi(x_i,\theta^{(k)})+\frac{\eta B\sqrt K}{n}Z_k

where B is an upper bound on the gradient Ψ, η is a discretization step, and K is the total number of iterations (thus fixed in advance). The above stochastic gradient sequence converges with high probability to the actual M-estimator in n and not in K, since the upper bound on the distance scales in √K/n. Where does the attached privacy guarantee come from? It proceeds by an argument of a composition of a sequence of differentially private outputs, all based on the same dataset.

“…the larger the number [K] of data (gradient) queries of the algorithm, the more prone it will be to privacy leakage.”

The Newton method version is a variation on the above stochastic gradient descent. Except it seems to converge faster, as illustrated above.

Bayesian learning

Posted in Statistics with tags , , , , , , , , on May 4, 2023 by xi'an

“…many well-known learning-algorithms, such as those used in optimization, deep learning, and machine learning in general, can now be derived directly following the above scheme using a single algorithm”

The One World ABC webinar today was delivered by Emtiyaz Khan (RIKEN), about the Bayesian Learning Rule, following Khan and Rue 2021 arXival on Bayesian learning. (It had a great intro featuring a video of the speaker’s daughter learning about the purpose of a ukulele in her first year!) The paper argues about a Bayesian interpretation/version of gradient descent algorithms, starting with Zellner’s (1988, the year I first met him!) identity that the posterior is solution to

\min_q \mathbb E_q[\ell(\theta,x)] + KL(q||\pi)

when ℓ is the likelihood and π the prior. This identity can be generalised to an arbitrary loss function (also dependent on the data)  replacing the likelihood and considered for a posterior chosen within an exponential family just as variational Bayes. Ending up with a posterior adapted to this target (in the KL sense). The optimal hyperparameter or pseudo-hyperparameter of this approximation can be recovered by some gradient algorithm, recovering as well stochastic gradient and Newton’s methods. While constructing a prior out of a loss function would have pleased the late Herman Rubin, this is not the case, but rater an approach to deriving a generalised Bayes distribution within a parametric family, including mixtures of Gaussians. At some point in the talk, the uncertainty endemic to the Bayesian approach seeped back into the picture, but since most of the intuition came from machine learning, I was somewhat lost at the nature of this uncertainty.


the Bayesian learning rule [One World ABC’minar, 27 April]

Posted in Books, Statistics, University life with tags , , , , , , , , , , , on April 24, 2023 by xi'an

The next One World ABC seminar is taking place (on-line, requiring pre-registration) on 27 April, 9:30am UK time, with Mohammad Emtiyaz Khan (RIKEN-AIP, Tokyo) speaking about the Bayesian learning rule:

We show that many machine-learning algorithms are specific instances of a single algorithm called the Bayesian learning rule. The rule, derived from Bayesian principles, yields a wide-range of algorithms from fields such as optimization, deep learning, and graphical models. This includes classical algorithms such as ridge regression, Newton’s method, and Kalman filter, as well as modern deep-learning algorithms such as stochastic-gradient descent, RMSprop, and Dropout. The key idea in deriving such algorithms is to approximate the posterior using candidate distributions estimated by using natural gradients. Different candidate distributions result in different algorithms and further approximations to natural gradients give rise to variants of those algorithms. Our work not only unifies, generalizes, and improves existing algorithms, but also helps us design new ones.

far south

Posted in Books, Statistics, Travel, University life with tags , , , , , , , , , , , , on February 23, 2022 by xi'an