 My PhD student Edoardo Bandoni, along with Julien Stoehr and myself, completed a paper on validating (Bayesian) kernel quadrature with unbounded domains of integration. Which connects with probabilistic numerics, since the integrand is modelled as a Gaussian process. And RKHS methods. As opposed to Monte Carlo estimators, quadrature methods approximate integrals of smooth functions with worst-case error decaying at a minimax rate α/d for smoothness α in dimension d. Existing rate-optimal quadrature methods often depend on deterministic point sets tailored to a specific kernel, making them sensitive to misspecification and thus less robust in practice. This paper studies instead randomised quadrature methods, with a focus on robustness rather than on kernel-specific optimality. We construct an explicit, n-dependent, sampling distribution that achieves minimax rates for worst-case errors over smoothness classes without requiring knowledge of the kernel. This kernel-agnostic design does improve robustness while retaining optimal rates and extends Briol et al. (2019) to the unbounded case. Which cannot always be easily handled by a change of variables. Our result thus mostly covers unbounded sampling measures such as Gaussian and Student-t distributions, extending beyond compact domains. The results provide both theoretical guarantees and a practical recipe for robust, rate-optimal, randomised quadrature. [The above is mostly stated in the abstract.]
Archive for Monte Carlo integration
optimal sampling for kernel quadrature on unbounded domains
Posted in Books, Statistics, University life with tags Bayesian quadrature, bois de Boulogne, contraction rate, ERC Synergy Grant, Gaussian processes, minimaxity, Monte Carlo integration, numerical integration, Ocean, probabilistic integration, probabilistic numerics, RKHS, sunset, uncertainty quantification, Université Paris Dauphine on May 22, 2026 by xi'anIn the paper there is y instead of x
Posted in Books, Kids, Statistics, University life with tags cross validated, importance sampling, infinite variance estimators, Monte Carlo integration, reference on October 17, 2023 by xi'an
powering a probability [a Bernoulli factory tale]
Posted in Books, R, Statistics with tags Bernoulli factory, cross validated, Monte Carlo integration on April 21, 2023 by xi'anStarting from an X validated question on finding an unbiased estimator of an integral raised to a non-integer power, I came across a somewhat interesting Bernoulli factory solution! Thanks to Peter Occil’s encyclopedic record of cases, pointing out to Mendo’s (2019) solution for functions of ρ that can be expressed as power series. Like ργ since

which rather magically turns into the reported algorithm
Set k=1
Repeat the following process, until it returns a value x:
 1. Generate a Bernoulli B(ϱ) variate z; if z=1, return x=1
 2. Else, with probability γ/k, return x=0
 3. Else, set k=k+1 and return to 1.
since
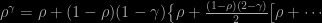
noisy importance sampling
Posted in Statistics with tags approximate Bayesian inference, approximate likelihood, importance sampling, Monte Carlo integration on February 14, 2022 by xi'anA recent short arXival by Fernando Llorente, Luca Martino, Jesse Read, and David Delgado–Gómez in which they analyse settings where (only) a noisy version of the target density is available. Not necessarily in an unbiased fashion although the paper is somewhat unclear as to which integral is targeted in (6), since the integrand is not the original target p(x). The following development is about finding the optimal importance function, which differs from the usual due to the random nature of the approximation, but it does not seem to reconnect with the true target p(x), except when the noisy realisation is unbiased… To me this is a major issue in simulation methodology in that getting away from the unbiasedness constraint opens (rather obviously) a much wider choice of techniques.
what if what???
Posted in Books, Statistics with tags Markov chain Monte Carlo algorithm, MCMC, Monte Carlo integration, Monte Carlo methods, what if?, wikipedia on October 7, 2019 by xi'an[Here is a section of the Wikipedia page on Monte Carlo methods which makes little sense to me. What if it was not part of this page?!]
Monte Carlo simulation versus “what if” scenarios
There are ways of using probabilities that are definitely not Monte Carlo simulations – for example, deterministic modeling using single-point estimates. Each uncertain variable within a model is assigned a “best guess” estimate. Scenarios (such as best, worst, or most likely case) for each input variable are chosen and the results recorded.[55]
By contrast, Monte Carlo simulations sample from a probability distribution for each variable to produce hundreds or thousands of possible outcomes. The results are analyzed to get probabilities of different outcomes occurring.[56] For example, a comparison of a spreadsheet cost construction model run using traditional “what if” scenarios, and then running the comparison again with Monte Carlo simulation and triangular probability distributions shows that the Monte Carlo analysis has a narrower range than the “what if” analysis. This is because the “what if” analysis gives equal weight to all scenarios (see quantifying uncertainty in corporate finance), while the Monte Carlo method hardly samples in the very low probability regions. The samples in such regions are called “rare events”.


