 Throughover the workshop in Chennai floated (!) the figure of Jean/André Ville, with his inequality generalising Markov’s, who invented martingales. He is not such a well-known figure in France—at least to me!—, despite having led a rather exceptional life, from being a visiting scholar in Berlin (in the Maison académique de Berlin, along with a certain Jean-Paul Sartre) and Vienna in the 1930s, to his wife being (in Berlin) one of the many (disposable and despised) lovers of JP Sartre (to whom an open-minded or clueless Ville later sent his thèse d’université on martingales and collectives, a much more substantial piece of work than the current PhD), to him working with German and Austrian mathematicians and logicians, such as Popper, Gödel, and Wald–who, what a coïncidence!, died in India from a plane crash in 1950 that had left from Chennai–and being impressed enough by the latter to passing an economics degree in the Sorbonne when back in Paris, establishing a minimax result for a zero-sum matrix game with two players, to his counter-example to von Mises’ kollectiv, to his nickname of the King of Counterexamples in the Viennese mathematics seminar, to him operating the first (Bull) computer at the Université de Paris. (Glenn Shafer wrote a detailed accounting of his youth, on which this post is based, up to his thesis defence but a few days from France mobilising for war–where his collegue Wolfgang Doeblin would kill himself the year after, to avoid capture–. With Bernard Bru, Edmond Malinvaud and Alain Trognon among the people who helped.) After the war, he worked several years as a prépa maths teacher before working for a French State electricity companion on signal theory and Monte Carlo methods, and then returning to Université de Paris as a professor in 1957.
Archive for Emile Borel
André ou Jean Ville (1910-1989)
Posted in Books, pictures, Travel, University life with tags 25w5482, Abraham Wald, Alain Trognon, André Ville, Andrey Markov, École Normale Supérieure, Berlin, Bernard Bru, BIRS-CMI, Bull computers, Chennai, Edmond Malinvaud, Emile Borel, George Darmois, Glenn Shafer, history of Monte Carlo, history of statistics, India, Jean Ville, Jean-Paul Sartre, Karl Popper, Kurt Gödel, martingales, Maurice Fréchet, minimax strategy, Monte Carlo methods, Paris, Paul Lévy, plane crash, Richard von Mises, signal theory, Simone de Beauvoir, Sorbonne, supermartingale, two-player game, Université de Paris, Vienna, Ville's inequality, Wolfgang Doeblin, WW II on August 12, 2025 by xi'anBorel and Langevin jailed [in 1941]
Posted in Books, Kids, pictures, Statistics, University life with tags Abwehr, Académie des Sciences, anti-fascism, Camille Marbo, collaboration, Collège de France, Emile Borel, French Navy, French resistance, IHP, Institut Henri Poincaré, Jacques Solomon, Lucien Le Cam, Nazi occupation, Paul Langevin, Pétain, Vichy régime, WW II on December 1, 2024 by xi'an

When attending the Le Cam 100th anniversary day at IHP, I learned from Laurent Mazliak’s talk that Émile Borel Borel (then in his 70’s and a member of the French Académie des Sciences) was arrested and jailed for a few weeks in 1941, as well as Paul Langevin (both in 1940 and 1941), for political (left-wing) reasons (?), by German security services (Abwehr), with no involvement of the French collaborationist authorities who rather intervened towards their release (along with the German Navy!, unlikely connected with Borel being the minister of the French Navy in 1924!!). Possibly from denunciations sent to German forces. Possibly as a show of power by the occupying forces towards the Vichy government and Philippe Pétain. The fact that Borel and his wife, Camille Marbo, were actually engaged in the French Resistance at least from 1942 fortunately did not come to the knowledge of French police or German security. (Langevin was one of the founders of the 1934 Comité de vigilance des intellectuels antifascistes. In 1941, his son-in-law, Jacques Solomon, a physicist, got arrested and executed for founding a clandestine newspaper, l’Université libre. His daughter Hélène Solomon-Langevin got deported but survived several deportation camps.)
Estimating means of bounded random variables by betting
Posted in Books, Statistics, University life with tags Abraham Wald, Berlin, betting, ChatGPT, Chernoff method, concentration inequality, confidence intervals, confidence sequence, decision theory, Emile Borel, game theory, Glenn Shafer, Hoeffding, Italian politics, Jean Ville, Jean-Paul Sartre, London, Maurice Fréchet, Read paper, Richard von Mises, Royal Statistical Society, Series B, Simone de Beauvoir, supermartingale on April 9, 2023 by xi'an Ian Waudby-Smith and Aaditya Ramdas are presenting next month a Read Paper to the Royal Statistical Society in London on constructing a conservative confidence interval on the mean of a bounded random variable. Here is an extended abstract from within the paper:
For each m ∈ [0, 1], we set up a “fair” multi-round game of statistician
against nature whose payoff rules are such that if the true mean happened
to equal m, then the statistician can neither gain nor lose wealth in
expectation (their wealth in the m-th game is a nonnegative martingale),
but if the mean is not m, then it is possible to bet smartly and make
money. Each round involves the statistician making a bet on the next
observation, nature revealing the observation and giving the appropriate
(positive or negative) payoff to the statistician. The statistician then plays
all these games (one for each m) in parallel, starting each with one unit of
wealth, and possibly using a different, adaptive, betting strategy in each.
The 1 − α confidence set at time t consists of all m 2 [0, 1] such that the
statistician’s money in the corresponding game has not crossed 1/α. The
true mean μ will be in this set with high probability.
I read the paper on the flight back from Venice and was impressed by its universality, especially for a non-asymptotic method, while finding the expository style somewhat unusual for Series B, with notions late into being defined if at all defined. As an aside, I also enjoyed the historical connection to Jean Ville‘s 1939 PhD thesis (examined by Borel, Fréchet—his advisor—and Garnier) on a critical examination of [von Mises’] Kollektive. (The story by Glenn Shafer of Ville’s life till the war is remarkable, with the de Beauvoir-Sartre couple making a surprising and rather unglorious appearance!). Himself inspired by a meeting with Wald while in Berlin. The paper remains quite allusive about Ville‘s contribution, though, while arguing about its advance respective to Ville’s work… The confidence intervals (and sequences) depend on a supermartingale construction of the form
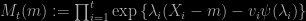
which allows for a universal coverage guarantee of the derived intervals (and can optimised in λ). As I am getting confused by that point about the overall purpose of the analysis, besides providing an efficient confidence construction, and am lacking in background about martingales, betting, and sequential testing, I will not contribute to the discussion. Especially since ChatGPT cannot help me much, with its main “criticisms” (which I managed to receive while in Italy, despite the Italian Government banning the chabot!)
However, there are also some potential limitations and challenges to this approach. One limitation is that the accuracy of the method is dependent on the quality of the prior distribution used to set the odds. If the prior distribution is poorly chosen, the resulting estimates may be inaccurate. Additionally, the method may not work well for more complex or high-dimensional problems, where there may not be a clear and intuitive way to set up the betting framework.
and
Another potential consequence is that the use of a betting framework could raise ethical concerns. For example, if the bets are placed on sensitive or controversial topics, such as medical research or political outcomes, there may be concerns about the potential for manipulation or bias in the betting markets. Additionally, the use of betting as a method for scientific or policy decision-making may raise questions about the appropriate role of gambling in these contexts.
being totally off the radar… (No prior involved, no real-life consequence for betting, no gambling.)
Bertrand-Borel debate
Posted in Books, Statistics with tags Bayes factor, Bayesian hypothesis testing, Bayesian model selection, Bertrand's paradox, conditioning, Deborah Mayo, Emile Borel, Erich Lehmann, Joseph Bertrand, Le Hasard, Pierre Simon Laplace, Pleiades, posterior probability, uniformly most powerful tests on May 6, 2019 by xi'anOn her blog, Deborah Mayo briefly mentioned the Bertrand-Borel debate on the (in)feasibility of hypothesis testing, as reported [and translated] by Erich Lehmann. A first interesting feature is that both [starting with] B mathematicians discuss the probability of causes in the Bayesian spirit of Laplace. With Bertrand considering that the prior probabilities of the different causes are impossible to set and then moving all the way to dismiss the use of probability theory in this setting, nipping the p-values in the bud..! And Borel being rather vague about the solution probability theory has to provide. As stressed by Lehmann.
“The Pleiades appear closer to each other than one would naturally expect. This statement deserves thinking about; but when one wants to translate the phenomenon into numbers, the necessary ingredients are lacking. In order to make the vague idea of closeness more precise, should we look for the smallest circle that contains the group? the largest of the angular distances? the sum of squares of all the distances? the area of the spherical polygon of which some of the stars are the vertices and which contains the others in its interior? Each of these quantities is smaller for the group of the Pleiades than seems plausible. Which of them should provide the measure of implausibility? If three of the stars form an equilateral triangle, do we have to add this circumstance, which is certainly very unlikely apriori, to those that point to a cause?” Joseph Bertrand (p.166)
“But whatever objection one can raise from a logical point of view cannot prevent the preceding question from arising in many situations: the theory of probability cannot refuse to examine it and to give an answer; the precision of the response will naturally be limited by the lack of precision in the question; but to refuse to answer under the pretext that the answer cannot be absolutely precise, is to place oneself on purely abstract grounds and to misunderstand the essential nature of the application of mathematics.” Emile Borel (Chapter 4)

Another highly interesting objection of Bertrand is somewhat linked with his conditioning paradox, namely that the density of the observed unlikely event depends on the choice of the statistic that is used to calibrate the unlikeliness, which makes complete sense in that the information contained in each of these statistics and the resulting probability or likelihood differ to an arbitrary extend, that there are few cases (monotone likelihood ratio) where the choice can be made, and that Bayes factors share the same drawback if they do not condition upon the entire sample. In which case there is no selection of “circonstances remarquables”. Or of uniformly most powerful tests.
severe testing : beyond Statistics wars?!
Posted in Books, pictures, Statistics, Travel, University life with tags Albert Einstein, book review, Cambridge University Press, cup, Deborah Mayo, Don Rubin, Egon Pearson, Emile Borel, gallimaufry, Jerzy Neyman, Likelihood Principle, Markov bar, Melbourne, R.A. Fisher, severe testing, statistical inference, Statistical Inference as Severe Testing, sufficiency, testing of hypotheses on January 7, 2019 by xi'an A timely start to my reading Deborah Mayo’s [properly printed] Statistical Inference as Severe Testing (How to get beyond the Statistics Wars) on the Armistice Day, as it seems to call for just this, an armistice! And the opportunity of a long flight to Oaxaca in addition… However, this was only the start and it took me several further weeks to peruse seriously enough the book (SIST) before writing the (light) comments below. (Receiving a free copy from CUP and then a second one directly from Deborah after I mentioned the severe sabotage!)
Indeed, I sort of expected a different content when taking the subtitle How to get beyond the Statistics Wars at face value. But on the opposite the book is actually very severely attacking anything not in the line of the Cox-Mayo severe testing line. Mostly Bayesian approach(es) to the issue! For instance, Jim Berger’s construct of his reconciliation between Fisher, Neyman, and Jeffreys is surgically deconstructed over five pages and exposed as a Bayesian ploy. Similarly, the warnings from Dennis Lindley and other Bayesians that the p-value attached with the Higgs boson experiment are not probabilities that the particle does not exist are met with ridicule. (Another go at Jim’s Objective Bayes credentials is found in the squared myth of objectivity chapter. Maybe more strongly than against staunch subjectivists like Jay Kadane. And yet another go when criticising the Berger and Sellke 1987 lower bound results. Which even extends to Vale Johnson’s UMP-type Bayesian tests.)
“Inference should provide posterior probabilities, final degrees of support, belief, probability (…) not provided by Bayes factors.” (p.443)
Another subtitle of the book could have been testing in Flatland given the limited scope of the models considered with one or at best two parameters and almost always a Normal setting. I have no idea whatsoever how the severity principle would apply in more complex models, with e.g. numerous nuisance parameters. By sticking to the simplest possible models, the book can carry on with the optimality concepts of the early days, like sufficiency (p.147) and and monotonicity and uniformly most powerful procedures, which only make sense in a tiny universe.
“The estimate is really a hypothesis about the value of the parameter. The same data warrant the hypothesis constructed!” (p.92)
There is an entire section on the lack of difference between confidence intervals and the dual acceptance regions, although the lack of unicity in defining either of them should come as a bother. Especially outside Flatland. Actually the following section, from p.193 onward, reminds me of fiducial arguments, the more because Schweder and Hjort are cited there. (With a curve like Fig. 3.3. operating like a cdf on the parameter μ but no dominating measure!)
“The Fisher-Neyman dispute is pathological: there’s no disinterring the truth of the matter (…) Fisher grew to renounce performance goals he himself had held when it was found that fiducial solutions disagreed with them.”(p.390)
Similarly the chapter on the “myth of the “the myth of objectivity””(p.221) is mostly and predictably targeting Bayesian arguments. The dismissal of Frank Lad’s arguments for subjectivity ends up [or down] with a rather cheap that it “may actually reflect their inability to do the math” (p.228). [CoI: I once enjoyed a fantastic dinner cooked by Frank in Christchurch!] And the dismissal of loss function requirements in Ziliak and McCloskey is similarly terse, if reminding me of Aris Spanos’ own arguments against decision theory. (And the arguments about the Jeffreys-Lindley paradox as well.)
“It’s not clear how much of the current Bayesian revolution is obviously Bayesian.” (p.405)
The section (Tour IV) on model uncertainty (or against “all models are wrong”) is somewhat limited in that it is unclear what constitutes an adequate (if wrong) model. And calling for the CLT cavalry as backup (p.299) is not particularly convincing.
 It is not that everything is controversial in SIST (!) and I found agreement in many (isolated) statements. Especially in the early chapters. Another interesting point made in the book is to question whether or not the likelihood principle at all makes sense within a testing setting. When two models (rather than a point null hypothesis) are X-examined, it is a rare occurrence that the likelihoo
 d factorises any further than the invariance by permutation of iid observations. Which reminded me of our earlier warning on the dangers of running ABC for model choice based on (model specific) sufficient statistics. Plus a nice sprinkling of historical anecdotes, esp. about Neyman’s life, from Poland, to Britain, to California, with some time in Paris to attend Borel’s and Lebesgue’s lectures. Which is used as a background for a play involving Bertrand, Borel, Neyman and (Egon) Pearson. Under the title “Les Miserables Citations” [pardon my French but it should be Les Misérables if Hugo is involved! Or maybe les gilets jaunes…] I also enjoyed the sections on reuniting Neyman-Pearson with Fisher, while appreciating that Deborah Mayo wants to stay away from the “minefields” of fiducial inference. With, mot interestingly, Neyman himself trying in 1956 to convince Fisher of the fallacy of the duality between frequentist and fiducial statements (p.390). Wisely quoting Nancy Reid at BFF4 stating the unclear state of affair on confidence distributions. And the final pages reawakened an impression I had at an earlier stage of the book, namely that the ABC interpretation on Bayesian inference in Rubin (1984) could come closer to Deborah Mayo’s quest for comparative inference (p.441) than she thinks, in that producing parameters producing pseudo-observations agreeing with the actual observations is an “ability to test accordance with a single model or hypothesis”.
“Although most Bayesians these days disavow classic subjective Bayesian foundations, even the most hard-nosed. “we’re not squishy” Bayesian retain the view that a prior distribution is an important if not the best way to bring in background information.” (p.413)
A special mention to Einstein’s cafe (p.156), which reminded me of this picture of Einstein’s relative Cafe I took while staying in Melbourne in 2016… (Not to be confused with the Markov bar in the same city.) And a fairly minor concern that I find myself quoted in the sections priors: a gallimaufry (!) and… Bad faith Bayesianism (!!), with the above qualification. Although I later reappear as a pragmatic Bayesian (p.428), although a priori as a counter-example!

