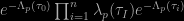Archive for Ockham’s razor

Bayesian workflow [book review]

Posted in Books, R, Statistics, University life with tags , , , , , , , , , , , , , , , , , , , , , , , , , , , , , on October 8, 2026 by xi'an


“This original, thought-provoking, and transforming, book is much much more than an implementation manual for Bayesian Data Analysis, even though it shares almost the same perspective. (The first sentence of the book states that the authors’ `conceptions of statistical practice, and of Bayesian statistics, have changed over the years’.) By providing a modus vivendi for undertaking Bayesian modelling from scratch in realistic settings where models are not magicked out of the blue, the authors explicit and rationalise the many steps required by such a bottom-up modelling protocol (`not a checklist, not a cookbook’, and not a flowchart!) in real situations. The contents read very well and very smoothly, with a seamless conjunction of intuition, modelling advices, computational details, and comparison tools. While unsurprisingly Bayesian, the perspective adopted therein remains both open and inclusive, with a welcome humility about the limitations and challenges of Bayesian workflows. This book should thus appeal to and profit a wide variety of readers, as providing guidance through an extensive collection of highly detailed examples, with shared code and exercises.”

This book proposes a modus vivendi for Bayesian modelling in applied, realistic Bayesian analysis, where models are not magicked out of the blue. It thus emphases iterative model building, model checking, computational troubleshooting, and simulated-data experimentation, filling a gap that looks glaring in retrospect. It particularly targets users and developers of Stan, with code excerpts in R and Stan. It consists of four parts:

  1. background on Bayesian methods and computational tools;
  2. the Bayesian workflow proper, namely building a statistical model from its components, together with its assessment tools;
  3. the computational aspects of fitting models, diagnosing convergence and assessing calibration;
  4. case studies.

I was eagerly waiting for the book, as I knew Andrew, Aki, and Richard had been working on it for a few years. (The quote above is the blurb I wrote upon request from the publisher.)

The tenets of BaWoFlo—if I may resort to this acronym!—are (i) fitting multiple models, (ii) applying methods repeatedly, and (iii) resorting to simulated-data experiments, which should not come as a surprise to readers of BDA. As noted in the introduction, the protocol exposed therein can also benefit non-Bayesian experimenters. This agrees with the highly moderate, “M-open”, agnostic approach to Bayesianism adopted by the authors (“there is no safe haven”). I also welcome and share their humble perspective about the limitations and challenges of Bayesian workflows.

Examples are treated in full detail, with successive modelling and computational choices profusely commented, which is a big plus for such a practical book. This starts as early as Chapter 4, with a multiple-choice exam example. Indeed, there cannot be general principles or a generic theory that would make the approach foolproof. See, e.g., “A data model is not just a ‘likelihood’” (p.70), as when the data model is not fully generative. I very much liked the section on choosing priors (5.6), and the very rich graphs (see, e.g., Chapter 8) for assessing the impact of prior and likelihood, as well as for predictive checks. In coherent continuation of the authors’ earlier work, the book advocates LOO methods and model stacking rather than model averaging. (With a surprisingly anti-Ockham perspective in Section 9.7.)

The MCMC coverage is unsurprising, with \(\hat R\) at the forefront. Chapter 12, on using fast experiments to detect fitting or computational issues, is very nice. The book builds on the immense corpus of work achieved by the authors over the decades (for the most senior ones!). By contrast, the chapter on approximate solutions (13) is way too short, and the same goes for those on calibration and software development.

The book is very US-centric, unsurprisingly given Andrew’s focus on political science. Some sections are reminiscent of Andrew’s blog entries (or the opposite). The (football) World Cup example was initiated when Andrew was in France, during the 2014 World Cup, and as a result (?) the names of the teams are in French! One chapter also reanalyses the birthdate data displayed on the cover of BDA.

Mileage varies on the applied chapters, depending on the example. A dog chapter is followed by a cat chapter! Not that the (stat)dog experiment was in any way enjoyable, especially for the dogs. Maybe the cats were running it! And then come chapters on roaches and sharks. There is also a frightening flowchart (Fig. 2.1)! And the book ends with an appendix on going through BDA to better understand BaWoFlo

[The usual disclaimer applies, namely that this review is likely to appear later in CHANCE, in my book reviews column.]

statistical modeling with R [book review]

Posted in Books, Statistics with tags , , , , , , , , , , , , , , , , , , , , , , , , , , , , , , , , , , , , , , on June 10, 2023 by xi'an

Statistical Modeling with R (A dual frequentist and Bayesian approach for life scientists) is a recent book written by Pablo Inchausti, from Uruguay. In a highly personal and congenial style (witness the preface), with references to (fiction) books that enticed me to buy them. The book was sent to me by the JASA book editor for review and I went through the whole of it during my flight back from Jeddah. [Disclaimer about potential self-plagiarism: this post or a likely edited version of it will eventually appear in JASA. If not CHANCE, for once.]

The very first sentence (after the preface) quotes my late friend Steve Fienberg, which is definitely starting on the right foot. The exposition of the motivations for writing the book is quite convincing, with more emphasis than usual put on the notion and limitations of modeling. The discourse is overall inspirational and contains many relevant remarks and links that make it worth reading it as a whole. While heavily connected with a few R packages like fitdist, fitistrplus, brms (a  front for Stan), glm, glmer, the book is wisely bypassing the perilous reef of recalling R bases. Similarly for the foundations of probability and statistics. While lacking in formal definitions, in my opinion, it reads well enough to somehow compensate for this very lack. I also appreciate the coherent and throughout continuation of the parallel description of Bayesian and non-Bayesian analyses, an attempt that often too often quickly disappear in other books. (As an aside, note that hardly anyone claims to be a frequentist, except maybe Deborah Mayo.) A new model is almost invariably backed by a new dataset, if a few being somewhat inappropriate as in the mammal sleep patterns of Chapter 5. Or in Fig. 6.1.

Given that the main motivation for the book (when compared with references like BDA) is heavily towards the practical implementation of statistical modelling via R packages, it is inevitable that a large fraction of Statistical Modeling with R is spent on the analysis of R outputs, even though it sometimes feels a wee bit too heavy for yours truly.  The R screen-copies are however produced in moderate quantity and size, even though the variations in typography/fonts (at least on my copy?!) may prove confusing. Obviously the high (explosive?) distinction between regression models may eventually prove challenging for the novice reader. The specific issue of prior input (or “defining priors”) is briefly addressed in a non-chapter (p.323), although mentions are made throughout preceding chapters. I note the nice appearance of hierarchical models and experimental designs towards the end, but would have appreciated some discussions on missing topics such as time series, causality, connections with machine learning, non-parametrics, model misspecification. As an aside, I appreciated being reminded about the apocryphal nature of Ockham’s much cited quote “Pluralitas non est ponenda sine necessitate“.

Typo Jeffries found in Fig. 2.1, along with a rather sketchy representation of the history of both frequentist and Bayesian statistics. And Jon Wakefield’s book (with related purpose of presenting both versions of parametric inference) was mistakenly entered as Wakenfield’s in the bibliography file. Some repetitions occur. I do not like the use of the equivalence symbol ≈ for proportionality. And I found two occurrences of the unavoidable “the the” typo (p.174 and p.422). I also had trouble with some sentences like “long-run, hypothetical distribution of parameter estimates known as the sampling distribution” (p.27), “maximum likelihood estimates [being] sufficient” (p.28), “Jeffreys’ (1939) conjugate priors” [which were introduced by Raiffa and Schlaifer] (p.35), “A posteriori tests in frequentist models” (p.130), “exponential families [having] limited practical implications for non-statisticians” (p.190), “choice of priors being correct” (p.339), or calling MCMC sample terms “estimates” (p.42), and issues with some repetitions, missing indices for acronyms, packages, datasets, but did not bemoan the lack homework sections (beyond suggesting new datasets for analysis).

A problematic MCMC entry is found when calibrating the choice of the Metropolis-Hastings proposal towards avoiding negative values “that will generate an error when calculating the log-likelihood” (p.43) since it suggests proposed values should not exceed the support of the posterior (and indicates a poor coding of the log-likelihood!). I also find the motivation for the full conditional decomposition behind the Gibbs sampler (p.47) unnecessarily confusing. (And automatically having a Metropolis-Hastings step within Gibbs as on Fig. 3.9 brings another magnitude of confusion.) The Bayes factor section is very terse. The derivation of the Kullback-Leibler representation (7.3) as an expected log likelihood ratio seems to be missing a reference measure. Of course, seeing a detailed coverage of DIC (Section 7.4) did not suit me either, even though the issue with mixtures was alluded to (with no detail whatsoever). The Nelder presentation of the generalised linear models felt somewhat antiquated, since the addition of the scale factor a(φ) sounds over-parameterized.

But those are minor quibble in relation to a book that should attract curious minds of various background knowledge and expertise in statistics, as well as work nicely to support an enthusiastic teacher of statistical modelling. I thus recommend this book most enthusiastically.

Bayesian thinking for toddler & Bayesian probabilities for babies [book reviews]

Posted in Statistics with tags , , , , , , , , , , on January 27, 2023 by xi'an

My friend E.-J.  Wagenmakers sent me a copy of Bayesian Thinking for Toddlers, “a must-have for any toddler with even a passing interest in Ockham’s razor and the prequential principle.” E.-J. wrote the story and Viktor Beekman (of thesis’ cover fame!) drew the illustrations. The book can be read for free on https://psyarxiv.com/w5vbp/, but not purchased as publishers were not interested and self-publishing was not available at a high enough quality level. Hence, in the end, 200 copies were made as JASP material, with me being the happy owner of one of these. The story follows two young girls competing for dinosaur expertise, and being rewarded by cookies, in proportion to the probability of providing the correct answer to two dinosaur questions. Toddlers may get less enthusiastic than grown-ups about the message, but they will love the drawings (and the questions if they are into dinosaurs).

This reminded me of the Bayesian probabilities for babies book, by Chris Ferrie, which details the computation of the probability that a cookie contains candy when the first bite holds none. It is more genuinely intended for young kids, in shape and design, as can be checked on a YouTube video, with an hypothetical population of cookies (with and without candy) being the proxy for the prior distribution. I hope no baby will be traumatised from being exposed too early to the notions of prior and posterior. Only data can tell, twenty years from now, if the book induced a spike or a collapse in the proportion of Bayesian statisticians!

[Disclaimer about potential self-plagiarism: this post or an edited version will potentially appear in my Books Review section in CHANCE.

Bayes factors revisited

Posted in Books, Mountains, pictures, Statistics, Travel, University life with tags , , , , , , , , , on March 22, 2021 by xi'an


“Bayes factor analyses are highly sensitive to and crucially depend on prior assumptions about model parameters (…) Note that the dependency of Bayes factors on the prior goes beyond the dependency of the posterior on the prior. Importantly, for most interesting problems and models, Bayes factors cannot be computed analytically.”

Daniel J. Schad, Bruno Nicenboim, Paul-Christian Bürkner, Michael Betancourt, Shravan Vasishth have just arXived a massive document on the Bayes factor, worrying about the computation of this common tool, but also at the variability of decisions based on Bayes factors, e.g., stressing correctly that

“…we should not confuse inferences with decisions. Bayes factors provide inference on hypotheses. However, to obtain discrete decisions (…) from continuous inferences in a principled way requires utility functions. Common decision heuristics (e.g., using Bayes factor larger than 10 as a discovery threshold) do not provide a principled way to perform decisions, but are merely heuristic conventions.”

The text is long and at times meandering (at least in the sections I read), while trying a wee bit too hard to bring up the advantages of using Bayes factors versus frequentist or likelihood solutions. (The likelihood ratio being presented as a “frequentist” solution, which I think is an incorrect characterisation.) For instance, the starting point of preferring a model with a higher marginal likelihood is presented as an evidence (oops!) rather than argumented. Since this quantity depends on both the prior and the likelihood, it being high or low is impacted by both. One could then argue that using its numerical value as an absolute criterion amounts to selecting the prior a posteriori as much as checking the fit to the data! The paper also resorts to the Occam’s razor argument, which I wish we could omit, as it is a vague criterion, wide open to misappropriation. It is also qualitative, rather than quantitative, hence does not help in calibrating the Bayes factor.

Concerning the actual computation of the Bayes factor, an issue that has always been a concern and a research topic for me, the authors consider only two “very common methods”, the Savage–Dickey density ratio method and bridge sampling. We discussed the shortcomings of the Savage–Dickey density ratio method with Jean-Michel Marin about ten years ago. And while bridge sampling is an efficient approach when comparing models of the same dimension, I have reservations about this efficiency in other settings. Alternative approaches like importance nested sampling, noise contrasting estimation or SMC samplers are often performing quite efficiently as normalising constant approximations. (Not to mention our version of harmonic mean estimator with HPD support.)

Simulation-based inference is based on the notion that simulated data can be produced from the predictive distributions. Reminding me of ABC model choice to some extent. But I am uncertain this approach can be used to calibrate the decision procedure to select the most appropriate model. We thought about using this approach in our testing by mixture paper and it is favouring the more complex of the two models. This seems also to occur for the example behind Figure 5 in the paper.

Two other points: first, the paper does not consider the important issue with improper priors, which are not rigorously compatible with Bayes factors, as I discussed often in the past. And second, Bayes factors are not truly Bayesian decision procedures, since they remove the prior weights on the models, thus the mention of utility functions therein seems inappropriate unless a genuine utility function can be produced.

Naturally amazed at non-identifiability

Posted in Books, Statistics, University life with tags , , , , , , , , , , , on May 27, 2020 by xi'an

A Nature paper by Stilianos Louca and Matthew W. Pennell,  Extant time trees are consistent with a myriad of diversification histories, comes to the extraordinary conclusion that birth-&-death evolutionary models cannot distinguish between several scenarios given the available data! Namely, stem ages and daughter lineage ages cannot identify the speciation rate function λ(.), the extinction rate function μ(.)  and the sampling fraction ρ inherently defining the deterministic ODE leading to the number of species predicted at any point τ in time, N(τ). The Nature paper does not seem to make a point beyond the obvious and I am rather perplexed at why it got published [and even highlighted]. A while ago, under the leadership of Steve, PNAS decided to include statistician reviewers for papers relying on statistical arguments. It could time for Nature to move there as well.

“We thus conclude that two birth-death models are congruent if and only if they have the same rp and the same λp at some time point in the present or past.” [S.1.1, p.4]

Or, stated otherwise, that a tree structured dataset made of branch lengths are not enough to identify two functions that parameterise the model. The likelihood looks like

\frac{\rho^{n-1}\Psi(\tau_1,\tau_0)}{1-E(\tau)}\prod_{i=1}^n \lambda(\tau_i)\Psi(s_{i,1},\tau_i)\Psi(s_{i,2},\tau_i)$

where E(.) is the probability to survive to the present and ψ(s,t) the probability to survive and be sampled between times s and t. Sort of. Both functions depending on functions λ(.) and  μ(.). (When the stem age is unknown, the likelihood changes a wee bit, but with no changes in the qualitative conclusions. Another way to write this likelihood is in term of the speciation rate λp

e^{-\Lambda_p(\tau_0)}\prod_{i=1}^n\lambda_p(\tau_I)e^{-\Lambda_p(\tau_i)}

where Λp is the integrated rate, but which shares the same characteristic of being unable to identify the functions λ(.) and μ(.). While this sounds quite obvious the paper (or rather the supplementary material) goes into fairly extensive mode, including “abstract” algebra to define congruence.


“…we explain why model selection methods based on parsimony or “Occam’s razor”, such as the Akaike Information Criterion and the Bayesian Information Criterion that penalize excessive parameters, generally cannot resolve the identifiability issue…” [S.2, p15]

As illustrated by the above quote, the supplementary material also includes a section about statistical model selections techniques failing to capture the issue, section that seems superfluous or even absurd once the fact that the likelihood is constant across a congruence class has been stated.