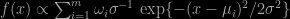Archive for optimisation

6th Workshop on Sequential Monte Carlo Methods (#2)

Posted in Mountains, pictures, Running, Statistics, Travel, University life with tags , , , , , , , , , , , , , , , , , , , , , , , on June 5, 2024 by xi'an

Managed to get back from the Pentland hills in time for the Wednesday afternoon session, which proved most interesting as close to my research interests!

Nicola Branchini presented his work with Victor Elvira (a close friend and coauthor, incidentally one of the organisers of the workshop!) on improving self normalised importance sampling by interpreting it as a ratio of estimators based on two samples (which may be the same) and attempting to optimise the joint distribution of said sample. The starting assumption is having (good) marginal importance functions, which means the goal here is in optimising a copula distribution targeting the ratio as quantity of interest. Optimality is however defined in terms of the approximate asymptotic variance of the ratio, which remains an approximation. The idea is nonetheless quite interesting and shows potential for connecting with bridge sampling and… AMIS! As an aside, the talk considered cases when the margins are multivariate, which requires a généralisation of Sklar’s theorem. Simo Särkä then demonstrated how highly parallel processors like GPUs can accommodate Bayesian filters and smoothers in state space models not requiring simulation, gaining a reduction in complexity from O(T) to O(log T). I had not really thought of parallel processing in the recent years, hence was quite pleased at hearing this resolution based on so-called associative scans, and see that implementations were already available in Julia/CUDA.

This was followed by a highly enjoyable poster session, including chats about ABC-SMC for discovery rates, infinite dimensional diffusions, Pareto smoothed importance samplings, &tc with posters by Hugo Marival (coauthor of our importance Monte Carlo recent paper) and Shreya Roy (a student at U of Warwick). With sunny views of Arthur’s Seat (and plenty of people at the top), contrary to the above! Followed by a private party dinner occupying half of a nearby and novel South Indian restaurant that proved quite tasty, local and definitely enjoyable.

For my last morning in town, albeit it was unrelated to the posted abstract, Pierre Del Moral spoke about noisy versions of the ensemble Kalman filter on linear diffusions that allowed for stable solutions under strong enough conditions, encompassing an impressive corpus of work over the past ten years. Alex Beskos presented antithetic multilevel methods for diffusions, which allow to improve the error in the discretisation, even though I did not fully get the whole idea (partly due to dozing out from time to time, a consequence of my last early rounds of Arthur’s Seat in the very early morn).

Daniel Paulin presented a novel unbiased method based on kinetic Langevin dynamics that combines advanced splitting methods with enhanced gradients, avoiding Metropolis correction by coupling and multilevel Monte Carlo approach, achieving unbiasedness by telescoping, but involving an avalanche of acronyms in the leapfrog/Gibbs steps.  And Adam Johansen (U of Warwick) on several recent papers of their divide-and-conquer filtering methods, introduced in a 2017 JCGS paper, following a decomposition of the state variable into low-dimensional components like branches and leaves of a tree.

simulation as optimization [by kernel gradient descent]

Posted in Books, pictures, Statistics, University life with tags , , , , , , , , , , , , , , , , , , , , , , , , on April 13, 2024 by xi'an

Yesterday, which proved an unseasonal bright, warm, day, I biked (with a new wheel!) to the east of Paris—in the Gare de Lyon district where I lived for three years in the 1980’s—to attend a Mokaplan seminar at INRIA Paris, where Anna Korba (CREST, to which I am also affiliated) talked about sampling through optimization of discrepancies.
This proved a most formative hour as I had not seen this perspective earlier (or possibly had forgotten about it). Except through some of the talks at the Flatiron Institute on Transport, Diffusions, and Sampling last year. Incl. Marilou Gabrié’s and Arnaud Doucet’s.
The concept behind remains attractive to me, at least conceptually, since it consists in approximating the target distribution, known up to a constant (a setting I have always felt standard simulation techniques was not exploiting to the maximum) or through a sample (a setting less convincing since the sample from the target is already there), via a sequence of (particle approximated) distributions when using the discrepancy between the current distribution and the target or gradient thereof to move the particles. (With no randomness in the Kernel Stein Discrepancy Descent algorithm.)
Ana Korba spoke about practically running the algorithm, as well as about convexity properties and some convergence results (with mixed performances for the Stein kernel, as opposed to SVGD). I remain definitely curious about the method like the (ergodic) distribution of the endpoints, the actual gain against an MCMC sample when accounting for computing time, the improvement above the empirical distribution when using a sample from π and its ecdf as the substitute for π, and the meaning of an error estimation in this context.

“exponential convergence (of the KL) for the SVGD gradient flow does not hold whenever π has exponential tails and the derivatives of ∇ log π and k grow at most at a polynomial rate”

Galton and Watson voluntarily skipping some generations

Posted in Books, Kids, R with tags , , , , , on June 2, 2023 by xi'an

A riddle on a form of a Galton-Watson process, starting from a single unit, where no one dies but rather, at each of 100 generations, Dog either opts for a Uniform number υ of additional units or increments a counter γ by this number υ, its goal being to optimise γ. The solution proposed by the Riddler does not establish his solution’s is the optimal strategy and considers anyway average gains. Solution that consists in always producing more units until the antepenultimate hour (ie incrementing only at the 99th and 100th generations),  I tried instead various logical (?) rules and compared outputs by bRute foRce, resulting in higher maxima (over numerous repeated calls) for the alternative principle

s<-function(p=.66){ 
   G=0;K=1 for(t in 1:9){ 
      i=sample(1:K,1) 
      K=K+i*(i>=K*p)
      G=G+i*(i<K*p)}
  return(c(G+sample(1:K,1),K))}

go forth and X [or the reverse]

Posted in Books, Kids with tags , , , , on February 8, 2023 by xi'an

The New Year Riddle is about optimisation: starting with a single machine, between delivering one unit per machine – hour and delivering one new machine per machine every six days, what is the maximal number of units produced over 100 days?

Comparing the amounts produced by k machines after 6log2(k) days used to multiply the machines showed that 2¹⁵ -1 additional machines were first produced, to generate 7864320 items over the remaining 10 days. Which did not really require an R implementation (although I checked that intermediate solutions where only some of the machines were producing new machines were sub-optimal).

master project?

Posted in Books, Kids, Statistics, University life with tags , , , , , , , on July 25, 2022 by xi'an

A potential master project for my students next year inspired by an X validated question: given a Gaussian mixture density

f(x)\propto\sum_{i=1}^m \omega_i \sigma^{-1}\,\exp\{-(x-\mu_i)^2/2\sigma^2\}

with m known, the weights summing up to one, and the (prior) information that all means are within (-C,C), derive the parameters of this mixture from a sufficiently large number of evaluations of f. Pay attention to the numerical issues associated with the resolution.  In a second stage, envision this problem from an exponential spline fitting perspective and optimise the approach if feasible.