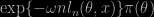Archive for matching priors

a lesser-known correlate of the Jeffreys-Lindley paradox (with discussion)

Posted in Books, pictures, Statistics, University life with tags , , , , , , , , , , , , , , , on October 19, 2024 by xi'an

Two UBC faculty, Harlan Campbell and Paul Gustafson, wrote a paper entitled “Defining a Credible Interval Is Not Always Possible with “Point-Null” Priors: A Lesser-Known Correlate of the Jeffreys-Lindley Paradox” in Bayesian Analysis (2024, 19, Number 3, pp. 925–984), which got discussed and presented on the BA webinar yesterday. I missed the call for discussion, on a topic I would have liked very much to discuss and an analysis I strongly disagree with. Fortunately, several of the discussants in the webinar and in the printed version advanced some of my points (as. e.g., Bertrand Clarke in the above slide screen-shot from the on-line video).

I find the paper somewhat missing in linking with the history of the topic, with no mention of Berger & Sellke (1987) that comes as a counterpoint to Casella &—the other—Berger (1987), opposing one sided to two sided tests. Or of matching priors, which connect credible and confidence intervals to higher orders. But the central issue with the apparent contradiction between rejecting the point null hypothesis and returning a credible interval that contains the null is that the construction proceeds from a model averaged posterior. Which fundamentally contradicts the construct of a pair of priors attached with each model towards selecting the fittest one. And requires a far-from-innocent choice of respective prior weights for both models, an ill-defined notion I have repeatedly criticised here and elsewhere. Model averaging clashes with model selection in both decision-theoretic and modelling terms. In model averaging terms, the disappearance of the opposition exhibited by the authors in the predictive distribution, as shown by discussants Held and Pawel, is unsurprising. And makes the spike-and-slab prior far of a necessity. Contrariwise to the model selection case where it proves unavoidable. And for which a merged credible interval does not make sense (to me at least) since it should be constructed once one (and only one) of the two models is chosen. At this point, that the other model ever was considered should not impact subsequent inference. And within that perspective I do not see the relevance of agnostic (ignoring the model choice ation) 5% confidence or credible regions.

“…considers the regime of a fixed true parameter value as n increases [and] of a fixed p-value…” (p928)

With regards with the connection with the Jeffreys-Lindley (or Lindley-Jeffreys) so-called paradox, on which I have already written a lot (or even too much!), many of the earlier objections resurface. Like the measure-theoretic difficulty in including within a continuous interval an atom, i.e., a value with a point mass. Which isolates this atom away from any other value in the interval (and of course creates discontinuities). Or fixing the p-value forever after (when n goes to infinity), as in the graph below (p929). Or treating an improper prior without further caution than with a proper prior. Especially when these are “created” by the decision problem itself.


Bayes is typically wrong…

Posted in pictures, Running, Statistics, Travel, University life with tags , , , , , , , , , , , on May 3, 2017 by xi'an

In Harvard, this morning, Don Fraser gave a talk at the Bayesian, Fiducial, and Frequentist conference where he repeated [as shown by the above quote] the rather harsh criticisms on Bayesian inference he published last year in Statistical Science. And which I discussed a few days ago. The “wrongness” of Bayes starts with the completely arbitrary choice of the prior, which Don sees as unacceptable, and then increases because the credible regions are not confident regions, outside natural parameters from exponential families (Welch and Peers, 1963). And one-dimensional parameters using the profile likelihood (although I cannot find a proper definition of what the profile likelihood is in the paper, apparently a plug-in version that is not a genuine likelihood, hence somewhat falling under the same this-is-not-a-true-probability cleaver as the disputed Bayesian approach).

“I expect we’re all missing something, but I do not know what it is.” D.R. Cox, Statistical Science, 1994

And then Nancy Reid delivered a plenary lecture “Are we converging?” on the afternoon that compared most principles (including objective if not subjective Bayes) against different criteria, like consistency, nuisance elimination, calibration, meaning of probability, and so on.  In an highly analytic if pessimistic panorama. (The talk should be available on line at some point soon.)

scaling the Gibbs posterior credible regions

Posted in Books, Statistics, University life with tags , , , , , , , on September 11, 2015 by xi'an

“The challenge in implementation of the Gibbs posterior is that it depends on an unspecified scale (or inverse temperature) parameter.”

A new paper by Nick Syring and Ryan Martin was arXived today on the same topic as the one I discussed last January. The setting is the same as with empirical likelihood, namely that the distribution of the data is not specified, while parameters of interest are defined via moments or, more generally, a minimising a loss function. A pseudo-likelihood can then be constructed as a substitute to the likelihood, in the spirit of Bissiri et al. (2013). It is called a “Gibbs posterior” distribution in this paper. So the “Gibbs” in the title has no link with the “Gibbs” in Gibbs sampler, since inference is conducted with respect to this pseudo-posterior. Somewhat logically (!), as n grows to infinity, the pseudo- posterior concentrates upon the pseudo-true value of θ minimising the expected loss, hence asymptotically resembles to the M-estimator associated with this criterion. As I pointed out in the discussion of Bissiri et al. (2013), one major hurdle when turning a loss into a log-likelihood is that it is at best defined up to a scale factor ω. The authors choose ω so that the Gibbs posterior

\exp\{-\omega n l_n(\theta,x) \}\pi(\theta)

is well-calibrated. Where ln is the empirical averaged loss. So the Gibbs posterior is part of the matching prior collection. In practice the authors calibrate ω by a stochastic optimisation iterative process, with bootstrap on the side to evaluate coverage. They briefly consider empirical likelihood as an alternative, on a median regression example, where they show that their “Gibbs confidence intervals (…) are clearly the best” (p.12). Apart from the relevance of being “well-calibrated”, and the asymptotic nature of the results. and the dependence on the parameterisation via the loss function, one may also question the possibility of using this approach in large dimensional cases where all of or none of the parameters are of interest.