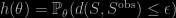Archive for Bayesian synthetic likelihood

statistical accuracy of neural posterior and likelihood estimation

Posted in pictures, Running, Statistics, Travel, University life with tags , , , , , , , , , , , , on March 17, 2025 by xi'an

As I have been aiming at mentioning this news for quite a while, David Frazier, Ryan Kelly, Christopher Drovandi, and David Warne arXived last November a paper that parallels our paper (with David and Gael) on ABC consistency and some earlier papers of theirs for synthetic likelihood in the case of neural posterior approximations, under similar conditions (see, e.g., Assumptions 1 and 2), with potential reduced computational cost in some situations.

“NLE requires additional MCMC steps to produce a posterior approximation, whereas NPE produces a posterior approximation directly and does not require any additional sampling”

Convergence is achieved when the neural  learning size grows fast enough with the sample size. And when the tolerance decreases fast enough with respect to the convergence rate of the summary statistic. Two options are possible, that is either approximating the likelihood and then exploiting this approximation in an MCMC algorithm, or directly approximating the posterior distribution, as a function of of the summary statistic Sn (rather than for the observed S⁰n), with arguments favouring the second option.

“if the intractable posterior Π(· | Sn) is asymptotically Gaussian a nd calibrated, then so long as νnγN = o(1), the NPE is also asymptotically Gaussian and calibrated”

where γN denotes the rate at which the neural approximation of the posterior converges to the ideal posterior (for the Kullback-Leibler divergence) in N the size of the learning sample. And νn is the rate of convergence of the statistic Sn to its asymptotic mean. The convergence result does not make explicit assumptions on the class of neural posteriors, but it requires that the observed statistic must fit within the range of the simulated values (a possibility illustrated in the paper with an MA(2) model that was already used in several of our papers (as I noticed when giving an ABC masterclass in Warwick this very week).

“While neural methods and normalizing flows are common choices for the approximating class Q, the diversity of such methods, along with their complicated tuning and training regimes, makes establishing theoretical results on the rate of convergence, γN,  difficult”

Under stronger and hard to check assumptions, namely on the minimaxity of the posterior density estimator within the class of locally β-Hölder functions, they recover a closed form γN . Which unravels how N should be chosen (with a surprising addition of the dimensions of the parameter θ and of the summary Sn. With a resulting explosion in the theoretical minimal value of N one should use. (And decent performances of the method with smaller values of N!) Concerning minimaxity, I have no intuition how this impacts the sparseness (lack thereof) of the neural networks that can be used.

I am wondering at strategies to remove superfluous statistics since their dimension matters so much and in detecting or evaluating the misspecification (or its complement, the compatibility, as discussed on page 31). But all in all this paper represents a massive addition to the consistency results for approximate Bayesian inference methods!

[strong] foundations of synthetic B’earning

Posted in Books, Statistics, University life with tags , , , , , , , , , , on July 15, 2024 by xi'an

I only recently read the (foundational!) paper on Foundations of Bayesian learnin from synthetic data by Harrison Wilde, Jack Jewson, Sebastian Volmer [all associated with Warwick at some point] and [my long time friend]  Chris Holmes, that merges Bayesian inference with differential privacy constraints thru generalised / Gibbs interface. Recouping with the M-open perspective in order to accommodate the misspecified nature of synthetic data. I like the approach very much in that it intersects a lot with my own views, excepts for following the differential privacy formalism. I however think that further progress could be made by adopting an even more Bayesian position.

Their key messages from that paper are that

  1. learning from synthetic data may prove damaging to your (data) health
  2. robustness unsurprisingly reduces the odds or magnitude of the damage
  3. real data can still be used to some extent

Since the (synthetic) generating model can be a GAN, the privacy requirement is such that noise is “injected” in the input data and in the learning mechanism. This is not discussed in the paper but highly conservative constraints surely make the DGP loose several learning points.

On the side, I also like the alternative of opposing data keeper and learner rather than data owner and adversary. Learning here means taking an optimal B decision about the actual data averaged over the true DGP. With a prior on the distribution of the actual data, while being unable to avoid misspecification in representing the (marginal) synthetic generation model.

Unsurprisingly, the alternative approach is relying on proper scoring rules as Bissiri et al. (2016). Rather than finding the distribution KL closest to the synthetic generative model, robustified by generalised B inference, either via downweighting or via ß-divergence. With a preference for the latter. Interestingly, the authors consider the optimal learning size for the synthetic data. Since bringing in more synthetic data does not mean better performances.

accronyms [CDT lectures]

Posted in Books, Statistics with tags , , , , , , , , , , , , , , , on May 16, 2022 by xi'an

This week, I gave a short and introductory course in Warwick for the CDT (PhD) students on my perceived connections between reverse logistic regression à la Geyer and GANS, among other things. The first attempt was cancelled in 2020 due to the pandemic, the second one in 2021 was on-line and thus offered little possibilities for interactions. Preparing for this third attempt made me read more papers on some statistical analyses of GANs and WGANs, which was more satisfactory [for me] even though I could not get into the technical details…

finding our way in the dark

Posted in Books, pictures, Statistics with tags , , , , , , , , , on November 18, 2021 by xi'an

The paper Finding our Way in the Dark: Approximate MCMC for Approximate Bayesian Methods by Evgeny Levi and (my friend) Radu Craiu, recently got published in Bayesian Analysis. The central motivation for their work is that both ABC and synthetic likelihood are costly methods when the data is large and does not allow for smaller summaries. That is, when summaries S of smaller dimension cannot be directly simulated. The idea is to try to estimate

h(\theta)=\mathbb{P}_\theta(d(S,S^\text{obs})\le\epsilon)

since this is the substitute for the likelihood used for ABC. (A related idea is to build an approximate and conditional [on θ] distribution on the distance, idea with which Doc. Stoehr and I played a wee bit without getting anything definitely interesting!) This is a one-dimensional object, hence non-parametric estimates could be considered… For instance using k-nearest neighbour methods (which were already linked with ABC by Gérard Biau and co-authors.) A random forest could also be used (?). Or neural nets. The method still requires a full simulation of new datasets, so I wonder at the gain unless the replacement of the naïve indicator with h(θ) brings clear improvement to the approximation. Hence much fewer simulations. The ESS reduction is definitely improved, esp. since the CPU cost is higher. Could this be associated with the recourse to independent proposals?

In a sence, Bayesian synthetic likelihood does not convey the same appeal, since is a bit more of a tough cookie: approximating the mean and variance is multidimensional. (BSL is always more expensive!)

As a side remark, the authors use two chains in parallel to simplify convergence proofs, as we did a while ago with AMIS!

ABC in Svalbard [the day after]

Posted in Books, Kids, Mountains, pictures, R, Running, Statistics, Travel, University life with tags , , , , , , , , , , , , , , , , , , , , on April 19, 2021 by xi'an

The following and very kind email was sent to me the day after the workshop

thanks once again to make the conference possible. It was full of interesting studies within a friendly environment, I really enjoyed it. I think it is not easy to make a comfortable and inspiring conference in a remote version and across two continents, but this has been the result. I hope to be in presence (maybe in Svalbard!) the next edition.

and I fully agree to the talks behind full of interest and diverse. And to the scheduling of the talks across antipodal locations a wee bit of a challenge, mostly because of the daylight saving time  switches! And to seeing people together being a comfort (esp. since some were enjoying wine and cheese!).

I nonetheless found the experience somewhat daunting, only alleviated by sharing a room with a few others in Dauphine and having the opportunity to react immediately (and off-the-record) to the on-going talk. As a result I find myself getting rather scared by the prospect of the incoming ISBA 2021 World meeting. With parallel sessions and an extensive schedule from 5:30am till 9:30pm (in EDT time, i.e. GMT-4) that nicely accommodates the time zones of all speakers. I am thus thinking of (safely) organising a local cluster to attend the conference together and recover some of the social interactions that are such an essential component of [real] conferences, including students’ participation. It will of course depend on whether conference centres like CIRM reopen before the end of June. And if enough people see some appeal in this endeavour. In the meanwhile, remember to register for ISBA 2021 and for free!, before 01 May.