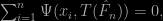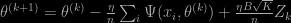Archive for score function

OWABI⁷, 26 February 2026: Prequential posteriors (11am UK time)

Posted in Books, Statistics, University life with tags , , , , , , , , , , , , , , on February 25, 2026 by xi'an

Speaker:  Shreya Sinha Roy (University of Warwick)

Title: Prequential posteriors
Abstract: Data assimilation is a fundamental task in updating forecasting models upon observing new data, with applications ranging from weather prediction to online reinforcement learning. Deep generative forecasting models (DGFMs) have shown excellent performance in these areas, but assimilating data into such models is challenging due to their intractable likelihood functions. This limitation restricts the use of standard Bayesian data assimilation methodologies for DGFMs. To overcome this, we introduce prequential posteriors, based upon a predictive-sequential (prequential) loss function; an approach naturally suited for temporally dependent data which is the focus of forecasting tasks. Since the true data-generating process often lies outside the assumed model class, we adopt an alternative notion of consistency and prove that, under mild conditions, both the prequential loss minimizer and the prequential posterior concentrate around parameters with optimal predictive performance. For scalable inference, we employ easily parallelizable wastefree sequential Monte Carlo (SMC) samplers with preconditioned gradient-based kernels, enabling efficient exploration of high-dimensional parameter spaces such as those in DGFMs. We validate our method on both a synthetic multi-dimensional time series and a real-world meteorological dataset; highlighting its practical utility for data assimilation for complex dynamical systems.
Keywords: diffusion models, simulation based inference, sequential methods.
Reference: S. S. Roy, R. Everitt, C. P Robert, R. Dutta. Prequential posteriors. Preprint at ArXiv:2511.17721, 202

OWABI⁷, 29 January 2026: Sequential Neural Score Estimation (11am UK time)

Posted in Books, Statistics, University life with tags , , , , , , , , , , on January 21, 2026 by xi'an

Speaker: Louis Sharrock (University College London)

Title: Sequential Neural Score Estimation: Likelihood-free inference with conditional score base diffusion models
Abstract: We introduce Sequential Neural Posterior Score Estimation (SNPSE), a score-based method for Bayesian inference in simulator-based models. Our method, inspired by the remarkable success of score-based methods in generative modelling, leverages conditional score-based diffusion models to generate samples from the posterior distribution of interest. The model is trained using an objective function which directly estimates the score of the posterior. We embed the model into a sequential training procedure, which guides simulations using the current approximation of the posterior at the observation of interest, thereby reducing the simulation cost. We also introduce several alternative sequential approaches, and discuss their relative merits. We then validate our method, as well as its amortised, non-sequential, variant on several numerical examples, demonstrating comparable or superior performance to existing state-of-the-art methods such as Sequential Neural Posterior Estimation (SNPE).
Keywords: diffusion models, simulation based inference, sequential methods.
Reference: L. Sharrock, J. Simons, S. Liu, M. Beaumont, Sequential Neural Score Estimation: Likelihood-Free Inference with Conditional Score Based Diffusion Models. PLMR, 235, 44565-44602, 2024.

All about that [Bayes] seminar [24 Jan]

Posted in Books, pictures, Statistics, Travel, University life with tags , , , , , , , , , , , , , , , , , , on January 13, 2025 by xi'an

The next All about that (Bayes) seminar will take place on Friday 24 Jan at SCAI, on the Jussieu campus, with the following talks. (Appearances to the contrary, I was not in the least involved in the program!)

13h30 – 14h30 Joshua Bon (OCEAN, Université Paris Dauphine) – Bayesian score calibration for approximate models

 Scientists continue to develop increasingly complex mechanistic models to reflect their knowledge more realistically. Statistical inference using these models can be challenging since the corresponding likelihood function is often intractable and model simulation may be computationally burdensome. Fortunately, in many of these situations, it is possible to adopt a surrogate model or approximate likelihood function. It may be convenient to conduct Bayesian inference directly with the surrogate, but this can result in bias and poor uncertainty quantification. In this paper (https://arxiv.org/abs/2211.05357) we propose a new method for adjusting approximate posterior samples to reduce bias and produce more accurate uncertainty quantification. We do this by optimizing a transform of the approximate posterior that maximizes a scoring rule. Our approach requires only a (fixed) small number of complex model simulations and is numerically stable. We demonstrate beneficial corrections to several approximate posteriors using our method on several examples of increasing complexity.

14h30 – 15h30 Giacomo Zanella (Bocconi University) – Entropy contraction of the Gibbs sampler under log-concavity

In this talk I will present recent work (https://arxiv.org/abs/2410.00858) on the non-asymptotic analysis of the Gibbs sampler, a classical and popular MCMC algorithm for sampling. In particular, under the assumption that the probability measure π of interest is strongly log-concave, we show that the random scan Gibbs sampler contracts in relative entropy, and provide a sharp characterization of the associated contraction rate. The result implies that, under appropriate conditions, the number of full evaluations of π required for the Gibbs sampler to converge is independent of the dimension. If time permits, I will also discuss connections and applications of the above results to the problem of zero-order parallel sampling, as well as extensions to Hit-and-Run and Metropolis-within-Gibbs.

Based on joint work with Filippo Ascolani and Hugo Lavenant.

16h00 – 17h00 Paul Bastide (Université Paris Cité) – Goodness of Fit for Bayesian Generative Models with Applications in Population Genetics

In population genetics, inference about intractable likelihood models is common, and simulation methods, including Approximate Bayesian Computation (ABC) and Simulation-Based Inference (SBI), are essential. ABC/SBI methods work by simulating instrumental data sets of the models under study and comparing them with the observed data set y⁰. Advanced machine learning tools are used for tasks such as model selection and parameter inference. The present work focuses on model criticism. This type of analysis, called goodness of fit (GoF), is important for model validation. It can also be used for model pruning when the number of candidates to be considered is excessive, especially in the context where data simulation is expensive. We introduce two new GoF tests based on the local outlier factor (LOF), an indicator that was initially defined for outlier and novelty detection. We test whether y⁰ is distributed from the prior predictive distribution (pre-inference GoF) and whether there is a parameter value such that y⁰ is distributed from the likelihood with that value (post-inference GoF).  We evaluate the performance of our two GoF tests on simulated datasets from three different model settings of varying complexity, and on a dataset of single nucleotide polymorphism (SNP) markers for the evaluation of complex evolutionary scenarios of modern human populations.

Joint work with Guillaume Le Mailloux, Jean-Michel Marin and Arnaud Estoup.

veniSBA²

Posted in Books, pictures, Running, Statistics, Travel, University life with tags , , , , , , , , , , , , , , , , , , , , , , , , on July 4, 2024 by xi'an

After another morning cycle of 2Xing Porte della Libertà (under a light and pleasant rain) and swimming in Sant’ Alviso (in too warm a water), I did not make it for the beginning of the Bayesian deep learning session, breakfast oblige!, and cumulated with different percolation events (ie, meeting friend after friend on my way to the classroom), I could not get enough of the session to report anything even barely useful!

As I did not rush fast enough to Andrew’s Foundation lecture (another sequence of percolations!), I had to stand in the back of the packed main amphitheatre (and former sorting hall of the Venice slaughterhouse!), Guido Cazzavillan’s Aula Magna, while he talked a fresco about some holes in Bayesian data analysis (the analysis, not the book!), those being [verbatim]

  1. the usual rules of conditional probability fail in the quantum realm,
  2. flat or weak priors lead to terrible inferences about things we care about,
  3. subjective priors are incoherent,
  4. Bayesian decision picks the wrong model,
  5. Bayes factors fail in the presence of flat or weak priors,
  6. for Cantorian reasons we need to check our models, but this destroys the coherence of Bayesian inference.

After lunch, I attended the (mostly sequential) simulation based inference (renamed from ABC!) session with a composite likelihood proposal by Lorenzo Rimella, that uses marginals to approximate the likelihood of a hidden Markov SIS epidemic model by composite likelihood towards getting more efficient if inexact versions. Then [1WABC webinar co-organiser] Umberto Picchini on surrogates for likelihood and posterior functions, with sequential improvements (w/o ABC and w/o neural networks). Called “Sequential mixture posterior and likelihood estimation”, using mixtures of experts when the weights are functions of the observed or simulated y. With adapting the number of components in the mixture. Comparing favourably with normalising flows. And Wentao Li on correcting by ABC for composite likelihood as in Ruli et al. (2016). Where a posterior distribution given composite scores (seen as [summary] statistics) is employed but requires a convergent estimator of the unknown parameter.

 No congratulation today to our PhD student who managed to fall in a canal (but survived)..!

robust privacy

Posted in Books, Statistics, University life with tags , , , , , , , , , , , , on May 14, 2024 by xi'an

During a recent working session, some Oceanerc (incl. me) went reading Privacy-Preserving Parametric Inference: A Case for Robust Statistics by Marco Avella-Medina (JASA, 2022), where robust criteria are advanced as efficient statistical tools in private settings. In this paper, robustness means using M-estimators T—as function of the empirical cdf—with basis score functions Ψ, defined as

\sum_{i=1}^n\Psi(x_i,T(\hat F_n))=0,

where Ψ is bounded. A construction further requiring that one can assess the sensitivity (in Dwork et al, 2006, sense) of a queried function, sensitivity itself linked with a measure of differential privacy. Because standard robustness approaches à la Huber allow for a portion of the sample to issue from an outlying (arbitrary) distribution, as in ε-contaminations, it makes perfect sense that robustness emerges within the differential framework. However, this common sense perception does not seem good enough for achieving differential privacy and the paper introduces a further randomization with noise scaled by (n,ε,δ) in the following way

T(\hat F_n)+\gamma(T,\hat F_n)5\sqrt{2\log(n)\log(2/\delta)/\epsilon_n}Z

that also applies to test statistics. This scaling seems to constitute the central result of the paper, which establishes asymptotically validity in the sense of statistical consistency (with the sample size n). But I am left wondering whether this outcome counts as supporting differential privacy as a sensible notion…

“…our proofs for the convergence of noisy gradient descent and noisy Newton’s method rely on showing that with high probability, the noise introduced to the gradients and Hessians has a negligible effect on the convergence of the iterates (up to the order of the statistical error of the non-noisy versions of the algorithms).” Avella-Medina, Bradshaw, & Loh

As a sequel I then read a more recent publication of Avella-Medina, Differentially private inference via noisy optimization, written with Casey Bradshaw & Po-Ling Loh, which appeared in the Annals of Statistics (2023). Again considering privatised estimation and inference for M-estimators, obtained by using noisy optimization procedures (noisy gradient descent, noisy Newton’s method) and constructing noisy confidence regions, that output differentially private avatars of standard M-estimators. Here the noisification goes through a randomisation of the gradient step like

\theta^{(k+1)}=\theta^{(k)}-\frac{\eta}{n}\sum_i\Psi(x_i,\theta^{(k)})+\frac{\eta B\sqrt K}{n}Z_k

where B is an upper bound on the gradient Ψ, η is a discretization step, and K is the total number of iterations (thus fixed in advance). The above stochastic gradient sequence converges with high probability to the actual M-estimator in n and not in K, since the upper bound on the distance scales in √K/n. Where does the attached privacy guarantee come from? It proceeds by an argument of a composition of a sequence of differentially private outputs, all based on the same dataset.

“…the larger the number [K] of data (gradient) queries of the algorithm, the more prone it will be to privacy leakage.”

The Newton method version is a variation on the above stochastic gradient descent. Except it seems to converge faster, as illustrated above.