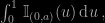Archive for Lebesgue integration

a second course in probability² [book review]

Posted in Books, Kids, Statistics, University life with tags , , , , , , , , , , , , , , , on December 17, 2023 by xi'an

I was sent [by CUP] Ross & Peköz Second Course in Probablity for review. Although it was published in 2003, a second edition has come out this year. I had not looked at the earlier edition hence will not comment on the differences, but rather reflect on my linear reading of the book and my reactions as a potential teacher (even though I have not taught measure theory for decades, being a low priority candidate in an applied math department). As a general perspective, I think it would be deemed as too informal for our 3rd year students in Paris Dauphine.

This indeed is a soft introduction to measure based probability theory. With plenty of relatively basic examples as the requirement on the calculus background of the readers is quite limited. Surprising appearance of an integral in the expectation section before it is ever defined (meaning it is a Riemann integral as confirmed on the next page), but all integrals in the book will be Riemann integrals, with hardly a mention of a more general concept or even of Lebesgue integration (p 16). Which leads to the probability density being defined in terms of the Lebesgue measure (not yet mentioned). Expectation as suprema of step functions which is enough to derive the dominated convergence theorem. And a (insufficiently detailed?) proof that inverting the cdf at a uniform produces a generation from that distribution. Representation that proves most useful for the results of convergence in distribution. Although the choice (p 31) that all rv’s in a sequence are deterministic transforms of the same Uniform may prove challenging for the students (despite mentioning Skohorod’s representation theorem). Concluding the first chapter with an ergodic theorem for stationary and… ergodic sequences, possibly making the result sound circular. Annoyingly (?) a lot of examples involve discrete rvs, the more as we proceed through the chapters. (Hence the unimaginative dice cover.)

Chap 2, the definition of stochastically smaller is missing italics on the term. This chapter relies on the powerful notion of coupling, leading to Le Cam’s theorem and the Stein-Chen method. Declined for Poisson, Geometric, Normal, and Exponential variates, incl. a Central Limit Theorem. Surprising appearance of a conditional distribution and even more of a conditional variate (Theorem 2.11)  that I would criticize as sloppy were it to occur within an X validated question!

Chap 3 on martingales with another informal start on conditional expectations using some intuition from the easiest cases, but also a yet undefined notion of conditional distribution. The main application of the notion is the martingale stopping theorem, with mostly discrete illustrations. (The first sentence of the chapter is puzzling, presenting as a generalisation of iid-ness a sequence of rv’s as having each term depending on the previous ones when the joint distribution can always be decomposed this way by a towering argument.)

Chap 4 on probability bounds with a first technique using the importance sampling identity, which includes the Chernoff bound as a special case. While there are principles at work, I am always uncomfortable teaching about these inequalities, as it often relies on a clever trick.

Chap 5 on Markov chains (with Markov deserving of an historical note contrary to Stein or Le Cam, Borel or Cantelli which would have helped my student seeking their names!) but this is solely done on discrete state spaces, without a mention that irreducible transient Markov chains cannot occur on a finite state space. The chapter covers essentials in that context, including Gambler’s ruin, but I’d rather refer to Feller’s (1970) more general coverage and wonder why the authors stuck to the discrete case.

Chap 6 on renewal theory, albeit defined only for crossing renewal times. In the spirit of Meyn & Tweedie (1994), I find renewal times quite useful in establishing Central Limit theorems in non-iid sequences, but here it is only applied to the renewal process itself (with a typo in Proposition 6.7). The chapter however includes an example of forward exact sampling for a Markov chain satisfying a minorisation condition, as well as brief sections on queuing and Poisson processes.

Chap 7 on Brownian motion, no less! With a discrete iterative construction one hopes will conduct to a proper limit as its existence is not formally proven. And which I deem did not require five figures to explain how to randomly move the midpoint of a segment. This short and final chapter proceeds à marche forcée towards a Central Limit theorem for general stationary and ergodic random variables. A bit too much for a 180p book.

[Disclaimer about potential self-plagiarism: this post or an edited version will eventually appear in my Books Review section in CHANCE.]

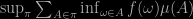
what makes variables randoms [book review]

Posted in Books, Mountains, Statistics with tags , , , , , , on July 19, 2017 by xi'an

When the goal of a book is to make measure theoretic probability available to applied researchers for conducting their research, I cannot but applaud! Peter Veazie’s goal of writing “a brief text that provides a basic conceptual introduction to measure theory” (p.4) is hence most commendable. Before reading What makes variables random, I was uncertain how this could be achieved with a limited calculus background, given the difficulties met by our third year maths students. After reading the book, I am even less certain this is feasible!

“…it is the data generating process that makes the variables random and not the data.”

Chapter 2 is about basic notions of set theory. Chapter 3 defines measurable sets and measurable functions and integrals against a given measure μ as

\sup_\pi \sum_{A\in\pi}\inf_{\omega\in A} f(\omega)\mu(A)

which I find particularly unnatural compared with the definition through simple functions (esp. because it does not tell how to handle 0x∞). The ensuing discussion shows the limitation of the exercise in that the definition is only explained for finite sets (since the notion of a partition achieving the supremum on page 29 is otherwise meaningless). A generic problem with the book, in that most examples in the probability section relate to discrete settings (see the discussion of the power set p.66). I also did not see a justification as to why measurable functions enjoy well-defined integrals in the above sense. All in all, to see less than ten pages allocated to measure theory per se is rather staggering! For instance,

\int_A f\text{d}\mu

does not appear to be defined at all.

“…the mathematical probability theory underlying our analyses is just mathematics…”

Chapter 4 moves to probability measures. It distinguishes between objective (or frequentist) and subjective measures, which is of course open to diverse interpretations. And the definition of a conditional measure is the traditional one, conditional on a set rather than on a σ-algebra. Surprisingly as this is in my opinion one major reason for using measures in probability theory. And avoids unpleasant issues such as Bertrand’s paradox. While random variables are defined in the standard sense of real valued measurable functions, I did not see a definition of a continuous random variables or of the Lebesgue measure. And there are only a few lines (p.48) about the notion of expectation, which is so central to measure-theoretic probability as to provide a way of entry into measure theory! Progressing further, the σ-algebra induced by a random variable is defined as a partition (p.52), a particularly obscure notion for continuous rv’s. When the conditional density of one random variable given the realisation of another is finally introduced (p.63), as an expectation reconciling with the set-wise definition of conditional probabilities, it is in a fairly convoluted way that I fear will scare newcomers out of their wit. Since it relies on a sequence of nested sets with positive measure, implying an underlying topology and the like, which somewhat shows the impossibility of the overall task…

“In the Bayesian analysis, the likelihood provides meaning to the posterior.”

Statistics is hurriedly introduced in a short section at the end of Chapter 4, assuming the notion of likelihood is already known by the readers. But nitpicking (p.65) at the representation of the terms in the log-likelihood as depending on an unspecified parameter value θ [not to be confused with the data-generating value of θ, which does not appear clearly in this section]. Section that manages to include arcane remarks distinguishing maximum likelihood estimation from Bayesian analysis, all this within a page! (Nowhere is the Bayesian perspective clearly defined.)

“We should no more perform an analysis clustered by state than we would cluster by age, income, or other random variable.”

The last part of the book is about probabilistic models, drawing a distinction between data generating process models and data models (p.89), by which the author means the hypothesised probabilistic model versus the empirical or bootstrap distribution. An interesting way to relate to the main thread, except that the convergence of the data distribution to the data generating process model cannot be established at this level. And hence that the very nature of bootstrap may be lost on the reader. A second and final chapter covers some common or vexing problems and the author’s approach to them. Revolving around standard errors, fixed and random effects. The distinction between standard deviation (“a mathematical property of a probability distribution”) and standard error (“representation of variation due to a data generating process”) that is followed for several pages seems to boil down to a possible (and likely) model mis-specification. The chapter also contains an extensive discussion of notations, like indexes (or indicators), which seems a strange focus esp. at this location in the book. Over 15 pages! (Furthermore, I find quite confusing that a set of indices is denoted there by the double barred I, usually employed for the indicator function.)

“…the reader will probably observe the conspicuous absence of a time-honoured topic in calculus courses, the “Riemann integral”… Only the stubborn conservatism of academic tradition could freeze it into a regular part of the curriculum, long after it had outlived its historical importance.” Jean Dieudonné, Foundations of Modern Analysis

In conclusion, I do not see the point of this book, from its insistence on measure theory that never concretises for lack of mathematical material to an absence of convincing examples as to why this is useful for the applied researcher, to the intended audience which is expected to already quite a lot about probability and statistics, to a final meandering around linear models that seems at odds with the remainder of What makes variables random, without providing an answer to this question. Or to the more relevant one of why Lebesgue integration is preferable to Riemann integration. (Not that there does not exist convincing replies to this question!)

an email exchange about integral representations

Posted in Books, R, Statistics, University life with tags , , , , on April 8, 2015 by xi'an

integralsI had an interesting email exchange [or rather exchange of emails] with a (German) reader of Introducing Monte Carlo Methods with R in the past days, as he had difficulties with the validation of the accept-reject algorithm via the integral

\mathbb{P}(Y\in \mathcal{A},U\le f(Y)/Mg(Y)) = \int_\mathcal{A} \int_0^{f(y)/Mg(y)}\,\text{d}u\,g(y)\,\text{d}y\,,

in that it took me several iterations [as shown in the above] to realise the issue was with the notation

\int_0^a \,\text{d}u\,,

which seemed to be missing a density term or, in other words, be different from

\int_0^1 \,\mathbb{I}_{(0,a)}(u)\,\text{d}u\,,

What is surprising for me is that the integral

\int_0^a \,\text{d}u

has a clear meaning as a Riemann integral, hence should be more intuitive….

a remarkably simple and accurate method for computing the Bayes factor &tc.

Posted in Statistics with tags , , , , , , , , on February 13, 2013 by xi'an

This recent arXiv posting by Martin Weinberg and co-authors was pointed out to me by friends because of its title! It indeed sounded a bit inflated. And also reminded me of old style papers where the title was somehow the abstract. Like An Essay towards Solving a Problem in the Doctrine of Chances… So I had a look at it on my way to Gainesville. The paper starts from the earlier paper by Weinberg (2012) in Bayesian Analysis where he uses an HPD region to determine the Bayes factor by a safe harmonic mean estimator (an idea we already advocated earlier with Jean-Michel Marin in the San Antonio volume and with Darren Wraith in the MaxEnt volume). An extra idea is to try to optimise [against the variance of the resulting evidence] the region over which the integration is performed: “choose a domain that results in the most accurate integral with the smallest number of samples” (p.3). The authors proceed by volume peeling, using some quadrature formula for the posterior coverage of the region, either by Riemann or Lebesgue approximations (p.5). I was fairly lost at this stage and the third proposal based on adaptively managing hyperrectangles (p.7) went completely over my head! The sentence “the results are clearly worse with O(∞) errors, but are still remarkably better for high dimensionality”(p.11) did not make sense either… The method may thus be remarkably simple, but the paper is not written in a way that conveys this impression!

Frequency vs. probability

Posted in Statistics with tags , , , , , , , on May 6, 2011 by xi'an

“Probabilities obtained by maximum entropy cannot be relevant to physical predictions because they have nothing to do with frequencies.” E.T. Jaynes, PT, p.366

“A frequency is a factual property of the real world that we measure or estimate. The phrase `estimating a probability’ is just as much an incongruity as `assigning a frequency’. The fundamental, inescapable distinction between probability and frequency lies in this relativity principle: probabilities change when we change our state of knowledge, frequencies do not.” E.T. Jaynes, PT, p.292

A few days ago, I got the following email exchange with Jelle Wybe de Jong from The Netherlands:

Q. I have a question regarding your slides of your presentation of Jaynes’ Probability Theory. You used the [above second] quote: Do you agree with this statement? It seems to me that a lot of  ‘Bayesians’ still refer to ‘estimating’ probabilities. Does it make sense for example for a bank to estimate a probability of default for their loan portfolio? Or does it only make sense to estimate a default frequency and summarize the uncertainty (state of knowledge) through the posterior? Continue reading →