Archive for Monte Carlo

more than mostly MC

Posted in Kids, pictures, Statistics, Travel, University life with tags , , , , , , , , , , , , , , , , , , , , , , on December 27, 2024 by xi'an

The session of last Friday (and last one of 2024!) proved most interesting, with two (fully) Monte Carlo talks. The first one by Louis Grenioux was about an improvement on diffusion sampler, following a recent arXival by Maxime Noble and co-authors. Which brought me back to the long-standing multimodal challenge in Monte Carlo methods. When all modes of a target distribution are known, even roughly, this is not much of an issue since samplers can be arm-bent into visiting all these modes. But the problem becomes much harder when the location and a fortiori the number of modes are not known. The paper aims at adapting diffusion samplers towards a better exploration of the modes, albeit their location is known. Otherwise, using MCMC as a starting (reference) distribution would risk missing some of them. Which also explains why the authors can rely on the classical Gaussian mixtures proposal as a cheap substitute to neural networks (EBM). Since, within diffusion models, both intermediary distributions and their scores are intractable, they also introduce a variational parametric approximation that can be optimised.

The second talk was given by Guillaume Chennetier, in connection with his recent PhD thesis, developing a form of X-entropy sampling for rare events. As in nuclear plant major accidents. It took me a while to realise that PDMPs were not used as a simulation tool, as in the zigzag sampler and its avatars, The proposal involved creating a graph structure on the space of PDMP trajectories and designing the optimal importance process (yes, the one with zero variance!) using so-called committor functions that modify jump intensity and kernel, in a sequential way reminiscent of X-entropy. The approach recycles past trajectories as Monte Carlo elements if missing an adaptive mixture importance sampling (AMIS!) version that would bring more stability. The talk also included an interesting pointer to the availability of the distribution of the PDMP path, thus treated as a likelihood. (!). The signage at the entrance of the Monte-Carlo (mind the hyphen!) casino also made an appearance, reminding me of our memorable group picture on the same spot, eons ago! (But not of whom took the picture!)

ಬೆಂಗಳೂರು ಸ್ನ್ಯಾಪ್‌ಶಾಟ್¹⁰ [jatp]

Posted in pictures, Travel with tags , , , , , , , , on January 15, 2023 by xi'an

tch

simulating from the joint cdf

Posted in Books, Kids, pictures, R, Statistics, University life with tags , , , , , , , , on July 13, 2022 by xi'an

An X validated question (what else?!) brought back (to me) the question of handling a bivariate cdf for simulation purposes. In the specific case of a copula when thus marginals were (well-)known…. And led me to an erroneous chain of thought, fortunately rescued by Robin Ryder! When the marginal distributions are set, the simulation setup is indeed equivalent to a joint Uniform simulation from a copula

\mathbb P[U_1\leq u_1,U_2\leq u_2,\dots,U_d\leq u_d]=C(u_1,u_2,\dots,u_d)

In specific cases, as for instance the obvious example of Gaussian copulas, there exist customised simulation algorithms. Looking for more generic solutions, I turn to the Bible, where Chapter XI[an], has two entire sections XI.3.2. and XI.3.3 on the topic (even though Luc Devroye does not use the term copula there despite them being introduced in 1959 by A, Sklar, in response to a query of M. Fréchet). In addition to a study of copulas, both sections contain many specific solutions (as for instance in the [unnumbered] Table on page 585) but I found no generic simulation method. My [non-selected] answer to the question was thus to propose standard solutions such as finding one conditional since the marginals are Uniform. Which depends on the tractability of the derivatives of C(·,·).

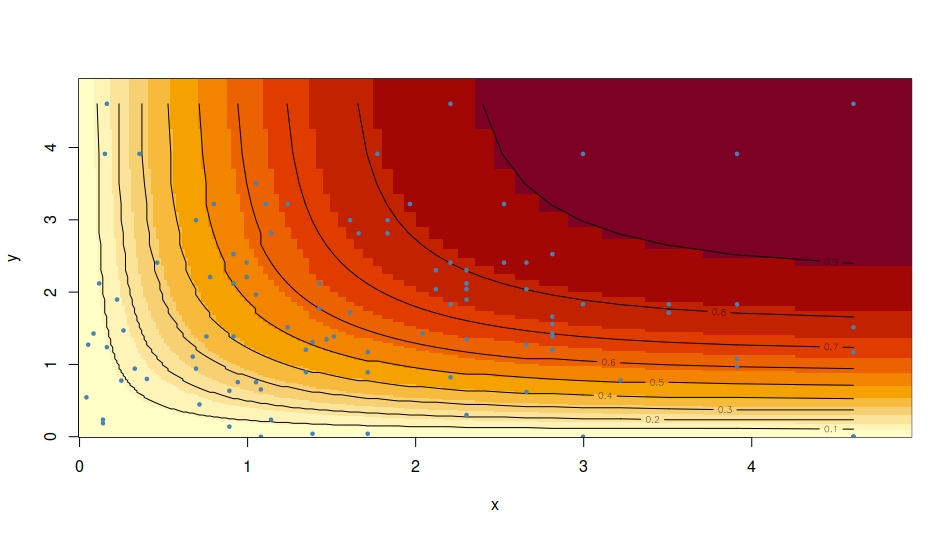
However, being dissatisfied with this bland answer, I thought further about the problem and came up with a fallacious scheme, namely to first simulate the value p of C(U,V) by drawing a Uniform, and second simulate (U,V) conditional on C(U,V)=p. Going as far as running an R code on a simple copula, as shown above. Fallacious reasoning since (as I knew already!!!), C(U,V) is not uniformly distributed! But has instead a case-dependent distribution… As a (connected) aside, I wonder if the generator attached with Archimedean copulas has any magical feature that help with the generation of the associated copula.

1 / duh?!

Posted in Books, R, Statistics, University life with tags , , , , , , , on September 28, 2021 by xi'an

An interesting case on X validated of someone puzzled by the simulation (and variance) of the random variable 1/X when being able to simulate X. And being surprised at the variance of the ratio being way larger than the variances of both numerator and denominator.

Monte Carlo in the convent

Posted in pictures, Statistics, Travel, University life with tags , , , , , , , , , on July 14, 2016 by xi'an

Last week, at the same time as the workshop on retrospective Monte Carlo in Warwick, there was a Monte Carlo conference in Paris, closing a Monte Carlo cycle run by Institut Louis Bachelier from October 2015 till June 2016. It took place in the convent of Les Cordeliers, downtown Paris [hence the title] and I alas could not attend the talks. As I organised a session on Bayesian (approximate) computations, with Richard Everitt, Jere Koskela, and Chris Sherlock as speakers (and Robin Ryder as chair), here are the slides of the speakers (actually, Jere most kindly agreed to give Chris’ talk as Chris was to sick to travel to Paris):