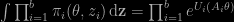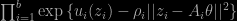Archive for Langevin MCMC algorithm

BayesComp 2025.3

Posted in pictures, Running, Statistics, Travel, University life with tags , , , , , , , , , , , , , , , , , , , , , , , , , , , , , , , , , , , , , , , , , , , , , , on June 20, 2025 by xi'an

The second day of the conference started with a cooler and less humid weather (although this did not last!), although my brain felt a wee bit foggy from a lack of sleep (and I almost crashed while running on the hotel treadmill, at 14.5km/h!), and the plenary talk of my friend of many years Sylvia Früwirth-Schnatter on horseshoe priors and time-varying time series (à la West). With a nice closed-form representation involving hypergeometric functions of the second kind (my favourite!), with the addition of a triple-Gamma prior. Sylvia stressed on the enormous impact of the prior choice on change-point detection, which was already the point in the original horseshoe paper (as opposed to George’s Lasso prior). Without incorporating any specific modelling on potential change-point, fair enough given that the parameter is moving with time, unhindered. Her MCMC choices involved discrete parameters with Negative Binomial and Poisson parameters, allowing for partially integrated or collapsed solutions. Possibly further improved by Swendsen-Wang steps.

I then attended the (advanced) Langevin session after agonising upon my choice for a wealth of options! Sam Power presented a talk linking simulation with optimisation targets, over measure spaces. With Wasserstein gradient flow algorithms that resemble Langevin algorithms once discretised by a particle system. (A natural resolution producing a somewhat unnatural form of measure estimator since made of Dirac masses, from which very little can be learned.) Then [my Warwick colleague & coauthor] Any Wang on underdamped Langevin diffusions. when Poincaré‘s inequality fails, but convergence (in total variation) still occurs. Followed by Peter Whalley on splitting methods (where random hypergeometric subsampling dominates Robbins-Monro) and stochastic gradient algorithms, in a connected (to the previous talks) way since involving underdamped aspects. (With a personal discovery of Polyak’s heavy ball method.)

The afternoon session saw me facing a terrible dilemma with three close friends talking at the same time! Eventually opting for PDMPs, over simulation-based inference and recalibration for approximate Bayesian methods. Kengo Kamatani gave a general introduction to PDMPs, before explaining the automated implementation he considered with Charly Andral (during Charly’s visit to ISM, Tokyo, two summers ago). Towards accelerating the generation of the jump time. Then Luke Hardcastle applied PDMPs for survival prediction, using spike & slab priors and sticky PDMPs. And Jere Koskela (formerly Warwick) extended zig-zag sampling to discrete settings (incl. Kingman’s coalescent.)

The (rather long) day was not over yet since we had planned an extra on-site OWABI seminar & webinar with two participants in the conference, Filippo Pagani (Warwick and OCEAN postdoc) using fusion for federated learning, with a trapezoidal approximation, and Maurizio Filippone on GANs as hidden perfect ABC model selection, a GAN providing an automatic density estimator… With astounding Gemini-generated cartoons! Videos are soon to be available. A big congrats to the speakers who managed to convey their ideas and results despite the late hour! (On the extra-academic side, I was invited last night to a genuine Szechuan dinner in Chinatown, with a large array of spicy dishes if not that spicy!, and a rare opportunity to taste abalone. And bullfrogs. Quite a treat! And a good reason to skip dinner altogether!)

mostly MCMC’s back

Posted in Statistics, University life with tags , , , , , , , , , , , , on September 13, 2024 by xi'an

Arnak Dalalyan at the RSS Journal Webinar

Posted in Books, pictures, Statistics, Travel, University life with tags , , , , , , , , , , , , , , on October 15, 2023 by xi'an

My friend and CREST colleague Arnak Dalalyan will (re)present [online] a Read Paper at the RSS on 31 October with my friends Hani Doss and Alain Durmus as discussants:

‘Theoretical Guarantees for Approximate Sampling and Log-Concave Densities’

Arnak Dalalyan ENSAE Paris, France

Sampling from various kinds of distributions is an issue of paramount importance in statistics since it is often the key ingredient for constructing estimators, test procedures or confidence intervals. In many situations, exact sampling from a given distribution is impossible or computationally expensive and, therefore, one needs to resort to approximate sampling strategies. However, there is no well-developed theory providing meaningful non-asymptotic guarantees for the approximate sampling procedures, especially in high dimensional problems. The paper makes some progress in this direction by considering the problem of sampling from a distribution having a smooth and log-concave density defined on ℝᵖ⁠, for some integer p > 0. We establish non-asymptotic bounds for the error of approximating the target distribution by the distribution obtained by the Langevin Monte Carlo method and its variants. We illustrate the effectiveness of the established guarantees with various experiments. Underlying our analysis are insights from the theory of continuous time diffusion processes, which may be of interest beyond the framework of log-concave densities that are considered in the present work.

turn-key and scalable synchronous distributed MCMC algorithm

Posted in Statistics, University life with tags , , , , , on April 29, 2022 by xi'an

Last week, I attended a Lagrange seminar where Vincent Plassier presented a ICML²¹ paper he had co-authored with Maxime Vono, Alain Durmus, and Eric Moulines. Aiming at distributed MCMC algorithms that operate on several machines, with a target distribution that breaks as a target

\int\prod_{i=1}^b \pi_i(\theta,z_i)\,\text d\mathbf{z}=\prod_{i=1}^b e^{U_i(A_i\theta)}

where θ is common to all terms. And each term in the product can (only) be computed locally. This setup is obviously the same as for the embarrassingly parallel approaches of Neiswanger et al. (2014) and Scott et al. (2016). And it follows an earlier proposal of Vono et al. (2020), which appears as a full Gibbs algorithm on the augmented parameters (θ,z), assuming each term is a conditional density in the latent z’s. Which requires constant communications between the b workers and the central “master” node when θ is concerned. The ICML²¹ paper overcomes this difficulty by defining an approximate target with a Normal component in z. Meaning that the (approximate) conditional distribution of θ given the latent z is Normal, i.e. considering the augmented joint

\prod_{i=1}^b\exp\left\{u_i(z_i)-\rho_i||z_i-A_i\theta||^2\right\}

but despite the Gaussian aspect, this is not always practical:

“When d [is large], this Gibbs sampling scheme unfortunately leads to prohibitive computational costs and hence prevents its practical use for general Bayesian inference problems.”

The authors then move to simulating from several Langevin step, more specifically running one move of the Euler-Maruyama discretisation scheme of the overdamped Langevin stochastic differential equation. Communication with the central node is then reduced. The paper proposes a proof of convergence in this unusual (since overdamped) setup. As well as bounds on the bias due to the inclusion of the latent variables. They also manage to find the required scaling of the various parameters involved (Normal variance, discretisation scale, Langevin runs) to achieve convergence, which I find rather remarkable. The table at the top illustrates the comparison with earlier methods, whenever available.

control variates [seminar]

Posted in pictures, Statistics, Travel, University life with tags , , , , , , , , , , , , , , on November 5, 2021 by xi'an

Today, Petros Dellaportas (whom I have know since the early days of MCMC, when we met in CIRM) gave a seminar at the Warwick algorithm seminar on control variates for MCMC, reminding me of his 2012 JRSS paper. Based on the Poisson equation and using a second control variate to stabilise the Monte Carlo approximation do the first control variate. The difference with usual control variates is finding a first approximate G(x)-q(y|x)G(Y) to F-πF. And the first Poisson equation is using α(x,y)q(y|x) rather than π. Then the second expands log α(x,y)q(y|x) to achieve a manageable term.

Abstract: We provide a general methodology to construct control variates for any discrete time random walk Metropolis and Metropolis-adjusted Langevin algorithm Markov chains that can achieve, in a post-processing manner and with a negligible additional computational cost, impressive variance reduction when compared to the standard MCMC ergodic averages. Our proposed estimators are based on an approximate solution of the Poisson equation for a multivariate Gaussian target densities of any dimension.

I wonder if there were a neural network version that would first build G from scratch and later optimise it towards solving the Poisson equation. As in this recent arXival I haven’t read (yet).