Archive for G-Wishart distribution

telescope on evidence for graphical models

Posted in Books, Statistics, University life with tags , , , , , , , , , on February 29, 2024 by xi'an

A recent paper on evidence by Anindya Bhadra, Ksheera Sagar, Sayantan Banerjee (whom I met during Rito’s seminar, since he was also visiting Ismael in Paris, and who mentioned this work), and Jyotishka Datta, on computing the evidence for graphical models. Obtaining an approximation of the evidence attached with a model and a prior on the covariance matrix Ω is a challenge they manage to address in a particularly clever manner.

“the conditional posterior density [of the last column of the covariance matrix] can be evaluated as a product of normal and gamma densities under suitable priors (…) We resolve this [difficulty with the integrated likelihood] by evaluating the required densities in one row or column at a time, and proceeding backwards starting from the p-th row, with appropriate adjustments to Ωp×p at each step via Schur complement. “

Using a telescoping trick, the authors exploit the fact that the decomposition
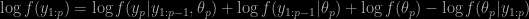
\log f(y_{1:p})=\log f(y_p|y_{1:p-1},\theta_p)+\log f (y_{1:p-1}|\theta_p)+\log f(\theta_p)-\log f(\theta_p|y_{1:p})

involves a problematic second term that can be ignored by successive cancellations, as shown by Figure 1. The other terms are manageable for some classes of priors on Ω. Like a Wishart. This allows them to call for Chib’s (two-black) method, which requires two independent MCMC runs. Actually, an unfortunate aspect of the approach is that its computational complexity is of order O(M p⁵), where M is the number of MCMC samples, due to the telescopic trick involving calling Chib’s approach for each of the p columns of Ω. While the numerical outcomes compare with nested sampling, annealed importance sampling, and even harmonic mean estimates (!), the computing time usually exceeds those for these other methods, esp. harmonic mean estimates For the specific G-Wishart case, the solution proposed by Atay-Kayis and Massam (2005) proves far superior. Since the main purpose of using evidence is in deriving Bayes factors, I wonder at possible gains in recycling simulations between models, even though this would seem to call for bridge sampling, no considered in the paper.

ISBA 2021 low key

Posted in Kids, Mountains, pictures, Running, Statistics, Travel, University life, Wines with tags , , , , , , , , , , , , , , , , , , , , , , , , on July 2, 2021 by xi'an

Fourth day of ISBA (and ISB@CIRM), which was a bit low key for me as I had a longer hike with my wife in the morning, including a swim in a sea as cold as the Annecy lake last month!, but nonetheless enjoyable and crystal clear, then attacked my pile of Biometrika submissions that had accumulated beyond the reasonable since last week, chased late participants who hadn’t paid yet, reviewed a paper that was due two weeks ago, chatted with participants before they left, discussed a research problem, and as a result ended attending only four sessions over the whole day. Including one about Models and Methods for Networks and Graphs, with interesting computation challenges, esp. in block models, the session in memoriam of Hélène Massam, where Gérard Letac (part of ISB@CIRM!), Jacek Wesolowski, and Reza Mohammadi, all coauthors of Hélène, made presentations on their joint advances. Hélène was born in Marseille, actually, in 1949, and even though she did not stay in France after her École Normale studies, it was a further commemoration to attend this session in her birth-place. I also found out about them working on the approximation of a ratio of normalising constants for the G-Wishart. The last session of my data was the Susie Bayarri memorial lecture, with Tamara Roderick as the lecturer. Reporting on an impressive bunch of tricks to reduce computing costs for hierarchical models with Gaussian processes.

normalising constants of G-Wishart densities

Posted in Books, Statistics with tags , , , , , , on June 28, 2017 by xi'an

Abdolreza Mohammadi, Hélène Massam, and Gérard Letac arXived last week a paper on a new approximation of the ratio of two normalising constants associated with two G-Wishart densities associated with different graphs G. The G-Wishart is the generalisation of the Wishart distribution by Alberto Roverato to the case when some entries of the matrix are equal to zero, which locations are associated with the graph G. While enjoying the same shape as the Wishart density, this generalisation does not enjoy a closed form normalising constant. Which leads to an intractable ratio of normalising constants when doing Bayesian model selection across different graphs.

Atay-Kayis and Massam (2005) expressed the ratio as a ratio of two expectations, and the current paper shows that this leads to an approximation of the ratio of normalising constants for a graph G against the graph G augmented by the edge e, equal to

Γ(½{δ+d}) / 2 √π Γ(½{δ+d+1})

where δ is the degree of freedom of the G-Wishart and d is the number of minimal paths of length 2 linking the two end points of e. This is remarkably concise and provides a fast approximation. (The proof is quite involved, by comparison.) Which can then be used in reversible jump MCMC. The difficulty is obviously in evaluating the impact of the approximation on the target density, as there is no manageable available alternative to calibrate the approximation. In a simulation example where such an alternative is available, the error is negligible though.