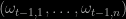Archive for scoring rule

Mostly Monte Carlo Se[a]minar

Posted in Kids, pictures, Statistics, University life with tags , , , , , , , , , , , , , , on October 6, 2023 by xi'an

A brand new monthly series of Parisian seminars on the theory and practice of Monte Carlo in statistics and data science, in conjunction with our ERC OCEAN project. To kick start the series the organisers, Joshua Bon and Andrea Bertazzi, first postdocs in the project, will present some of their work on Friday 13 October, 4PM – 6PM, Room 7, PariSanté Campus 2 Rue d’Oradour-sur-Glane, Paris 15. The following seminars are planned on Friday 17 November and Friday 15 December.

4pm/16h CEST: Piecewise deterministic sampling with splitting schemes

Andrea Bertazzi, CMAP – École Polytechnique

Piecewise deterministic Markov processes (PDMPs) received substantial interest in recent years as an alternative to classical Markov chain Monte Carlo algorithms. While theoretical properties of PDMPs have been studied extensively, their practical implementation remains limited to specific applications in which bounds on the gradient of the negative log-target can be derived. In order to address this problem, we propose to approximate PDMPs using splitting schemes, that means simulating the deterministic dynamics and the random jumps in two different stages. We show that symmetric splittings of PDMPs are of second order. Then we focus on the Zig-Zag sampler (ZZS) and show how to remove the bias of the splitting scheme with a skew reversible Metropolis filter. Finally, we illustrate with numerical simulations the advantages of our proposed scheme over competitors.

5pm/17h CEST: Bayesian score calibration for approximate models

Joshua Bon, Ceremade – Université Paris Dauphine-PSL

Scientists continue to develop increasingly complex mechanistic models to reflect their knowledge more realistically. Statistical inference using these models can be challenging since the corresponding likelihood function is often intractable and model simulation may be computationally burdensome. Fortunately, in many of these situations, it is possible to adopt a surrogate model or approximate likelihood function. It may be convenient to base Bayesian inference directly on the surrogate, but this can result in bias and poor uncertainty quantification. In this paper we propose a new method for adjusting approximate posterior samples to reduce bias and produce more accurate uncertainty quantification. We do this by optimizing a transform of the approximate posterior that maximizes a scoring rule. Our approach requires only a (fixed) small number of complex model simulations and is numerically stable. We demonstrate good performance of the new method on several examples of increasing complexity.
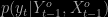
Terry Tao on Bayes… and Trump

Posted in Books, Kids, Statistics, University life with tags , , , , , , , on June 13, 2016 by xi'an

“From the perspective of Bayesian probability, the grade given to a student can then be viewed as a measurement (in logarithmic scale) of how much the posterior probability that the student’s model was correct has improved over the prior probability.” T. Tao, what’s new, June 1

Jean-Michel Marin pointed out to me the recent post of Terry Tao on setting a subjective prior for allocating partial credits to multiple answer questions. (Although I would argue that the main purpose of multiple answer questions is to expedite grading!) The post considers only true-false questionnaires and the case when the student produces a probabilistic assessment of her confidence in the answer. In the format of a probability p for each question. The goal is then to devise a grading principle, f, such that f(p) goes to the right answer and f(1-p) to the wrong answer. This sounds very much like scoring weather forecasters and hence designing proper scoring rules. Which reminds me of the first time I heard a talk about this: it was in Purdue, circa 1988, and Morrie DeGroot gave a talk on scoring forecasters, based on a joint paper he had written with Susie Bayarri. The scoring rule is proper if the expected reward leads to pick p=q when p is the answer given by the student and q her true belief. Terry Tao reaches the well-known conclusion that the grading function f should be f(p)=log²(2p) where log² denotes the base 2 logarithm. One property I was unaware of is that the total expected score writes as N+log²(L) where L is the likelihood associated with the student’s subjective model. (This is the only true Bayesian aspect of the problem.)

An interesting and more Bayesian last question from Terry Tao is about what to do when the probabilities themselves are uncertain. More Bayesian because this is where I would introduce a prior model on this uncertainty, in a hierarchical fashion, in order to estimate the true probabilities. (A non-informative prior makes its way into the comments.) Of course, all this leads to a lot of work given the first incentive of asking multiple choice questions…

One may wonder at the link with scary Donald and there is none! But the next post by Terry Tao is entitled “It ought to be common knowledge that Donald Trump is not fit for the presidency of the United States of America”. And unsurprisingly, as an opinion post, it attracted a large number of non-mathematical comments.

Assessing models when all models are false

Posted in Statistics, University life with tags , , , , , on November 11, 2010 by xi'an

When I arrived home from Philadelphia, I got the news that John Geweke was giving a seminar at CREST in the early afternoon and thus biked there to attend his talk. The topic was about comparing asset return models, but what interested most was the notion of comparing models without a reference to a true model, a difficulty I have been juggling with for quite a while (at least since the goodness-of-fit paper with Judith Rousseau we never resubmitted!). And for which I still do not find a satisfactory (Bayesian) solution.

Because there is no true model, Durham and Geweke use the daily (possibly Bayesian) predictive

p(y_t|Y^o_{t-1},X^o_{t-1})

as their basis for model assessment and rely on a log scoring rule

\sum_{s=1}^{t-1} \log p_s(y^o_s|Y^o_{s-1},X^o_{s-1})

to compare models. (The ‘o’ in the superscript denotes the observed values.) As reported in the paper this is a proper (or honest) scoring rule. If n models are under competition, a weighted (model) predictive average

\sum_{i=1}^n \,\omega_{s-1;i} p^i_s(y_s|Y^o_{s-1},X^o_{s-1})

can be considered and the paper examines the impact of picking the optimal weight vector (\omega_{t-1,1},\ldots,\omega_{t-1,n}) against the log scoring rule, i.e.

\arg\max_{\mathbf{\omega}_{t-1}} \sum_{s=1}^{t-1} \sum_{i=1}^n \,\omega_{t-1;i} \log p^i_s(y^o_s|Y^o_{s-1},X^o_{s-1})

The weight vector at time t-1 is therefore optimising the backward sequence of predictions of the observed values till time t-1. The interesting empirical result from this study is that, even from a Bayesian perspective, the weights never degenerate, unless one of the models is correct (which is rarely the case!). Thus, even after very long series of observations, the weights of different models remain away from zero (while the Bayesian posterior probability of a single model goes to one). Even though I am not yet at the point of adopting this solution (in particular because it seems to be using the data twice, once through the posterior/predictive and once through the score), I find the approach quite intriguing and hope I can study it further. Maybe a comparison with a Bayesian non-parametric evaluation would make sense…