 x
Archive for Bayesian model comparison
ECMLE on CRAN
Posted in R, Statistics, University life with tags Bayesian model comparison, CRAN, ECMLE package, elliptical covering, github, HPD region, marginal likelihood, normalising constant, R, R package, statistical evidence on March 27, 2026 by xi'anx
Karim Benabed, astrophysician
Posted in Statistics, Travel, University life with tags ABC, adaptive importance sampling, ANR, astronomy, Bayesian inference, Bayesian model comparison, CMB, cosmology, cycling, dark energy, evidence, gravitational lensing, IAP, Institut d'Astrophysique de Paris, Nuit de l'Astronomie, Planck experiment, PMC, population Monte Carlo, traffic accident on December 5, 2025 by xi'an
The astronomer and cosmologist Karim Benabed got killed on Wednesday in Paris. While cycling, run over by a truck-driver (with no further details at the moment). He was a senior research at IAP (Institut d’Astrophysique de Paris) and we actively collaborated together between 2005 and 2010 on an ANR project on efficient simulation methods for inferring cosmological parameters, based on PMC. And Bayesian model comparison. He was a very congenial person, very sharp in assimilating new methods and keen on exploring novel hypotheses. While we did not keep closely in touch, I would meet him now and then while visiting the IAP. Ironically, Darren Wraith, formerly a postdoc with him at IAP, was visiting me last week and we were reminiscing of that era as late as Saturday night over dinner… So sad (and also so absurd, a truck stopping the trajectory of someone managing to travel to the origins of the Universe). The above is a cartoon of him drawn during his cosmic microwave background presentation during the Nuit de l’Astronomie.
model uncertainty and missing data: an objective BAyesian perspective
Posted in Books, Statistics, Travel, University life with tags Arnold Zellner, Bayes factor, Bayesian Analysis, Bayesian model comparison, Bayesian predictive, Bayesian variable selection, deviance information criterion, DIC, Don Rubin, Florence Forbes, g-priors, Gilles Celeux, Haar measure, ignorability, improper priors, invariance, Jeffreys priors, linear regression, marginal likelihood, Mike Titterington, missing values, missing-at-random model, model uncertainty, objective Bayes, objective prior distribution, oracle, ozone dataset, reference prior, Rubin’s rules, Spain, time zones, webinar on September 16, 2025 by xi'an My Spanish and objective Bayesian friends Gonzalo García-Donato, María Eugenia Castellanos, Stefano Cabras, Alicia Quirós, and Anabel Forte wrote an fairly exciting paper in BA that is open to discussion (for a few more days), to be discussed on 05 November (4:00 PM UTC | 11:00 AM EST | 5:00 PM CET).
The interplay between missing data and model uncertainty—two classic statistical problems—leads to primary questions that we formally address from an objective Bayesian perspective. For the general regression problem, we discuss the probabilistic justification of Rubin’s rules applied to the usual components of Bayesian variable selection, arguing that prior predictive marginals should be central to the pursued methodology. In the regression settings, we explore the conditions of prior distributions that make the missing data mechanism ignorable, provided that it is missing at random or completely at random. Moreover, when comparing multiple linear models, we provide a complete methodology for dealing with special cases, such as variable selection or uncertainty regarding model errors. In numerous simulation experiments, we demonstrate that our method outperforms or equals others, in consistently producing results close to those obtained using the full dataset. In general, the difference increases with the percentage of missing data and the correlation between the variables used for imputation.
The so-called Rubin’s identity is simply the representation of the posterior probability of a model γ given the observed data x⁰, p(γ|x⁰), as the integrated posterior probability of a model given both observed and latent data, p(γ|x⁰, x¹), against the marginal of latent x¹ given observed x⁰. Since this marginal involves the probabilities p(γ|x⁰), this representation is not directly useful for a numerical implementation.
In this paper, missingness relates to some entries of either the covariates or the response variate. Which is less common but more realistic, especially if some covariates do not contribute to the response. (The missingness mechanism does not matter if the data is missing at random (à la Rubin). The computational solution (p9) is rather standard, simulating the missing variables given the observed variables. In my opinion, the elephant in the room is the super-delicate selection of a prior distribution on the missing covariates, as methinks this impacts in a considerable manner the actual value of the Bayes factor, hence the selection of the surviving model. (As a side remark, we are credited in Celeux et al. (2006) to have “extended DIC for missing data models or when missing data were present”, but our point was instead to point out the arbitrariness of the very definition of DIC in such contexts.)
“The standard Bayesian method for addressing the absence of prior information uses improper distributions. In estimation problems (the model is fixed), the impropriety of priors does not imply any additional difficulty as long as the posterior is proper” (p9)
The authors point out the well-known difficulty with improper priors but still resort to improper priors on the parameters shared by all models—which I dispute as being adequate, despite the arguments put forward on p15, right Haar measure or not—, while sticking to proper priors on the model-dependent parameters. Which unsurprisingly become Zellner’s g-priors. Or rather g’-priors, although the discussion seems to resolve into the (model-free) factor g’ being equal to 1 as for the g-priors. Again a strong term in the derivation of the Bayes factor.
machine-learning harmonic mean
Posted in Books, Statistics with tags Bayesian model comparison, diabetes, harmonic mean estimator, HPD region, importance sampling, kernel density estimator, Pima Indians on February 25, 2022 by xi'an In a recent arXival, Jason McEwen propose a resurrection of the “infamous” harmonic mean estimator. In Machine learning assisted Bayesian model comparison: learnt harmonic mean estimator, they propose to aim at the “optimal importance function”. The paper provides a fair coverage of the literature on that topic, incl. our 2009 paper with Darren Wraith (although I do not follow the criticism of using a uniform over an HPD region, esp. since one of the learnt targets is also a uniform over an hypersphere, presumably optimised in terms of the chosen parameterisation).
“…the learnt harmonic mean estimator, a variant of the original estimator that solves its large variance problem. This is achieved by interpreting the harmonic mean estimator as importance sampling and introducing a new target distribution (…) learned to approximate the optimal but inaccessible target, while minimising the variance of the resulting estimator. Since the estimator requires samples of the posterior only it is agnostic to the strategy used to generate posterior samples.”
The method thus builds upon Gelfand and Dey (1994) general proposal that is a form of inverse importance sampling since the numerator [the new target] is free while the denominator is the unnormalised posterior. The optimal target being the complete posterior (since it lead to a null variance), the authors propose to try to approximate this posterior by various means. (Note however that an almost Dirac mass at a value with positive posterior would work as well!, at least in principle…) as the sections on moment approximations sound rather standard (and assume the estimated variances are finite) while the reason for the inclusion of the Bayes factor approximation is rather unclear. However, I am rather skeptical at the proposals made therein towards approximating the posterior distribution, from a Gaussian mixture [for which parameterisation?] to KDEs, or worse ML tools like neural nets [not explored there, which makes one wonder about the title], as the estimands will prove very costly, and suffer from the curse of dimensionality (3 hours for d=2¹⁰…).The Pima Indian women’s diabetes dataset and its quasi-Normal posterior are used as a benchmark, meaning that James and Nicolas did not shout loud enough! And I find surprising that most examples include the original harmonic mean estimator despite its complete lack of trustworthiness.
Monte Carlo Markov chains
Posted in Books, Statistics, University life with tags Andrei Kolmogorov, Bayesian Analysis, Bayesian model comparison, book review, CHANCE, Gregor Mendel, iris data, irreducibility, JASA, Jeffreys priors, Kolmogorov axioms, Kolmogorov-Smirnov distance, MCMC, physics, population genetics, pot-pourri, recurrence, Richard Price, Ronald Fisher, Springer-Verlag, textbook, Thomas Bayes, W. Gosset on May 12, 2020 by xi'an
“Two major avenues are available for the assignment of probabilities. One is based on the repetition of the experiments a large number of times under the same conditions, and goes under the name of the frequentist or classical method. The other is based on a more theoretical knowledge of the experiment, but without the experimental requirement, and is referred to as the Bayesian approach.”
“The Bayesian probability is assigned based on a quantitative understanding of the nature of the experiment, and in accord with the Kolmogorov axioms. It is sometimes referred to as empirical probability, in recognition of the fact that sometimes the probability of an event is assigned based upon a practical knowledge of the experiment, although without the classical requirement of repeating the experiment for a large number of times. This method is named after the Rev. Thomas Bayes, who pioneered the development of the theory of probability.”
“The likelihood P(B/A) represents the probability of making the measurement B given that the model A is a correct description of the experiment.”
“…a uniform distribution is normally the logical assumption in the absence of other information.”
“The Gaussian distribution can be considered as a special case of the binomial, when the number of tries is sufficiently large.”
“This clearly does not mean that the Poisson distribution has no variance—in that case, it would not be a random variable!”
“The method of moments therefore returns unbiased estimates for the mean and variance of every distribution in the case of a large number of measurements.”
“The great advantage of the Gibbs sampler is the fact that the acceptance is 100 %, since there is no rejection of candidates for the Markov chain, unlike the case of the Metropolis–Hastings algorithm.”
Let me then point out (or just whine about!) the book using “statistical independence” for plain independence, the use of / rather than Jeffreys’ | for conditioning (and sometimes forgetting \ in some LaTeX formulas), the confusion between events and random variables, esp. when computing the posterior distribution, between models and parameter values, the reliance on discrete probability for continuous settings, as in the Markov chain chapter, confusing density and probability, using Mendel’s pea data without mentioning the unlikely fit to the expected values (or, as put more subtly by Fisher (1936), “the data of most, if not all, of the experiments have been falsified so as to agree closely with Mendel’s expectations”), presenting Fisher’s and Anderson’s Iris data [a motive for rejection when George was JASA editor!] as a “a new classic experiment”, mentioning Pearson but not Lee for the data in the 1903 Biometrika paper “On the laws of inheritance in man” (and woman!), and not accounting for the discrete nature of this data in the linear regression chapter, the three page derivation of the Gaussian distribution from a Taylor expansion of the Binomial pmf obtained by differentiating in the integer argument, spending endless pages on deriving standard properties of classical distributions, this appalling mess of adding over the conditioning atoms with no normalisation in a Poisson experiment
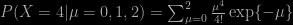
botching the proof of the CLT, which is treated before the Law of Large Numbers, restricting maximum likelihood estimation to the Gaussian and Poisson cases and muddling its meaning by discussing unbiasedness, confusing a drifted Poisson random variable with a drift on its parameter, as well as using the pmf of the Poisson to define an area under the curve (Fig. 5.2), sweeping the improperty of a constant prior under the carpet, defining a null hypothesis as a range of values for a summary statistic, no mention of Bayesian perspectives in the hypothesis testing, model comparison, and regression chapters, having one-dimensional case chapters followed by two-dimensional case chapters, reducing model comparison to the use of the Kolmogorov-Smirnov test, processing bootstrap and jackknife in the Monte Carlo chapter without a mention of importance sampling, stating recurrence results without assuming irreducibility, motivating MCMC by the intractability of the evidence, resorting to the term link to designate the current value of a Markov chain, incorporating the need for a prior distribution in a terrible description of the Metropolis-Hastings algorithm, including a discrete proof for its stationarity, spending many pages on early 1990’s MCMC convergence tests rather than discussing the adaptive scaling of proposal distributions, the inclusion of numerical tables [in a 2017 book] and turning Bayes (1763) into Bayes and Price (1763), or Student (1908) into Gosset (1908).
[Usual disclaimer about potential self-plagiarism: this post or an edited version of it could possibly appear later in my Books Review section in CHANCE. Unlikely, though!]


