 x
Archive for R package
ECMLE on CRAN
Posted in R, Statistics, University life with tags Bayesian model comparison, CRAN, ECMLE package, elliptical covering, github, HPD region, marginal likelihood, normalising constant, R, R package, statistical evidence on March 27, 2026 by xi'anx
mixture models [book review]
Posted in Books, Statistics, University life with tags book review, CHANCE, Dirichlet process Gaussian mixture, EM algorithm, Gibbs sampler, handbook of mixture analysis, hidden Markov models, hypothesis testing, identifiability, improper posteriors, improper priors, label switching, likelihood ratio, MAP estimators, mixture models, mixtures of distributions, parametric bootstrap, R, R package, reversible jump MCMC, semi-parametrics, spams, Statistical Science, unknown number of components on August 14, 2024 by xi'an Strangely enough, I became aware of this new book on mixtures through one of these annoying emails “Your work has been cited n times this week“… Mixture Models (Parametric, Semiparametric, and New Directions) by Weixin Yao and Sijia Wang got published by CRC Press earlier this year, within the Monographs on Statistics and Applied Probability green series (#175), and covers across 380 pages most aspects of mixture (and hidden Markov) estimation, if with strong emphasis on maximum likelihood estimation, while the new directions are unsurprisingly those pursued by the authors, namely robust and semi-parametric estimation, as well as model selection by testing.
An early warning about this book review is that I co-edited a Handbook of Mixture Analysis with my friends Sylvia Früwirth-Schnatter and Gilles Celeux a few years ago. I am therefore biased in what I would have included in a new book on the topic, the more because I find the available literature already plentiful, even though the early (1984) book of Titterington et al. that was my entry to the field may have become an historical reference. For instance, Finite Mixtures by McLachlan and Peel (2000) remains relevant, with similar emphasis on maximum likelihood and the EM algorithm, while Sylvia’s Finite Mixture and Markov Switching Models is still a reference to this day.
And an additional warning on me not being a massive fan of semi- and non-parametric estimation in this setting…
Preliminaries that may explain my limited enthusiasm about the book and its limited originality. Not that I found significant errors there (even though “improper priors [do not always] yield improper posteriors” [p.145] as we demonstrated in several papers), however, I had trouble with the uneven pace adopted by the authors that often skim some topics of importance while spending an inconsiderate amount of space on less relevant once. Some items get many bibliographical references, while others do not. For instance, EM receives a lion’s share (see, e..g, Sections 6.6 and 6.7). Or the 12 pages of proof in Chapter 10. Declination of sections into mixtures, mixtures of regressions, multivariate mixtures, hidden Markov models, and so on feels somewhat repetitive. This is particularly the case for the “mixture regression models” chapter.
The book also contains Bayesian entries, with a first introduction (p.105) in the discrete data chapter that precedes the short Bayesian chapter #4 (p.145), the same issue arising for related algorithms like Gibbs (p.107) that “estimate properties of the joint posterior” and MCMC (p.112). Which sort of erases the specificity of a Bayesian approach by reducing it to one item in the toolbox (with the wrong stress on MAP estimates). In this Bayesian chapter, MCMC validation is handled for discrete state spaces while applied in general spaces. The focus is mostly on relabelling for the following label switching chapter, albeit a large collection of methods are compared if not mentioned.
Handing an unknown number of components by hypothesis testing is supported in the next short chapter, although very little is said about reversible jump MCMC. And there is no general discussion on the consistency of these tests, in particular with bootstrap. Or at least on the regularity conditions they request. An puzzling paradox (p.191) is the existence of an unbounded Fisher information of an exponential mixture

when the weight π is the parameter (and close to 1).
High-dimensional mixtures in Chapter 8 are mostly handled by linear projections in smaller subspaces, which is natural given that they preserve the mixture structure but open a Pandora box of a wide range of proposed methods, again with little comparison available. Except in the R final section opposing several R functions on the same dataset (if unconclusively).
The semi-parametric chapters mention Dirichlet process priors, albeit briefly, but fail to relate to the recent works on using these when inferring about the number of components. Or failing to do so. There is also a very limited connection pointed out with machine learning but little can be gathered from the three page presentation (pp.308-310). These chapters also have significant overlap with the review paper of Xiang et al. (2019) in Statistical Science.
Most chapters end up with an R section, which usually reads as a quick demo of a related R package, like BayesLCA or our own mixtool. Hence not massively helpful beyond pointers to these packages. The numerical illustrations also are unevenly distributed between chapters, from nothing at all to four pages of small font tables on an MSE comparison between more or less robust approaches undertaken by Yu et al. (2020).
The above thus explains why I am not particularly excited about this bibliographical addition to the analysis of mixtures. It does offer a reference for researchers in the field by adding recent references and approaches to the existing books mentioned above, but I could not recommend it as a textbook (as suggested on p.xiii).
[Disclaimer about potential self-plagiarism: this post or an edited version may eventually appear in my Books Review section in CHANCE.]
operation precisely impossible
Posted in Books, Kids, R, University life with tags almost.unique(), arithmetics, bazar, brute force, CRAN, evolution tree, mathematical puzzle, OEIS sequence, R, R package, riddle, The Riddler, unique() on May 13, 2023 by xi'an Since the solution to the previous riddle from The Riddler on the maximum of different terms in the composed operation
a∅b∅c∅d∅e∅f
depending on the bracketing ordering and the meaning of each ∅ among one of the six elementary operations got posted today as 974,860, I got back to my R code to understand why it differed from my figures by two orders of magnitude and realised I was overly trusting the R function unique. As it was returning more “different” entries than it should have, especially when choosing the six starting numbers (a,…,f) as Uniform (0,1). Using integers instead led for instance to 946,558, which was not so far from the target. But still imprecise as to whether or not some entries had been counted several times. I mentioned the issue to Robin, who rose to the challenge and within minutes came up with using the R function almost.unique from the CRAN package bazar, then producing outcomes like 974,513, hence quite close to 974,860 for random initialisations!
learning base R [book review]
Posted in Books, Kids, Statistics, University life with tags Black-Scholes formula, book review, Brownian motion, CHANCE, complex numbers, directory, Eratosthenes, introductory textbooks, loops, matrix algebra, probability distribution, R, R package, R studio, Rmarkdown, simulation, Squid Games on February 26, 2022 by xi'an This second edition of an introductory R book was sent to me by the author for a potential CHANCE book review. As there are many (many) books in the same spirit, the main question behind my reading it (in one go) was on the novelty it brings. The topics Learning Base R covers are
- arithmetics with R
- data structures
- built-in and user-written R functions
- R utilities
- more data structures
- comparison and coercion
- lists and data frames
- resident R datasets
- R interface
- probability calculations in R
- R graphics
- R programming
- simulations
- statistical inference in R
- linear algebra
- use of R packages
within as many short chapters. The style is rather standard, that is, short paragraphs with mostly raw reproductions of line commands and their outcome. Sometimes a whole page long of code examples (if with comments). All in all I feel there are rather too few tables when compared with examples, at least for my own taste. The exercises are mostly short and, while they vary in depth, they show that the book is rather intended for students with some mathematical background (e.g., with a chapter on complex numbers and another one on linear algebra that do not seem immediately relevant for most intended readers). Or more than that, when considering one (of several) exercise (19.30) on the Black-Scholes process that mentions Brownian motion. Possibly less appealing for would-be statisticians.
I also wonder at the pedagogical choice of not including and involving more clearly graphical interfaces like R studio as students are usually not big fans of “old-style” [their wording not mine!] line command languages. For instance, the chapter on packages would have benefited from this perspective. Nothing on Rmarkdown either. Apparently nothing on handling big data, more advanced database manipulation, the related realistic dangers of memory freeze and compulsory reboot, the intricacies of managing different directories and earlier sessions, little on the urgency of avoiding loops (p.233) by vectorial programming, a paradoxically if function being introduced after ifelse, and again not that much on statistics (with density only occurring in exercises).The chapter on customising R graphics may possibly scare the intended reader when considering the all-in-one example of p.193! As we advance though the book, the more advanced examples often are fairly standard programming ones (found in other language manuals) like creating Fibonacci numbers, implementing Eratosthenes sieve, playing the Hanoi Tower game… (At least they remind me of examples read in the language manuals I read as a student.) The simulation chapter could have gone into the one (Chap. 19) on probability calculations, rather than superfluously redefining standard distributions. (Except when defining a random number as a uniformly random number (p.162).) This chapter also spends an unusual amount of space on linear congruencial pseudo-random generators, while missing to point out the trivia that the randu dataset mentioned twice earlier is actually an outcome from the infamous RANDU Fortran generator. The following section in that chapter is written in such a way that it may give the wrong impression that one can find the analytic solution from repeated Monte Carlo experiments and hence the error. Which is rarely the case, even in finite environments with rational expectations, as one usually does not know of which unit fraction the expectation should be a multiple of. (Remember the Squid Games paradox!) And no mention is made of the prescription of always returning an error estimate along with the numerical approximation. The statistics chapter is obviously more developed, with descriptive statistics, ecdf, but no bootrstap, a t.test curiously applied to the Michelson measurements of the speed of light (how could it be zero?!), ANOVA, regression handled via lm and glm, time series analysis by ARIMA models, which I hope will not be the sole exposure of readers to these concepts.
In conclusion, there is nothing critically wrong with this manual introducing R to newcomers and I would not mind having my undergraduate students reading it (rather than our shorter and home-made handout, polished along the years) before my first mathematical statistics lab. However I do not find it massively innovative in its presentation or choice of concept, even though the most advanced examples are not necessarily standard, and may not appeal to all categories of students.
[Disclaimer about potential self-plagiarism: this post or an edited version will eventually appear in my Book Review section in CHANCE.]
likelihood inference with no MLE
Posted in Books, R, Statistics with tags exponential families, maximum likelihood estimation, R package, rcdd, statistical inference on July 29, 2021 by xi'an“In a regular full discrete exponential family, the MLE for the canonical parameter does not exist when the observed value of the canonical statistic lies on the boundary of its convex support.”
Daniel Eck and Charlie Geyer just published an interesting and intriguing paper on running efficient inference for discrete exponential families when the MLE does not exist. As for instance in the case of a complete separation between 0’s and 1’s in a logistic regression model. Or more generally, when the estimated Fisher information matrix is singular. Not mentioning the Bayesian version, which remains a form of likelihood inference. The construction is based on a MLE that exists on an extended model, a notion which I had not heard previously. This model is defined as a limit of likelihood values
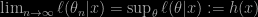
called the MLE distribution. Which remains a mystery to me, to some extent. Especially when this distribution is completely degenerate. Examples provided within the paper alas do not help, as they mostly serve as illustration for the associated rcdd R package. Intriguing, indeed!

