Archive for confidence sequence

e-values in Chennai

Posted in Books, pictures, Running, Statistics, Travel, University life with tags , , , , , , , , , , , , , , , , , , , on July 23, 2025 by xi'an

To recap, I thus attended the BIRS-CMI workshop 25w5482 at the Chennai Mathematical Institute, Navalur, Tamil Nadu, in early July, for being intrigued by the developments around the concept. And enjoyed the week, from partaking in the company of friendly and enthusiastic academics to the exposure of new views and concepts, mostly remote from mine’s. Recall that an e-value attached to an hypothesis H described as a collection of distributions is a non-negative random variable E with expectation less than 1 for E~Q and all Q ∈ H. When a stopping rule is involved, the e-value is extended into an e-process. (Beyond Aaditya Ramdas’ E-book, Ruodu Wang also wrote a “tiny” review.) Aaditya Ramdas recalled in his introduction of the workshop that e-values are fundamentally equivalent to p-values and confidence intervals. And that a confidence sequence is a sequence of confidence intervals that contains the true value for all time steps t’s with a probability of at least 1-α.

The talks reflected a general belief in α levels and in Neyman-Pearsonian likelihood ratio optimality in simple vs simple settings, considering extension for sequential analysis settings, anytime inference, universality under general alternatives, and connections with FDRs, incl. Benjamini & Hochberg solution, but pointed out a lack of middle ground between frequentists and Bayesians.

“e-values have a clear interpretation in terms of betting and are closely related to likelihood ratios and other Bayes factor. At the same time, e–values do not require prior distributions conditional on the null and alternative hypotheses”

Although David R. Bickel attempted a Bayesian version, using a marginal likelihood ratio within betting settings, that is an incoming American Statistician paper. I may have being missing some aspects due to a lack of sleep the night before (!), but I find the attempt resulting in a fairly unusual vision of Bayesian testing as either not depending on any parameter or on the opposite using a family of priors. I did not understand either the “criticism” that the predictive depends on the prior and felt that this representation was bending in a rather onsiderable way the Bayesian perspective towards achieving a certain degree of agreement with p– and e-value notions, to conclude that the Bayes factor is an e-value. (As an aside, this may be the first paper that cited our critical review of Aitkin! Similarly, Shubhada Agrawal mentioned Roger Farrell in his talk, with whom we wrote a complete class Annals paper in the late 1980’s.) Nikos Ignatiadis also explored Empirical Bayes e-values, while Ben Chugg gave a presentation (constrained) admissibility, albeit under type-I error constraints that makes Bayes infeasible and using Neyman-Pearsonian loss functions. On the last day, Peter Grünwald tried for some BFF cohesion with openings on e-posteriors, treating hypothesis testing losses symmetrically, defining it as an inverse of e-values but incorporating pseudo-posteriors of many flavours like confidence, inferential, and fiducial distributions. He also mentioned a Savage-Dickey version while using an arbitrary prior, which is also an e-value, but with upper & lower meanings, again with measure issues

Given the hosting of the workshop in the Chennai Mathematical Institute, which is quite far from the centre of town (much closer to Mahabalipuram!), I did not visit Chennai but enjoyed the South Indian cuisine (albeit missing some fierceness in the spices!) and local fruits from street stands, if being sorry I could not find cocoa pods from nearby Kerala.

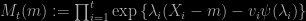
Estimating means of bounded random variables by betting

Posted in Books, Statistics, University life with tags , , , , , , , , , , , , , , , , , , , , , , , on April 9, 2023 by xi'an

Ian Waudby-Smith and Aaditya Ramdas are presenting next month a Read Paper to the Royal Statistical Society in London on constructing a conservative confidence interval on the mean of a bounded random variable. Here is an extended abstract from within the paper:

For each m ∈ [0, 1], we set up a “fair” multi-round game of statistician
against nature whose payoff rules are such that if the true mean happened
to equal m, then the statistician can neither gain nor lose wealth in
expectation (their wealth in the m-th game is a nonnegative martingale),
but if the mean is not m, then it is possible to bet smartly and make
money. Each round involves the statistician making a bet on the next
observation, nature revealing the observation and giving the appropriate
(positive or negative) payoff to the statistician. The statistician then plays
all these games (one for each m) in parallel, starting each with one unit of
wealth, and possibly using a different, adaptive, betting strategy in each.
The 1 − α confidence set at time t consists of all m 2 [0, 1] such that the
statistician’s money in the corresponding game has not crossed 1/α. The
true mean μ will be in this set with high probability.

I read the paper on the flight back from Venice and was impressed by its universality, especially for a non-asymptotic method, while finding the expository style somewhat unusual for Series B, with notions late into being defined if at all defined. As an aside, I also enjoyed the historical connection to Jean Ville‘s 1939 PhD thesis (examined by Borel, Fréchet—his advisor—and Garnier) on a critical examination of [von Mises’] Kollektive. (The story by Glenn Shafer of Ville’s life till the war is remarkable, with the de Beauvoir-Sartre couple making a surprising and rather unglorious appearance!). Himself inspired by a meeting with Wald while in Berlin. The paper remains quite allusive about Ville‘s contribution, though, while arguing about its advance respective to Ville’s work… The confidence intervals (and sequences) depend on a supermartingale construction of the form

M_t(m):=\prod_{i=1}^t \exp\left\{ \lambda_i(X_i-m)-v_i\psi(\lambda_i)\right\}

which allows for a universal coverage guarantee of the derived intervals (and can optimised in λ). As I am getting confused by that point about the overall purpose of the analysis, besides providing an efficient confidence construction, and am lacking in background about martingales, betting, and sequential testing, I will not contribute to the discussion. Especially since ChatGPT cannot help me much, with its main “criticisms” (which I managed to receive while in Italy, despite the Italian Government banning the chabot!)

However, there are also some potential limitations and challenges to this approach. One limitation is that the accuracy of the method is dependent on the quality of the prior distribution used to set the odds. If the prior distribution is poorly chosen, the resulting estimates may be inaccurate. Additionally, the method may not work well for more complex or high-dimensional problems, where there may not be a clear and intuitive way to set up the betting framework.

and

Another potential consequence is that the use of a betting framework could raise ethical concerns. For example, if the bets are placed on sensitive or controversial topics, such as medical research or political outcomes, there may be concerns about the potential for manipulation or bias in the betting markets. Additionally, the use of betting as a method for scientific or policy decision-making may raise questions about the appropriate role of gambling in these contexts.

being totally off the radar… (No prior involved, no real-life consequence for betting, no gambling.)