Archive for learning rate

Nature snapshots

Posted in Books, Kids, Mountains, pictures, Travel with tags , , , , , , , , , , , , , , , , , , , , , , , on September 19, 2024 by xi'an

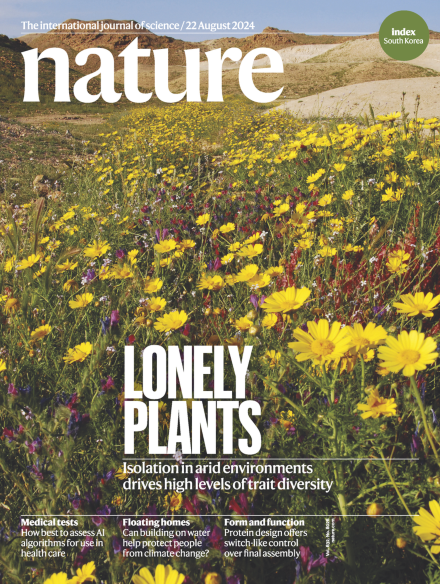
Some quick breakfast reads from the 22 August issue of Nature, beyond the nice pun in the cover title (which reads like Lonely Planet at first glance!) capturing a rare blooming of plants in the drylands of the Judaean Desert in 2015, discussing the higher diversity of plants in dry environments,

  • a tribune about the declining number of junior researchers in South Korea (with a supplementary Nature Index on its remarkable achievements), due to lower birth rates. The government is trying to make postdoc positions more attractive, to attract international students and postdocs. It has also signed with the EU to become an associate member of the Horizon Europe program, hence potentially benefitting of ERC grants.
  • looking for the hottest temperature compatible with humans, alas soon in a theatre near you… (With a heatwave chamber that was driven from Brisbane to Sydney!) I did not understand, though, how the limit of 31⁰C as the minimal temperature at which a healthy, young person would die after six hours of exposure. But agreed with the immediate benefits of skin-wetting, which I use almost constantly on hot days and nights.
  • the false good idea of wood pellets, reminding me of a freezing August in Christchurch back in 2005!, as pellets (and other biomass energy) generate more carbon than coal, favour deforestation, impacts the health of communities surrounding facilities, and takes decades to reach neutral outcomes.
  • another possibly false good idea, floating and sustainable settlements in coastal regions threatened by sea rises. Not only floating cities are expensive to build, but they are more exposed to extreme weather events, compete with the preservation of wetlands and mangroves, and cannot function without adapted infrastructure, from water and sewage treatment to means of transportation, and enough nearby services.
  • the ERROR project that pays for spotting mistakes in published papers, developed by the Universities of Bern and Leipzig. ERROR stands for Estimating the Reliability and Robustness of Research. At 2,500 Swiss francs per paper, this is hardly sustainable…
  • the problem of artificial neural networks losing plasticity in continual-learning settings and a potential solution via back-propagation.

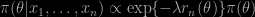
 

PAC-Bayesians

Posted in Books, Kids, pictures, Statistics, Travel, University life with tags , , , , , , , , , on September 22, 2015 by xi'an

Yesterday, I took part in the thesis defence of James Ridgway [soon to move to the University of Bristol[ at Université Paris-Dauphine. While I have already commented on his joint paper with Nicolas on the Pima Indians, I had not read in any depth another paper in the thesis, “On the properties of variational approximations of Gibbs posteriors” written jointly with Pierre Alquier and Nicolas Chopin.

PAC stands for probably approximately correct and starts with an empirical form of posterior, called the Gibbs posterior, where the log-likelihood is replaced with an empirical error

\pi(\theta|x_1,\ldots,x_n) \propto \exp\{-\lambda r_n(\theta)\}\pi(\theta)

that is rescaled by a factor λ. Factor that is called the learning rate, to be optimised as the (Kullback) closest  approximation to the true unknown distribution, by Peter Grünwald (2012) in his SafeBayes approach. In the paper of James, Pierre and Nicolas, there is no visible Bayesian perspective, since the pseudo-posterior is used to define a randomised estimator that achieves optimal oracle bounds. When λ is of order n. The purpose of the paper is rather to produce an efficient approximation to the Gibbs posterior, by using variational Bayes techniques. And to derive point estimators. With the added appeal that the approximation also achieves the oracle bounds. (Surprisingly, the authors do not leave the Pima Indians alone as they use this benchmark for a ranking model.) Since there is no discussion on the choice of the learning rate λ, as opposed to Bissiri et al. (2013) I discussed around Bayes.250, I have difficulties perceiving the possible impact of this representation on Bayesian analysis. Except maybe as an ABC device, as suggested by Christophe Andrieu.