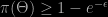Archive for Kullback-Leibler divergence

a novel discrepancy measure

Posted in Statistics, University life with tags , , , , , on June 1, 2025 by xi'an

My friend EJ Wagenmakers, along with his colleague  Raoul Grasman, have proposed a novel measure of discrepancy between two distributions that they formulate through a basic Bayesian lens as an expected posterior probability, written as

D_{\mathrm EP}(f||g) = \int_{\mathfrak X} \frac{f(x)}{f(x)+g(x)}f(x)\,\text dx

(with no priors harmed in the process!) in case both distributions are absolutely continuous wrt a common dominating measure, with densities f and g. Which I have not met before. This discrepancy has nicer properties than Kullback-Leibler in that it is symmetric, that

D_{\mathrm EP}(f||g) = \int_{\mathfrak X}\frac{1}{f(x)^{-1}+g(x)^{-1}}\frac{f(x)}{g(x)}\,\text dx

does not require absolute continuity, and suffers less from tail influence and from asymmetric convergence speeds between null and alternative. From a truly Bayesian perspective, comparing two posterior predictive densities this way is less appealing since they are not available in closed form, but the posterior probability in favour of model f can be replaced with a Monte Carlo estimate.

venISBA⁴⁻

Posted in Books, pictures, Statistics, Travel, University life with tags , , , , , , , , , , , , , , , , , , , , , , , on July 8, 2024 by xi'an

As I was released all of a sudden from the Ospedale Civile di Venezia around noon, I managed to attend the last session of ISBA 2024 (after stopping by my airbnb for an emergency coffee next to the hospital and stopping for showering, changing clothes, and eating something more substantial than the contents of IV bags).

My first of these last talks was about coresets by Trevor Campbell, for reducing sample sizes while keeping the likelihood roughly the same (and making me wondering if possibly getting some privacy on the side??) Original algorithm almost completely blind to the data, but a new version by subsample-optimize (KL distance to the posterior) version bringing huge improvements (although I missed the practical details on how the algorithm is reaching this minimum), namely a KL distance of order O(1), i.e., not growing in the sample size. Then, in the same session, a talk by Aikihiko Nakamura on mixing and PDMP, resulting in the novel bouncy Hamiltonian dynamics, which proves time reversible and volume preserving, with no U turns and the time within a given general Hamiltonian value being itself generated w/o rejection. (I am quite sorry to have missed other PDMP talks during the conference, eg, Paul Fearnhead’s, as well as the last poster session…) And I finally jumped rooms to listen to Sam Power on hybrid slice sampling with an MCMC extension to avoid simulating from the Uniform conditional. Reminding me of nested sampling, which also faces this difficulty of sampling from a possibly complex set. This was the end of a wonderful (if shortened by my personal issue) meeting. Next round, see you in Nagoya, Japan (on the Tōkaidō road!).


As a final word about this ISBA 2024 conference in Ca’Foscari, on many levels, I want to most warmly thank my friend Roberto Casarin for his investment and dedication for making the event running so efficiently, in an ideal environment for a meeting of this (800+) size that kept to the Aristotelian unities, especially keeping people together on a unique site without feeling crowded (and very few falling in a Venice canal). And many thanks as well to the local organisers (discounting my nominal inclusion in that group!), the Ca’Foscari staff, and all the students involved in the event!

simulation as optimization [by kernel gradient descent]

Posted in Books, pictures, Statistics, University life with tags , , , , , , , , , , , , , , , , , , , , , , , , on April 13, 2024 by xi'an

Yesterday, which proved an unseasonal bright, warm, day, I biked (with a new wheel!) to the east of Paris—in the Gare de Lyon district where I lived for three years in the 1980’s—to attend a Mokaplan seminar at INRIA Paris, where Anna Korba (CREST, to which I am also affiliated) talked about sampling through optimization of discrepancies.
This proved a most formative hour as I had not seen this perspective earlier (or possibly had forgotten about it). Except through some of the talks at the Flatiron Institute on Transport, Diffusions, and Sampling last year. Incl. Marilou Gabrié’s and Arnaud Doucet’s.
The concept behind remains attractive to me, at least conceptually, since it consists in approximating the target distribution, known up to a constant (a setting I have always felt standard simulation techniques was not exploiting to the maximum) or through a sample (a setting less convincing since the sample from the target is already there), via a sequence of (particle approximated) distributions when using the discrepancy between the current distribution and the target or gradient thereof to move the particles. (With no randomness in the Kernel Stein Discrepancy Descent algorithm.)
Ana Korba spoke about practically running the algorithm, as well as about convexity properties and some convergence results (with mixed performances for the Stein kernel, as opposed to SVGD). I remain definitely curious about the method like the (ergodic) distribution of the endpoints, the actual gain against an MCMC sample when accounting for computing time, the improvement above the empirical distribution when using a sample from π and its ecdf as the substitute for π, and the meaning of an error estimation in this context.

“exponential convergence (of the KL) for the SVGD gradient flow does not hold whenever π has exponential tails and the derivatives of ∇ log π and k grow at most at a polynomial rate”

Bayesian differential privacy for free?

Posted in Books, pictures, Statistics with tags , , , , , , , , , , , , on September 24, 2023 by xi'an

“We are interested in the question of how we can build differentially-private algorithms within the Bayesian framework. More precisely, we examine when the choice of prior is sufficient to guarantee differential privacy for decisions that are derived from the posterior distribution (…) we show that the Bayesian statistician’s choice of prior distribution ensures a base level of data privacy through the posterior distribution; the statistician can safely respond to external queries using samples from the posterior.”

Recently I came across this 2016 JMLR paper of Christos Dimitrakakis et al. on “how Bayesian inference itself can be used directly to provide private access to data, with no modification.” Which comes as a surprise since it implies that Bayesian sampling would be enough, per se, to keep both the data private and the information it conveys available. The main assumption on which this result is based is one of Lipschitz continuity of the model density, namely that, for a specific (pseudo-)distance ρ

|\log f(x|\theta)-\log f(y|\theta)|\le L\rho(x,y)

uniformly in θ over a set Θ with enough prior mass

\pi(\Theta)\ge 1-e^{-\epsilon}

for an ε>0. In this case, the Kullback-Leibler divergence between the posteriors π(θ|x) and π(θ|y) is bounded by a constant times ρ(x,y). (The constant being 2L when Θ is the entire parameter space.) This condition ensures differential privacy on the posterior distribution (and even more on the associated MCMC sample). More precisely, (2L,0)-differentially private in the case Θ is the entire parameter space. While there is an efficiency issue linked with the result since the bound L being set by the model and hence immovable, this remains a fundamental result for the field (as shown by its high number of citations).

learning optimal summary statistics

Posted in Books, pictures, Statistics with tags , , , , , , , , , on July 27, 2022 by xi'an

“Despite the pursuit of the holy grail of sufficient statistics, most applications will have to settle for the weakest concept of optimal statistics.”Quiz #1: How does Bayes sufficiency [which preserves the posterior density] differ from sufficiency [which preserves the likelihood function]?

Quiz #2: How does Fisher-information sufficiency [which preserves the information matrix] differ from standard sufficiency [which preserves the likelihood function]?

Read a recent arXival by Till Hoffmann and Jukka-Pekka Onnela that I frankly found most puzzling… Maybe due to the Norman train where I was traveling being particularly noisy.

The argument in the paper is to find a summary statistic that minimises the [empirical] expected posterior entropy, which equivalently means minimising the expected Kullback-Leibler distance to the full posterior.  And maximizing the mutual information between parameters θ and summaries t(.). And maximizing the expected surprise. Which obviously requires breaking the sample into iid components and hence considering the gain brought by a specific transform of a single observation. The paper also contains a long comparison with other criteria for choosing summaries.

“Minimizing the posterior entropy would discard the sufficient statistic t such that the posterior is equal to the prior–we have not learned anything from the data.”

Furthermore, the expected aspect of the criterion takes us away from a proper Bayes analysis (and exhibits artifacts as the one above), which somehow makes me question the relevance of comparing entropies under different distributions. It took me a long while to realise that the collection of summaries was set by the user and quite limited. Like a neural network representation of the posterior mean. And the intractable posterior is further approximated by a closed-form function of the parameter θ and of the summary t(.). Using there a neural density estimator. Or a mixture density network.