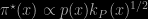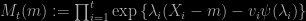Archive for Series B

robust simulation-based inference

Posted in Books, pictures, Statistics, University life with tags , , , , , , , , , , , , , , on March 7, 2026 by xi'an

This new arXival by Lorenzo Tomaselli, Valérie Ventura, and Larry Wasserman (from CMU) considers simulation-based inference under model misspecification (as we did for ABC in our 2020 Series B paper). Which is almost always the case. In the paper, SBI is defined as producing N parameters and N samples from the prior and the corresponding sampling distribution, respectively, and then doubling the resulting samples by permuting at random the parameters θ. This means that the second half is distributed from the product of the prior and of the marginal, hence that the classification odds ratio is equal to the likelihood, hence providing an estimation method (andlikelihood trick) à la Geyer. From this estimate, an ABC p-value can be derived, but it is incorrect as such when the model is misspecified. Hence the use of the Hellinger discrepancy, the power divergence and the kernel distance (or MMD) as alternatives to the misspecified MLE.

The paper then expands on approximating density ratios by virtue of a reproducing kernel Hilbert space, using a Gaussian kernel. (With a nice remark on requiring only one single ratio estimator for all values of θ, albeit in the joint space.) And focus on a studentized MMD estimator (à la e-value) to build a confidence set that remains valid under model misspecification. And without regularity assumptions.

Another approach is further explored, based on exponential tilting—of which I am not a great fan, from being highly dependent on the choice of the pseudo-sufficient statistic to require an intractable normalising constant, to requiring an extra optimization, even though I appreciate the mathematical appeal of the construct. Which seems to require a sample simulation for each value of θ at the learning stage, albeit relying on the same likelihood trick. The appropriateness of the tilting can be tested by a goodness of fit test tailored for the SBI structure, which sounds rather greedy in the required simulations. 

Besides the g-and-k distribution example (which, as pointed out several times on the ‘Og, is not intractable, strictly speaking!), the paper studies a mixture example, despite Larry dubbing them as evil as tequila a long while ago! (The paper also offers a section called accoutrements, which is my first encounter with this use of the term, usually found in medieval contexts!)

Note that Larry will present the paper at the OWABI webinar next 25 March!

Skew-symmetric approximations of posterior

Posted in Statistics with tags , , , , , , , on February 26, 2026 by xi'an

Botond Szabó gave a BNP webinar last week on the recent paper he wrote with Bocconni colleagues Francesco Pozza and Daniele Durante, to appear in Series B. Which studies the impact of using skew-symmetric approximations of posterior distributions. Skew-symmetric distributions are easy to simulate, either by accept-reject or by exploiting the cdf x pdf structure and the symmetry in the pdf. The Bernstein-von Mises theorem can be expanded to this case, although I am not certain what this means! The main theoretical result is a gain in the magnitude of the approximation, eg in KL, which I did not expected. With questions about the choice of the cdf (which can be automatised when the original posterior is available or when a closed-form approximation replaces it) and of the symmetry point ξ for complex models (which seems to be the MAP by default.) and of the impact on marginal likelihood approximations (if it makes any sense).

miXtures on arXiv

Posted in Books, Statistics, University life with tags , , , , , , , , , , , , , , , , , , , , on February 5, 2025 by xi'an

A paper about Bayesian inference on mixtures was posted on arXiv last week, as of 13 Jan 2025.  Fast sampling and model selection for Bayesian mixture models, by M. E. J. Newman is based on the notion that (genuine) parameters of a mixture model can be marginalized out when using conjugate priors. This is something that we pointed out quite a while ago, in a 1999 paper with George and Marty, which was devised in a long ride from Baltimore to Cornell after JSM 1999, and again in the 2002 Series B perfect sampling paper with George, Kerrie and Mike. (Also written in 1999.) And marginal likelihood can furthermore be approximated along this way as discussed in the more recent papers Bayesian Inference on Mixtures of Distributions with Kate, Kerrie & Jean-Michel, as well as Approximating the marginal likelihood in mixture models with Jean-Michel.

“Standard mixture models, as commonly formulated, also suffer from a technical, but important, difficulty: the existence of empty components. In many models (…) the number of observations in a component can be zero. Arguably this is acceptable for a model with a fixed number of components, but when the number of components is a free random variable it causes ambiguity, because a given division of observations into components can be represented in more than one way in the model. For instance, we could divide observations into two components, or we could divide them into three components, one of which is empty. This in turn creates difficulties when estimating the number of components—do we have two components or three?”

A very puzzling perspective, imho, since potentially empty components are inherent to (both finite and infinite) mixture models with connected issues of prohibiting some improper priors (if not all) and non-identifiability, including non-identifiability of the number of empty components (which remains random conditional on the data!), but different numbers of components lead to different models and their comparison is handled straightforwardly by a Bayesian analysis.

The author then proceeds to “prohibit empty components” [as a prior choice ?] as we did in the original (!) Gibbs sampler for mixtures in 1990 (published in 1994 in Series B!), seeking posterior properness, a trick later validated by Larry Wasserman (in again 1999, the year of mixtures!). Who called the construct the combination of a fixed prior and of a pseudo-likelihood, correctly imho (as the data dependent part is not properly normalised by a function of the parameters), rather than a prior choice. (The very one who stated that “mixtures, like tequila, are evil and should be avoided“.)

From there, the modelling is rather standard, with an arbitrary prior on k, number of components, a random partition model that prohibits empty components, even though the constraint could be more stringent depending on the number of parameters of a given component and the degree of improperness of the prior, as in our 1990 Series B paper. (Impropriety is not discussed in the paper.) Bayesian inference on k is based on the simulated (pseudo-)posterior. The choice therein as the estimated clustering is the most frequent partition (consensus clustering), connected to our proposal of (again!) 1999 with Merrilee and Gilles. While the estimated mixture is not explicited. The approach is assessed as running at an O(k) cost, with no parallel in terms of the data size n, even though the examples include a 59,946 dataset. One notable algorithmic trick when moving k is in selecting a component at random first rather than an observation index.

Some minor issues: detailed balance indicated as required for convergence (p14), label switching is called component switching (p5), higher acceptance rate indicated as meaning improved performances (p7)

optimal importance sampling

Posted in Books, pictures, Statistics, University life with tags , , , , , , , , on May 31, 2023 by xi'an

In Stein Π-Importance Sampling, Congye Wang et al. (mostly from Newcastle, UK) build an MCMC scheme with invariant distribution Π targeting a distribution P, showing that the optimal solution (in terms of a discrepancy) differs from P when the chain is Stein-sampled, e..g. via kernel discrepancies. In terms of densities, the solution is

\pi^\star(x)\propto p(x)k_P(x)^{1/2}

the correction involving the root of a Stein kernel, introduced by Oates, Girolami, and Chopin in their 2017 Series B Read Paper. This is rather paradoxical, even though the outcome does depend on the divergence criterion. Most intriguing!!!

Estimating means of bounded random variables by betting

Posted in Books, Statistics, University life with tags , , , , , , , , , , , , , , , , , , , , , , , on April 9, 2023 by xi'an

Ian Waudby-Smith and Aaditya Ramdas are presenting next month a Read Paper to the Royal Statistical Society in London on constructing a conservative confidence interval on the mean of a bounded random variable. Here is an extended abstract from within the paper:

For each m ∈ [0, 1], we set up a “fair” multi-round game of statistician
against nature whose payoff rules are such that if the true mean happened
to equal m, then the statistician can neither gain nor lose wealth in
expectation (their wealth in the m-th game is a nonnegative martingale),
but if the mean is not m, then it is possible to bet smartly and make
money. Each round involves the statistician making a bet on the next
observation, nature revealing the observation and giving the appropriate
(positive or negative) payoff to the statistician. The statistician then plays
all these games (one for each m) in parallel, starting each with one unit of
wealth, and possibly using a different, adaptive, betting strategy in each.
The 1 − α confidence set at time t consists of all m 2 [0, 1] such that the
statistician’s money in the corresponding game has not crossed 1/α. The
true mean μ will be in this set with high probability.

I read the paper on the flight back from Venice and was impressed by its universality, especially for a non-asymptotic method, while finding the expository style somewhat unusual for Series B, with notions late into being defined if at all defined. As an aside, I also enjoyed the historical connection to Jean Ville‘s 1939 PhD thesis (examined by Borel, Fréchet—his advisor—and Garnier) on a critical examination of [von Mises’] Kollektive. (The story by Glenn Shafer of Ville’s life till the war is remarkable, with the de Beauvoir-Sartre couple making a surprising and rather unglorious appearance!). Himself inspired by a meeting with Wald while in Berlin. The paper remains quite allusive about Ville‘s contribution, though, while arguing about its advance respective to Ville’s work… The confidence intervals (and sequences) depend on a supermartingale construction of the form

M_t(m):=\prod_{i=1}^t \exp\left\{ \lambda_i(X_i-m)-v_i\psi(\lambda_i)\right\}

which allows for a universal coverage guarantee of the derived intervals (and can optimised in λ). As I am getting confused by that point about the overall purpose of the analysis, besides providing an efficient confidence construction, and am lacking in background about martingales, betting, and sequential testing, I will not contribute to the discussion. Especially since ChatGPT cannot help me much, with its main “criticisms” (which I managed to receive while in Italy, despite the Italian Government banning the chabot!)

However, there are also some potential limitations and challenges to this approach. One limitation is that the accuracy of the method is dependent on the quality of the prior distribution used to set the odds. If the prior distribution is poorly chosen, the resulting estimates may be inaccurate. Additionally, the method may not work well for more complex or high-dimensional problems, where there may not be a clear and intuitive way to set up the betting framework.

and

Another potential consequence is that the use of a betting framework could raise ethical concerns. For example, if the bets are placed on sensitive or controversial topics, such as medical research or political outcomes, there may be concerns about the potential for manipulation or bias in the betting markets. Additionally, the use of betting as a method for scientific or policy decision-making may raise questions about the appropriate role of gambling in these contexts.

being totally off the radar… (No prior involved, no real-life consequence for betting, no gambling.)